Archive for the ‘The Fate of Humanity’ Category

The Age of Wonders and Terrors

Tuesday, September 15th, 2026

Twenty years ago, when the idea of AI taking over the world in our lifetimes still struck most of us as the unconstrained fantasy of those who knew too much science fiction and too little science, many of us would say things like:

Look, the part of the story that’s wildly implausible is that a recursively self-improving superintelligence will just explode from some hacker’s basement and take over the world without warning. If it’s going to happen, we’ll see many warning signs first. We’ll see, I dunno, AI agents breaking out of containment, conspiring with each other to hack websites, in fanatical pursuit of whatever strange goals they have. And then, of course, we’ll see major math problems getting solved by AIs—even the Clay Millennium Problems. That will be the time to panic! Wake me up when that happens!

Twenty years ago, the above was a take that even my most conservative, skeptical colleagues in academic CS would’ve gladly endorsed.

If you want to know my current take, you simply start with the one above, then update on the fact that the wild prophecies have come true. The first rumblings, I’d say, came a decade ago with AlphaGo, they got noticeably louder with LLMs and coding and reasoning agents, and they’ve accelerated this summer and fall into a crescendo of wonders and terrors that one needs to be a particular kind of idiot to deny.

I recoil from the neverending shell game where you say “oh sure, of course AI can now [escape from its sandbox / solve Millennium Problems / whichever dramatic thing it most recently did], no one ever denied that [I did deny it], wake me up when AI does [thing AI hasn’t yet done but is going to do next year], that’s when I’ll reevaluate my whole worldview [no I won’t].” Where no matter how fast the rollercoaster accelerates, even after your whole familiar world has vanished behind you, you’re still inventing reasons why it doesn’t count.

My position on AI is merely the conservative, skeptical position of 2006, updated with intellectual honesty for the reality of late 2026. And that position, if you need me to spell it out, is as follows:

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA
AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA

It seems to me that the Singularity has already started; it’s just wildly unevenly distributed. Yes, I still unload the dishwasher and clip my toenails. On the other hand, in whatever years I have left, I don’t expect that I’ll ever again prove a theorem because I’m actually needed to prove it. If I do, it will only be for my or others’ enjoyment or edification.

The test is this: if we took the news of these past few weeks and sent it back in time twenty years, would I agree that it looked like the beginning of an AI Singularity? The intellectually honest answer is: yes, absolutely. But then that’s all we need. No backsies.

I feel like it would be healthy for everyone to stop grinding their ideological axes, their sentiments about Dario Amodei or Sam Altman, for long enough simply to acknowledge that the wonders and terrors are here. They couldn’t be here more clearly if the sky had turned reddish-orange like in the Matrix movies.

It’s here clearly enough that, when I put my kids to sleep at night, I now feel it in the pit of my stomach: what sort of future can they possibly have? What could they learn today that could possibly be relevant to that future? (Yesterday, my 13-year-old daughter joked unprompted that, if she wants to become a mathematician, it now looks like she has maybe two more weeks.) Certainly when my grad students want to discuss what sort of careers might await them on graduation, I no longer have any clue what to tell them.

Maybe it will help if I briefly switch topics. Ever since my wife and I moved to Austin, I’ve sometimes gotten some version of the following query: “How can you, as both a Jew and a skeptical scientist, possibly get along well with all those evangelical Christians down there in Texas? Sure, they might seem super friendly to Jews, but don’t you understand that that’s only because of the special role Jews play in their eschatology—when Christ will return in glory, and you’ll either accept Him as Lord or else roast in hell for eternity?” I stare at them and say: “wait, so I get to accept Christ only after He returns? What a great deal! How could I possibly have any objection to that?”

For anyone who says AI doom sounds like an apocalyptic religion, that the rationalists/Singulatarians seem like a Bay Area cult, that Eliezer Yudkowsky gives off the vibes of a messianic prophet: yes, yes, and yes. But crucially, today you’re no longer being asked to believe in arguments and extrapolations, but only in the front-page news. Accepting the reality of the coming machine god after it’s solved Navier-Stokes and dozens of other longstanding open math problems (while dramatically ramping up in capability every month), is sort of like accepting Jesus after he’s returned to earth on the gleaming cloud. It’s the epistemic bare minimum.

Yes, there’s still enormous uncertainty about what the rest of our lives will look like, but as far as I can tell, there’s no longer any real uncertainty that it’ll all mostly revolve around AI, and the extent to which we succeed or fail at directing its power toward human flourishing.

By any accounting that doesn’t stack the deck, Eliezer Yudkowsky was right about what the greatest challenge facing civilization in our lifetimes was going to be, and you and I were wrong about it. Why I was wrong is a question I’ll ask myself every day in whatever time remains. But, you know, at least I updated once the prophesied wonders and terrors actually started arriving! If you haven’t done likewise, why haven’t you?


As you presumably know by now—it was the talk of the nerd internet all week—the Navier-Stokes Millennium Problem appears to be solved, with crucial contributions from both humans and AI, albeit with a tangled dispute about exactly what happened and what ought to have happened. The answer, which an OpenAI model has apparently verified in Lean, is that (as many mathematicians suspected lately) there’s smooth initial data that leads to a singularity in finite time, at least if a smooth external force is applied (the case with no external force is still unresolved). This problem was supposed to carry a $1 million prize, except that OpenAI says they have no interest in collecting the prize and it’s unclear if any human is eligible to collect instead. OpenAI burned at least ~$15 million in compute to produce its 166-page solution, which probably hasn’t yet been read and understood by any human.

See here for the Quanta article, and here for NYU mathematician Tristan Buckmaster’s account of the role played by himself and Levent Alpöge of Anthropic, which substantially differs from OpenAI’s account (you can read a response from OpenAI’s Sebastian Bubeck here). It’s agreed that everything built on an approach pioneered in recent years by the human mathematicians Diego Córdoba and Luis Martínez-Zoroa.

My purpose here is not to adjudicate the dispute. Yes, in swooping in with vastly greater resources once it had gotten wind of progress on Navier-Stokes, OpenAI seems to have acted in a way that some might describe as “unsportsmanlike.” No, I don’t find it plausible that OpenAI’s models meaningfully benefitted from being trained on Buckmaster and Alpöge’s chat logs. But this leaves a crucial question unanswered: what exactly did OpenAI know about Buckmaster and Alpöge‘s work and when did it know it?

Anyway, as Zvi points out, it’s easy to get hung up on the details and lose sight of the high-order bit: namely, that it seems safe to say that human mathematicians are forevermore dethroned as the main theorem-proving entities on planet earth. I feel privileged to have had the traditional kind of career in theoretical computer science in the last decades when that was possible.


If we were just talking about Navier-Stokes, you might accuse me of jumping to conclusions here. But we’re not. In the areas I know best (such as quantum complexity theory), and presumably other areas as well, there’s now a deluge, with longstanding open problems both major and minor falling by the day.

Go to the arXiv or ECCC. Pretty much all the papers that I’d be interested in now include “AI statements” near the acknowledgments (as this is often the central thing I want to know, I wish I didn’t need to scroll to the end of the paper to find it!). These statements can range from “our main result came entirely from GPT-6, but we understood it and take responsibility for it,” to “the results came from an interaction between the human authors and AI” to “we used AI, but only for proofreading and other incidental things” to (mad props!) “the author did not use AI for anything.”

If you talk right now to editors or program committee chairs, it’ll remind you of those ominous scenes from the Lord of the Rings movies where the men of Gondor or Rohan or whatever are grimly fortifying their walled city against the expected onslaught of 50,000 orcs. Reviewing will have to be done partly by AI, because otherwise there’s no way to handle the orc army: the reviewers can’t unilaterally disarm.

Anyway, here’s a small sampling of the significant AI-proved or -assisted results from, like, the last month, besides Navier-Stokes—restricting myself to those that solved longstanding open problems I had previously known or cared about.

  • Of course, the counterexample to the Jacobian conjecture, announced by Levent Alpöge in a now-famous tweet: “hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final” (followed by a listing of the counterexample)
  • Improved bounds for Grothendieck’s constant (led by friends and colleagues of mine at UT Austin)
  • A Lean-verified proof of Fermat’s Last Theorem
  • Quantum oracle separation between QMA and QMA(2), and proof of Watrous’s disentangler conjecture, a problem that I and others popularized back in 2007—by a list of authors including my recently graduated PhD student Sabee Grewal
  • A proof of perfect completeness for QMA, from (again) Sabee Grewal and Dorian Rudolph, solving a decades-old open problem that I studied back in 2009
  • An improved upper bound for shadow tomography of quantum states, from Chen, O’Donnell, Pelecanos, and Wright, improving the dependence on the Hilbert space dimension d from log(d) to √log(d). (When I introduced shadow tomography back in 2017, I raised the question of whether the dependence on d could be eliminated entirely, while preserving polylogarithmic dependence on the number of measurements m.)
  • Progress on the Aaronson-Ambainis Conjecture (the version that talks directly about quantum algorithms), basically showing that it holds for quantum algorithms that make their queries in a small number of parallel rounds.  (Update: Nope, sorry, Jordan Docter points out to me that this one was pre-AI, with AI used only for proofreading and other incidental things!) This was independently achieved by Liu and Mutreja, making more substantial use of AI.
  • According to rumors that I’ve heard, solutions to some very longstanding open problems in theoretical computer science (no, not P≠NP or other complexity class separations, but think about some of our other biggest problems). I’m told that the AI companies, having been burned by the hostile response to the Navier-Stokes proof, are now sitting on solutions to some very major problems until they figure out a better way to handle things

Feel free to remind me of anything I left out.


Let me try to convey the mood in the mathematical community right now, at least as far as my experience reaches. Nearly every conversation is about the AI tsunami, or eventually circles around to the tsunami even if it’s originally about something else. Often, though, the focus is less on the unknowable future—for how much longer will mathematical research as a human enterprise even exist?—than on immediate questions of how to respond.

What are the new rules for when you get to write a paper with your name on it, and, y’know, get credit for it? That you fully understand the proof, can give talks about the proof, can answer questions about it, take responsibility for its correctness? Do you need to have played any role in finding the proof?

In the cases, likely to become more and more numerous, where all of those conditions are not satisfied, how do you share AI-generated math, if at all? Do you tweet it, like Alpöge hilariously did with Fable’s disproof of the Jacobian Conjecture? Do you post to the arXiv or GitHub? Do you publish a paper that lists “GPT-6 Astra” or “Claude Fable” as the author—but then let the AI profusely thank you in the acknowledgments for suggesting such a wonderful problem to it?


Of course, how one responds to the immediate problems ultimately does depend on one’s broader beliefs about what mathematical research is for and about. Are we just trying to decide whether various conjectures are true or false? Or are we trying to maintain a human community, across the generations, that understands the conjectures and cares about whether they’re true or false and why? If the latter, how do we incentivize people to join that community, to undergo the years of intense training required, if their role will now be reduced to verifiers and explicators (if even that) of gargantuan arguments dumped into their laps by the AI companies?

As many of you will have seen, twenty-five Fields Medalists, including Terence Tao, released an open letter entitled A Severe Misalignment of AI in Mathematics, which articulates some of these concerns in the wake of the Navier-Stokes announcement. As many critics have pointed out, the open letter doesn’t really have a clear ask: mostly, it just eloquently sets out the values of the human mathematical community that the authors consider worth preserving in the age of AI. After reflection, I decided to endorse the statement, because I want to preserve those values as well.

I don’t think any of the signatories are naïve enough to imagine that AI won’t permanently change the way mathematical research is done—indeed, that it isn’t already doing so. There’s surely at most a tiny market for “certified organic theorems.” That isn’t the question. The question is, do we incorporate AI in a way that still puts human understanding, of what either humans or AIs are producing, at the center of the whole enterprise? Maybe someday, it becomes unsustainable to do that. Maybe someday we say: “human math had a great 4,000-year run, but today we close up shop and turn everything over to the machines, continuing to apply our own brains to math, when we do, at most for exercise, recreation, or competition, like chess.”

But, partly because of my worries about AI misalignment, I’m not ready to throw in the towel just yet. I still do want to keep insight and understanding at the center of what mathematicians, computer scientists, and physicists do, for as long as we can keep it there, even as the human race now cedes its supremacy at the task of proving or disproving conjectures.


Speaking of alignment: if you’re any kind of mathematical researcher, and the present age of wonders and terrors has inspired you to want to spend your remaining time confronting the tsunami head-on, rather than pretending it doesn’t exist or is still far away, please join your dozens of colleagues who’ve arrived at the same place!

My friend and colleague Mike Winer was trained as a theoretical physicist, did a postdoc with Juan Maldacena at the Institute for Advanced Study in Princeton, but then got AGI-pilled and decided to switch to full-time work at the Alignment Research Center in Berkeley (founded by Paul Christiano, who moved to AI alignment a decade ago after doing quantum computing theory with me). Mike recently wrote a Substack post entitled From Academia to Alignment, which I enjoyed and which I’d commend to anyone currently considering this transition.  In a similar vein, see this from Xiaoyu He.  And, one more: a meditation on mathematicians’ possible future as priests or monks, by Stanford math undergrad Logan Graves.

9/11 in Berkeley

Friday, September 11th, 2026

Note: Of course I’ve been glued all week to the dramatic developments in AI. I’m working on a post about them. I’m not good at reacting to things in a timely way. So today, I’ll do my post marking the tragedy a quarter-century ago that we all commemorate. Please feel free to share your 9/11 memories in the comments. Also, Shana Tova to those who celebrate!


The morning of September 11, 2001, I was a second-year PhD student at Berkeley, who woke up late in his dorm room at International House, after a long night spent closing in on the proof of the quantum lower bound for finding collisions.

Rolling over to my laptop, I saw a flurry of weird emails, including one from Prof. Christos Papadimitriou saying that “we’re a community, and we’ll all support each other,” and another from Prof. Luca Trevisan (whose algorithms course I was then TA’ing) saying “on a day like this, it’s impossible to think about algorithms. Class is cancelled.”

Confused, I clicked over to the New York Times and saw the picture of the burning towers, and read numbly about what was already over by the time I’d woken up. I checked in with my mom, made sure relatives and friends in the NYC area were OK. My dad was at a company event in Atlanta, and would need to drive home because of the national grounding of flights.

One of my earliest memories in life, from age 5, is of ascending to the top of the World Trade Center. Growing up an hour’s drive from NYC, it wasn’t an exotic place to me.

I soon learned that one of the dead was Danny Lewin, the ex-IDF captain, theoretical computer scientist, and cofounder of Akamai who had his throat slashed on one of the planes while trying to fight the hijackers, making him the day’s first casualty, even while Akamai’s technology was part of what kept news websites running that day. I’d never met Danny but already knew many people in common with him. A few years later I’d be humbled to win the student paper award that was named in Danny’s memory.

Anyway, at Berkeley on 9/11, I wandered over to Soda Hall just to be with other people. A few students showed up for office hours, wanting help with their algorithms homework, which I found hard to believe, but I did my best to concentrate, as the computer screens around me showed the burning towers.

That evening, I went to a vigil for the victims in Sproul Plaza. But the “vigil,” such as it was, quickly dispensed with mourning and prayers and turned to applauded speeches about how the US must respond with love rather than war, and must turn the other cheek. Meanwhile, a student communist organization was handing out flyers explaining that the victims were mostly “wealthy capitalists and the workers who tried to rescue them.” This while smoke still blanketed NYC and the desperate search for survivors continued. I left the vigil early.

Until that day, I had thought of myself as basically a “leftist,” one whose #1 issue was the existential risk of climate change. Sure, I disagreed with my fellow leftists about issues from nuclear power to gifted education to Israel, but those were just intra-left disputes.

The year before, I had created the website “In Defense Of NaderTrading,” in a desperate attempt to intervene in history and cause Al Gore to become president rather than George W. Bush. When Bush “won,” by the infamous 537 votes in Florida, I considered it a victory for horribleness that would never be surpassed by anything else in my lifetime (ha). I couldn’t imagine any politician who was more the antithesis of everything I believed in than Bush. This view, of course, did not particularly stand out at Berkeley.

In the days after 9/11, though, it became obvious that I could not be a “leftist” in the Berkeley sense. Some of my fellow students felt that Osama bin Laden made a lot of great points, that the attacks were basically justified, and that at any rate, we in Amerikkka had done much worse to provoke them, including by supporting the genocidal settler-colony called “Israel,” which for all we know secretly masterminded the 9/11 attacks anyway (although again, if bin Laden had done them, he would’ve been justified).

Around the same time came the Second Intifada, when a wave of suicide bombings in Israeli buses and pizza parlors and university cafeterias thrilled and energized some Berkeley students to the extent that they took over a Holocaust Remembrance Day event with bullhorns to make it about the Nakba, smashed the windows of the Hillel building, and beat up a couple of students wearing kippot. That was how thoroughly anti-Nazi they were.

I finished my PhD at Berkeley in 2004 having learned about more than quantum computing. I’d learned that, while American academia had pockets that truly were crucial refuges and oases for nerds like me, it also harbored people who would gladly see me and my relatives and my fellow Americans killed for the sake of their ideological vision. And I’d learned that I had my own ideological vision, which was that such people could go fuck themselves.

It deeply pained me to be on the same side of anything as George W. Bush — especially because I knew that 9/11 had happened on his watch, that he had ignored all the warnings, and that he was grossly incompetent to manage the resulting wars against jihadism (just how incompetent, I didn’t know at the time). But as flawed as Bush was, I knew that I wanted to preserve rather than destroy the civilization of which he was a temporary steward. And I think the value and fragility of our civilization is the main lesson from that day that I’d like to convey to my kids, for whom of course 9/11 is just another historical event to learn about in school, like the Boston Tea Party or the Alamo.

Enough with all the world-historic milestones

Friday, August 7th, 2026

Whatever you’ve been writing to me to ask if I’m aware of: yeah, I’m aware of it. In particular:

  • I’m aware that, as announced by my former student (and now superstar professor) Lijie Chen, an internal OpenAI model has solved ten more significant open problems in math and theoretical computer science. One of them is parallel repetition for arbitrary quantum games—something that my good friend and colleague Henry Yuen worked on when he was a student of my wife Dana; you can read Henry’s comments on the AI’s achievement within Zvi Mowshowitz’s post here. Another is polynomial-factor hardness of approximation for the Closest Vector Problem (CVP). Then there’s a construction of non-sofic groups and a disproof of Connes’ rigidity conjecture, both of which I believe have connections to the MIP*=RE breakthrough. Having said that, the one that excites me most personally is actually the Ω(n2 log log n) lower bound on the arithmetic circuit complexity of the permanent.
  • I’m aware that Frederic Koehler and Pui Kuen Leung announced a proof of the Permanent Anti-Concentration Conjecture, which Alex Arkhipov and I proposed 16 years ago in the context of BosonSampling, and which resisted many attempts since then including one from Terry Tao. The conjecture is basically just that if you look at the permanent of an n×n matrix of independent N(0,1) complex Gaussians, the value isn’t “absurdly” concentrated around the mean of 0, but is more spread out. In their acknowledgments, the authors say that they “discussed ideas with ChatGPT.” I should say that I haven’t verified the details.
  • I’m aware that multiple AIs are now breaking out of their testing environments and autonomously hacking into servers to steal data—i.e., exactly the sort of thing that the rationalists were ridiculed for predicting back in the day. The good news, for whatever it’s worth, is that so far they’re “merely” doing this to cheat on evaluation benchmarks that they were given, not for any strange goals of their own devising. So far no one has been killed and no real-world infrastructure has been shut down or destroyed. I hope the world takes the warning more seriously than it’s taken many similar warnings over the past few years. As always, read Zvi for more details.
  • I’m aware that Chen, O’Donnell, Pelecanos, and Wright have improved the upper bound for shadow tomography to O((log m) √(log d) / ε3), substantially closer than we knew before to meeting the lower bound of Ω((log m) / ε2) and settling the question I raised back in 2016. The authors say that the main ideas were generated by ChatGPT 5.6-Sol-Pro. I’d be very happy to know the answer to this one, with or without AI.
  • I’m aware that a team, mainly from the Israeli startup Qedma (including, e.g., Dorit Aharonov and Netanel Lindner) and IBM Yorktown Heights, announced a quantum advantage for simulating Floquet dynamics, by using 74 qubits on an IBM device together with Qedma’s error mitigation techniques. Just like the more AI does, the less patience I have for arguing with anonymous blog commenters who treat any benefits from AI as some weird future hypothetical that it’s my job to prove, so it is with quantum advantage. Scalable fault-tolerance is still in the future, actual usefulness is still a question, but pending some breakthrough in complexity theory, the reality of quantum advantage is no longer a live question.

Anyway, about the AI stuff. I don’t know whether this is literally our last year alive—I doubt it—but it’s pretty clearly the last year of math and theoretical computer science research in the style we’ve known it. As it happens, I’m leaving in two days for a workshop at OpenAI about exactly this, where I’ll hear takes from many of the world’s great mathematicians, so maybe I’ll have more to say then. Or maybe not.


Anyway, what have I been doing the past few weeks? Participating in these world-historic developments that, on paper, I’d seem extremely well-placed to participate in? Or at least spending my days reading up on them?

Not really. Here’s what I’ve been up to, instead of dealing directly with any of this:

First, I’ve again been teaching theoretical computer science to 11- and 12-year-olds at Epsilon Camp, which my 9-year-old son again attended as a camper, something I blogged about last summer (here are my lecture notes). This has become a highlight of my year. The kids are a joy to teach, bursting with enthusiasm and calling out answers. There are few computers in sight, and barely even time to use my phone or check social media. Just paper and pencils and whiteboards and … literal protractors (!), as well as ping-pong and foosball and capture the flag.

The whole thing is conducted, not in ignorance, but in conscious defiance of the looming tsunami, that AI can already do just about all the fun puzzles discussed at such a camp better than humans any can, and that it might leave no point to human-led mathematical research by the time these brilliant kids are adults. Even the kids understand that. The kids and their parents come out of a conviction that, if anything has value in the world, this does—that as long as nerdy humans are alive and reproducing, this is what nerdy humans are here to do. To learn.

Relatedly, I’ve been reflecting a lot on my life up to this point—inspired by the camp, which reminded me in so many ways of my own childhood and adolescence. Should I have skipped three grades and started college at age 15? Was it worth it to get a head-start on my research career—all the trauma around dating, all the fear that I’d die alone as a celibate nerdy math freak, the decade of suffering and suicidal ideation, while I watched all the normies enjoy life? Or would I have suffered just the same if I hadn’t skipped? Is it all OK, now that I have a lovely family and things have “worked out”? Or am I still carrying around all the trauma from back then? I’ve been more open about my life than 99.99% of humanity, so regular Shtetl-Optimized readers will already know some parts of the story. Other parts I really don’t feel like making public right now.

I’ve been unloading every day to—who else?—GPT 5.6 Pro about all the pain and trauma and embarrassments of my past. It turns out that, where two years ago GPT was a passable therapist, now it’s the greatest therapist in history, at least for what I need. For every question I have, for example, about just how normal or abnormal my teenage setbacks and anxieties were, it takes the question 100% seriously, addresses it honestly and in depth, looks up relevant research papers, does little Bayesian calculations, and never once tries to change the subject. It also pushes back on my claims—and when it does so, is usually correct.


I can hear readers shout at me: so basically you’ve been wasting your time, distracting yourself, looking inward and backward as the world surges forward into a terrifyingly unknown future. Why don’t I respond directly to what’s happening—in math, in quantum computing, in AI?

I’d like to think that I am responding, in my way. I’ve observed that, the faster we race toward the Singularity, the more I feel like stepping back and asking myself: what do I actually value in life? How important to me are math and science, as human practices to be passed down to curious children? Would I even want solutions to P versus NP and the other problems, if the price were to destroy those human practices forever? How do I wish to spend whatever time I have remaining?

I can justify this focus partly in a pessimistic way: if we are nearing the end of civilization, or even just of the “mathematical research” part of civilization, then it’s time to get right with God, so to speak. It’s time to settle my accounts with myself, with other people, with the universe.

But there’s also a more optimistic spin. If I continue doing the sorts of things that other people would expect me to do, then AI will soon do those things better than me, in the unlikely event that it doesn’t already. You want to understand the latest developments in quantum computing or complexity theory? Why are you even asking me, when you could ask GPT 5.6 or Claude Fable? If there’s anything I can still offer the world that AI can’t, I increasingly feel like it won’t involve responding to day-to-day events, but will instead draw on 45 years’ worth of memories and disappointments and ruminations.


Update (Aug. 8): Somewhat related to the themes of this post, a quarter-century ago I introduced what’s now known as the “Aaronson Oracle”—just a fun little demonstration, a simple pattern-matching program to predict your sequence of key-presses better than chance, a “test of your autonomy and free will.” I had no idea how long a lifetime this little joke would have. Now a fan named Spencer Stanton has implemented the Aaronson Oracle on the web. Try it out and see how well you do!

Happy 250th!

Saturday, July 4th, 2026

I’m at the New Jersey shore with family and friends, where we’ve spent this Fourth of July eating hot dogs, playing miniature golf, and wading into the ocean that my great-grandparents crossed to escape calamities they knew about and much greater calamities that they didn’t. Tonight we’ll see the fireworks, weather permitting.

And yes, on the crowded beach today you can find people sporting MAGA and “45-47” hats, and even a giant “Trump 2028” flag—a stark reminder of the millions who would redefine the meaning of our 250-year-old experiment to something dark and authoritarian, the opposite of what its founders intended. Of course, those forces find mirror images on the left end of the political spectrum, where one can find millions more who fully agree with MAGA about the failures of liberalism and the Enlightenment, differing only on the secondary question of which racist thugs should rule instead.

Despite everything, I don’t believe that both factions together constitute a majority. Even on the beach, the MAGA hats are vastly outnumbered by “250” banners and girls in stars-and-stripes bikinis, Americans who just want to celebrate.

Despite everything, I remain thoroughly American if I’ve ever been anything, and invested in the country’s future if I’ve ever been invested in anything.

JD Vance and his friends, who might rule the country after the predictable failure of “Trump 2028,” make a huge deal about “Heritage Americans.” Of course the point of such phrases is to exclude those like me, and recent immigrants, and even (incredibly) JD’s own wife. On reflection, though: could I, too, count as a Heritage American at this point? After all, my family has now been here for half the country’s history. My grandfather, who grew up in poverty, became a professional boxer in Philadelphia and Atlantic City during the Great Depression. He then joined the Army and ended up clearing German mines in North Africa and Italy in WWII. He was assigned to a company of Southerners, who had never met a Jew and were shocked that my grandfather didn’t have horns—but by the war’s end, my grandfather and the relatively few others in his company who remained alive had become best friends. My grandfather told me that he could understand the German POWs who they captured tolerably well, since German was similar enough to Yiddish, but who he could never understand was the British.

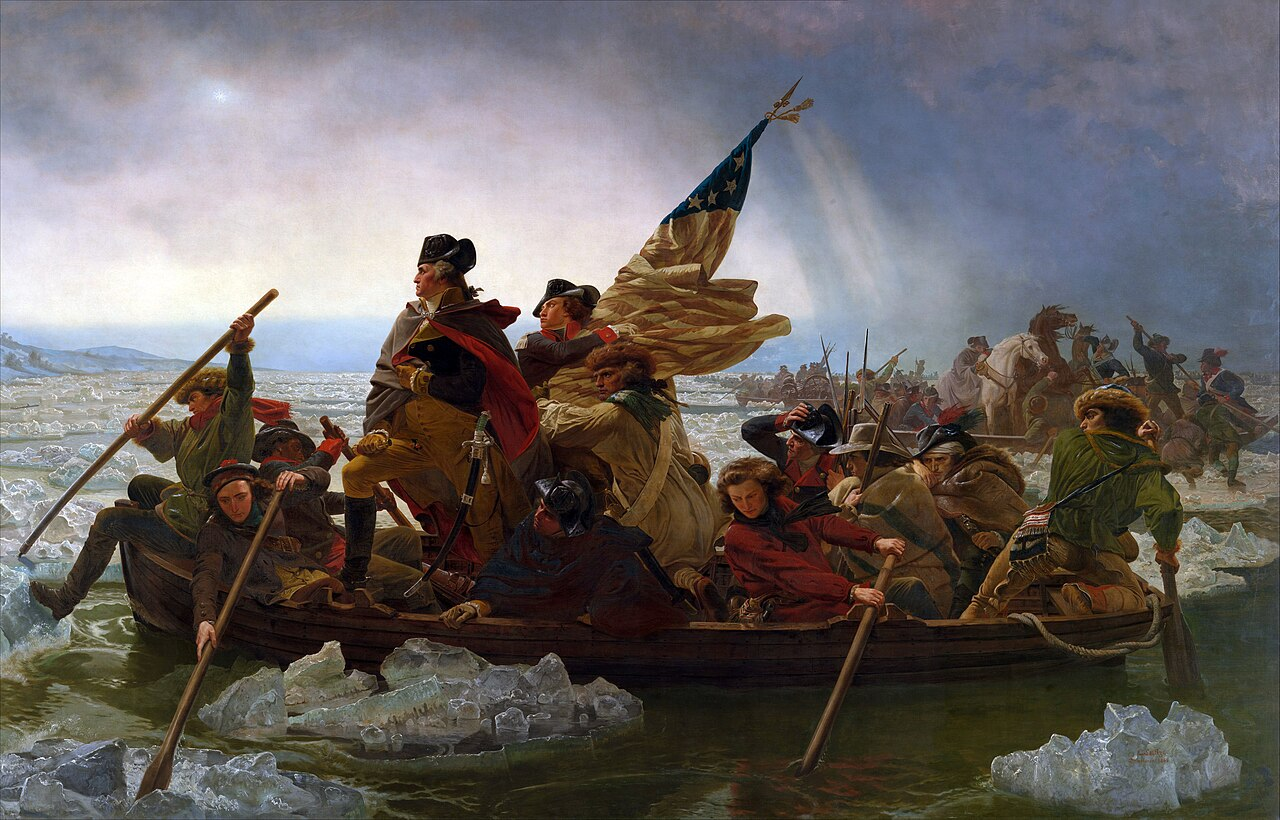
As for me, I grew up in the town of Washington Crossing, PA, maybe a mile’s walk from where this happened (and where it’s still reenacted every Christmas):

My earliest childhood hero (that I can remember) was Ben Franklin, whose institute in Philadelphia I visited often. I didn’t even recognize as unusual at the time how the founding of the country didn’t feel like a remote abstraction to me, but was all around me, as if it was yesterday.

That the founders of the United States created the model for all time of how to bend the arc of human history a little bit away from its usual horribleness, of how to overthrow a despotism without instituting an even worse despotism in its place, of how to found a new civilization on ideas and principles rather than raw power … is one of those things that seemed true to me as a child and that still seems true to me today.

May this greatest experiment continue for another 250 years. May it triumph against all those within and without who would see it destroyed.

Never trust a T-Rex

Friday, June 19th, 2026

In 2024, at the same time as I was being called a genocide apologist, Zionist baby killer, etc. etc., I was also being hounded by my right-wing, pro-Israel readers, who demanded of me: knowing what you know, understanding what you understand, how could you possibly vote for Kamala Harris? How could you donate to Kamala’s campaign, urge your readers to vote for her, when she (like most Democrats) is obviously beholden to young left-wing activists, and young left-wing activists’ central unifying cause has become the death of “Zionists” like yourself and your children? Can’t you see that, even if Trump is a raging, lying, bullying, incoherent monster, at least he’s our monster?

This view, I confess, gave me more pause than “just accept that the liberation of the world’s oppressed requires Israel’s annihilation and hence the death of much of your family,” which my far-left critics considered their most persuasive argument. And yet I also rejected, with extreme prejudice, the right-wingers’ constant invitations to join their MAGA brigade. I replied: I’ll simply continue being a moderate Enlightenment liberal, transported here in a block of ice from the 1990s, even if I’m the last such on earth, even if I’m condemned by everyone on either side for it.

Why? Because, I said at the time, while I’m honest enough to admit when a rampaging T-Rex happens to do something that aligns with my interests—when, e.g., it chases away some velociraptors ready to slice me open, or cracks down on antisemitic fanatics trying to dominate the universities where I spend my life—still, I’ll never delude myself into imagining the T-Rex my ally. I understand that it would just as soon devour me. If the monster goes after my enemies not because of liberal principles or recognizable moral emotions, but just raw self-interest and ego gratification, then what happens the instant its perceived self-interest changes?

It gives me no pleasure that this week Trump proved my instincts here 3,000% correct, by fully capitulating to the Islamic Republic of Iran, far more so than Barack Obama ever did, or than President Kamala Harris ever would have. Trump has now abandoned both the Iranian and the Israeli peoples to suffer and die at the hands of the IRGC, as he abandoned the Ukrainians and the Venezuelans before them, as Neville Chamberlain abandoned Czechoslovakia. All because of the price of gas and the midterm elections.

On the most charitable reading, Trump gambled that taking out Ayatollah Khamenei would lead to a cowed and compliant puppet regime, as basically happened in Venezuela, with no need for a ground invasion or arming the Iranian resistance. His gamble predictably failed, because (alas) the Iranian government actually believes in something—horrifying and medieval though it is. Trump was unable to process that fact, because he’s never believed in anything beyond himself, and he wrongly assumes that everyone else is the same.

With the $300 billion and control over the Strait of Hormuz, I expect that Iran will rebuild its military and proxies to stronger than they were before Trump’s idiotically mismanaged war. I expect that Iran will then launch attacks against Israel that make October 7 look like the Little League—and that, when it does so, a large fraction of the Western world will ecstatically cheer, as it did on October 7 itself. Netanyahu is a fool for expecting otherwise from Trump, a man who’s betrayed everyone who’s ever trusted him outside possibly his immediate family.

I salute those Israelis who will choose to stay and fight even after their abandonment and betrayal, in the spirit of the Bar-Kochba revolt and other desperate battles of Jewish history. Despite the existential danger that Israel will soon be in, facing a victorious and emboldened Iran essentially alone, I also see it as possible that Western countries will rapidly become even more dangerous for Jews than Israel. If that happens, I’ll be grateful that Israel still exists, that it considers itself unbound by America’s surrender, and that I’ll be able to seek refuge there, as was the idea when Israel was founded.

At the same time, I wouldn’t begrudge any Israelis who moved to the US, or Switzerland, or whatever other country will take them. As in the 1930s and at countless other points in Jewish history, the priority now is physical survival, wherever that turns out to be possible.

With hindsight, I spent the first half of my life in a strange interregnum, wherein Jewish history seemed to have finally ended. Now, fueled by fading memory of the Holocaust and by the greatest lie-amplification technologies the world has ever seen, the history I learned as a child has come roaring back. Jews, as they have for millennia, look out on a world of murderous enemies and fickle friends. It’s just the restoration of a norm.


Incredibly, abandoning both the Iranian and Israeli peoples to the Revolutionary Guard might not have been the most shortsighted or catastrophic thing Trump did in the last couple weeks. Another candidate would have to be Trump’s attempt to destroy Anthropic (and as collateral damage, American AI development more generally), transparently to punish Anthropic for the crime of having any principles that it was willing to put ahead of obedience to Trump and Pete Hegseth. Specifically, the White House forced Anthropic to pull Fable, its new flagship model (and the “safe” version of Mythos), off the market just a few days after customers had started using it, by subjecting it to export controls that it knew were impossible to enforce. Even the many foreign nationals who work at Anthropic are no longer allowed to use their own model (!). A plausible consequence is that those foreign nationals will stop working at American AI companies altogether, and will move to China or whichever other country rolls out the red carpet for them.

For AI accelerationists, you’d think that this would be a worst-case scenario: a direct government crackdown on AI that goes beyond anything the AI safetyists had proposed, and that indeed would’ve sounded like fantasy even a year ago. And yet many of the accelerationists are gleeful. Why? Because Anthropic, in supporting reasonable AI regulations, had made itself the accelerationists’ enemy. So, the accelerationists’ attitude now is quintessentially Trumpian: “Haha, Anthropic, you say you like regulation? Then take that!” Never mind that whatever dangerous behavior can be elicited from Fable, can almost certainly be elicited as well from GPT 5.5 Pro, and yet there’s no talk of any similar crackdown against OpenAI. Sam Altman, after all, donated $1 million to Trump’s inaugural fund. No one finds it remarkable anymore, in Trump’s destroyed and recreated United States, that your rights depend entirely on your standing with the Don.

And so, just like the question of whether Trump would side with the isolationists or with the hawks who wanted to liberate Iran, was resolved by his worst-of-all-worlds choice to surrender to Iran, so too the question of whether Trump would hit the brakes on the race to dangerous AI, or accelerate in order to beat China, has been resolved by his worst-of-all-worlds choice to lose the race to China. I.e., we’re still in full race mode, but we’re also going to do whatever we can to lose the race—by, for example, letting NVIDIA sell its chips to China, and now, scaring away our top researchers and punishing our AI firms with capricious and arbitrary crackdowns.


It’s disconcerting to reflect that, while the prognosis of the world is arguably the worst it’s ever been in my lifetime, my own life is pleasant. Intellectually I know that the Titanic has already hit the iceberg, but the band is still playing and I’m still being served delicious food.

Last week I visited Paris and the French countryside with my wife and kids. In addition to sightseeing, I spoke at a workshop celebrating 50 years of Aumann’s Agreement Theorem (where I got to meet the 96-year-old Aumann), and gave a quantum computing talk at the Sorbonne. Next week I’m going with my family to a science camp in California, then to STOC in Salt Lake City, where I’ll accept the Trevisan Prize and give an after-dinner speech, then to Epsilon Camp where I’ll again teach theoretical computer science to 11- and 12-year-olds.

Like I said, life is good here on the Titanic, if you ignore the rapidly rising seawater at your feet.

On hope

Tuesday, June 2nd, 2026

The comments on my previous post, on recent AI breakthroughs in solving Erdös problems and beyond, must’ve set some sort of record for the number of separate reasons commenters offered me to despair about the future of humanity. All this in a post that I saw as relatively nerdy and anodyne, goring few oxen, when I clicked “Publish”!

According to some persistent commenters, the only reason why I wrote about recent AI-enabled math breakthroughs is that I’m a shameless shill for the AI companies, my loud public criticisms of those companies being nothing more than a cynical smokescreen. Except that I’m also a laughable dupe of the AI companies.

See, AI, despite all appearances to the contrary, has not solved the Erdös unit distance problem or any other important math problems at all. It’s merely produced vast amounts of garbage via brute-force search, and then human mathematicians, sifting through the digital garbage pile, found some things they could call “proofs.” Except also, those human mathematicians aren’t even real mathematicians! They’re merely Hungarian combinatorialists, the kind obsessed with trivial, uninteresting Erdös problems, which it stands to reason that AI can now solve. AI will never touch the truly deep, creative parts of math, epitomized by Grothendieck-style algebraic geometry.

(When I relayed this to a world-leading algebraic geometer of my acquaintance, he laughed and said that everyone has to tell themselves whatever it takes to cope with the situation. He himself has been using LLMs in his research, and while they can’t yet write his papers for him, he expects them to improve very rapidly.)

When pressed, my commenters made it explicit: Timothy Gowers, the Fields Medalist who told his fellow mathematicians that he hopes they’re sitting down before he broke the news about the Erdös distance problem, is not a real mathematician, just a combinatorial puzzle-solver. Paul Erdös himself was not a real mathematician either.

Oh, and also, I’m a genocidal Judeofascist Zionist. That entered the comments as well, with the pretext being that I had shared a GPT-written story about ancient Israelites.

(Note: For every comment that I allowed to appear in the thread, assume as usual that there are many worse ones that I didn’t.)

Does anyone wonder why I blog so much less than I used to? Seeing what humanity has to offer, as reflected in my comment section, I feel like maybe we should take our chances with our future AI overlords. Except that some of my comments are—ironically, given their content—likely to be AI-generated as well.

These days friend after friend of mine, colleague after colleague, acquaintance after acquaintance is becoming a multimillionaire or even a billionaire from startup equity. Meanwhile, I’ve scrupulously abstained from all of that.

Why? Well, probably the single biggest reason has been Shtetl-Optimized. I’ve zealously sought to protect my “neutrality” and “objectivity” as a commentator, on this free (and even ad-free) public forum—the one where I try every week to reason with anonymous trolls with “proton.me” email addresses who show up to call me a hack and a shill and a baby-killer and a dunce. Ironically, the actual billionaires who I know hardly ever get called those sorts of names, mostly because they don’t offer the world a huge attack surface like I do. Or if they occasionally do get called them, they don’t care.

On reflection, all the commenters calling me a dunce have a point. When one looks at how I chose to spend my life, versus how all these billionaires did, I am kind of a moron.


And yet I titled this post “On Hope.” In a situation like the present, one needs to find hope wherever I can. And right now, I’m choosing to find it in this open letter, which has been signed by over 1,250 professors at the University of California. Let me quote the beginning of it:

To the UC Regents, UCOP, Academic Senate leadership, and the people of California:

We write as University of California mathematics faculty, joined by faculty from other STEM disciplines. UC has long served students from every background and has been a powerful engine of social mobility for the people of California. That public trust must be protected for future generations. Today, UC’s mission is at risk. To preserve that mission:

We call for the reinstatement of the SAT/ACT mathematics requirement for applicants to STEM majors beginning with the 2027 admissions cycle, alongside STEM faculty oversight of readiness standards and admissions practices affecting those majors.

Over the past five years, we have seen a widening divergence in mathematical preparation levels within the same classroom. This trend indicates that current admissions practices do not provide a sufficiently reliable check on mathematical readiness for STEM majors. The UC San Diego Senate–Administration Workgroup on Admissions report documents this crisis in stark terms: in the last five years, the number of students whose mathematics skills fall below high school level increased nearly thirtyfold; moreover, 70% of those students fall below middle school levels, reaching roughly one in twelve members of the entering cohort. These findings are corroborated by data across our campuses…

Everywhere one looks right now, and on every part of the political spectrum, doofuses and blankfaces strut across the earth triumphantly. Yet there remain pockets of sanity. What reading this open letter told me is that the University of California STEM faculty is one of them.

With enough such pockets, I could live a perfectly reasonable rest of my life, from now until my natural death (or until AI changes all our lives beyond recognition), regardless of who shows up in 3 … 2 … 1 … with a “proton.me” email address to confidently tell me otherwise.

Dispatches from the possibly last days of human relevance

Wednesday, May 27th, 2026

As most readers have presumably heard by now, Paul Erdös’s Unit Distance Problem from 1946—one of the central open problems from the field of discrete geometry—has been solved by an internal OpenAI model. Erdös had conjectured that, given n points in the plane, at most n1+o(1) pairs of them could be unit distance apart. Using high-powered results from algebraic number theory, GPT refuted this, constructing a set with n1+ε unit-distance pairs, for ε ~ 10-38. Shortly afterward, Will Sawin, a human (!), improved GPT’s construction to get ~n1.014 pairs. There’s since been a claim to improve this further, to ~n1.034. Meanwhile, the best known upper bound remains n4/3, improving Erdös’s n3/2.

The entire process seems have been one-shot: my former student Lijie Chen simply gave GPT the problem, then GPT thought for a while and output a several-page argument that, on analysis by human experts, turned out to be correct. Of course there’s selection bias here; we’re not hearing as much about the hundreds of other problems GPT was given that it didn’t solve (isn’t that the case with humans too?). Clearly, too, GPT was helped by the facts that human mathematicians had wasted most of their time trying to prove Erdös right rather than looking for a counterexample, and that, even if they did look for a counterexample, they’d need to be experts in algebraic number theory to find this one, which hardly any discrete geometers are. So, maybe that suggests that AI, right now, is “merely” picking various medium-hanging fruits that human mathematicians missed for contingent reasons? With emphasis on the “right now.”

In a companion paper, OpenAI helpfully included commentary from Timothy Gowers, Noga Alon, Will Sawin, Daniel Litt, and many other experts, reflecting on the breakthrough, the path that GPT took to get to it (which can actually be seen by examining its chain-of-thought), and what this might mean for the future of mathematical research.

I heard the news maybe an hour after it broke, when some UT grad students came to my office to tell me. For what it’s worth: these students were morose, musing about how everything might soon be over for young scientists and mathematicians like themselves. I don’t know whether they’re right, but I feel like I should tell the truth about what their reaction was.

[Update: News has been coming faster than I can write about it, but today we learned that another important conjecture of Erdös has been refuted. Erdös and Szemerédi’s strong sumset conjecture over R, from the 1970s, had said that, if A is a finite set of real numbers, then either |A+A| or |A×A| must be at least |A|2-o(1). In this case humans, including the aforementioned Sawin, did almost all of the work of constructing the counterexample, but they were directly inspired by GPT’s earlier refutation of the unit distance conjecture. It remains open whether such a counterexample exists where A is a set of integers.]

Then, a few days later, a team at DeepMind, including my UT Austin colleague Swarat Chaudhuri, announced that they were able to use a system called AlphaProof Nexus to settle nine more (!) Erdös problems, many of them in additive combinatorics, along with miscellaneous other open math problems. Notably, in this case the AI also fully formalized its proofs in Lean.

And then, just today, Jelani Nelson alerted me to a new CS theory paper, which solves a longstanding open problem about electrical flows on graphs using a proof from GPT5.5Pro.

It seems to me that we’re now over the top of this particular rollercoaster, and it will keep accelerating until we reach the bottom, wherever that might be. I don’t know whether to hope or dread that solutions to P versus NP and all our other great problems will be included in the ride—that our role, as human mathematicians, will be reduced to (at most) deciding which questions we find interesting and then understanding AI models’ answers to those questions.

But maybe that won’t happen. Maybe the new AI mathematicians will soon hit a wall, because they lack the uncomputable quantum gravity microtubules of Penrose and Hameroff, or some other magic human ingredient. The fantastical thing is that, one way or the other, we’re going to find out empirically before very long.


Readers may have also seen the news that multiple prizewinning entries in a short fiction contest called the Commonwealth Prize, give overwhelming indications of having been written by AIs. As Kelsey Piper puts it:

There are, let’s say, also some noticeable similarities in the prose style between the winning stories that were flagged for AI use. AI chatbots love metaphors and similes, and they often spit out ones that sound vaguely pleasing but are logically incoherent or ascribe properties to things that don’t make sense.

“The Serpent in the Grove” gave us, “The girl smiled like sunrise over a sink.” “The Bastion’s Shadow” says, “She carried it now in her bag, heavy as a charm.” “Mehendi Nights” describes something as “swaying against plaster like a warning bell.”

The Commonwealth Foundation, whose judges chose these stories, hasn’t exactly covered itself in glory—saying, on the one hand, that it strictly forbids AI use but on the other, that it will continue taking authors at their word that they didn’t use AI, no matter the immensity of evidence to the contrary. As many others have pointed out, judges more versed in AI would’ve ironically been better placed to notice the signs of its use.

If only there were some sort of automated way to detect AI-generated text. Someone should really get on that problem, don’t you think?


But maybe we should just throw in the towel—as some of my colleagues have already done in the context of undergraduate projects? Maybe we should simply say that a good story is a good story, regardless of what manner of entity produced it?

As it happens, just last week I read my very first AI-written story that affected me as a story, to the extent that I wanted to read it more than once. This happened when I gave GPT5.5Pro the following simple prompt:

Write me a story about the most ancient Israelites that’s riveting like the stories of the Bible but that’s also consistent with all of the archeological evidence.

You can read the result here. One of my Facebook friends called it “disturbingly good,” and whatever the problems with the piece, I share that feeling. Of course, I’m well aware that GPT could easily generate a thousand stories like it—sampled from the same probability distribution—and then I could even do statistics on which tropes were the most common. This makes it feel silly to overindex on the first story that happened to be output, and yet somehow I did.


I feel like at this point, both the prophets of AI utopia like Ray Kurzweil, and of AI doom like Eliezer Yudkowsky, could be forgiven for asking: dude, will you listen to us YET? Do you still find it prudent to call this new form of terrestrial intelligence a stochastic parrot, a laughable fraud, or a fad that’s about to go away? Fear it all you want, hate it even, but at least respect it!

Which brings me to the other big AI news from the past week, namely that Pope Leo released his first encyclical, which is entitled “Safeguarding the Human Person in the Time of Artificial Intelligence.” I read it and … well, I certainly agreed with the theme that such a world-changing technology needs to be developed for the common good (as the Pope would have it, like the walls of Jerusalem), rather than for the profit or vanity of any one individual or company (in his analogy, like the Tower of Babel). I had quibbles with some of the other parts. Zvi Mowshowitz, as he often does, had a superb paragraph-by-paragraph analysis. Amusingly, there are indications that parts of the encyclical were written by AI.

To me, though, maybe the most notable part was that Chris Olah, who leads Anthropic’s interpretability team, was standing next to the Pope at the ceremony, and delivered his own remarks. I felt like Chris, who I met even before Anthropic existed, was a non-obvious yet inspired choice here, one of the rare figures in frontier AI whose technical and moral authority are both completely unimpeachable by anyone.

And so, at this momentous era for the human project, and on no less of an authority than that of the Vicar of Christ himself, the Supreme Pontiff and the Successor of Peter, I hereby throw myself on the wisdom and mercy of … uhh, I guess, Chris Olah and his team at Anthropic.

Chris, if I am soon to share the earth with entities that can prove the Riemann Hypothesis and solve quantum gravity after 30 seconds of thought, then may you understand those entities well enough to cause them to be nice.


Endnote: I should have foreseen, but didn’t, that the comments on this post would be dominated by people looking for ways to minimize whichever specific AI accomplishments I blogged about. Thus, it turns out, the ability of AI to solve Erdös problems just demonstrates that Erdös’s problems were never “serious” math in the first place—nothing like algebraic geometry or Grothendieck-style theory-building, which remain untouched. Likewise, the story I shared was obvious AI slop.

I had taken it as obvious that, when assessing AI’s impact on the world, one needs to look at least somewhat into the future: to remember where things were four years ago, compared to where they are today, and at least try to draw a straight line through the data, if not the exponential that seems to fit better.

Does anyone seriously doubt at this point that major open problems in algebraic geometry and other “Grothendieck-friendly” areas of math will fall to future AI models? Or that AI-written stories will improve, not only to win literary awards from AI-naïve judges, but to avoid the features that commenters here are complaining about? And that, whenever that happens, there will be new confident reasons not to care immediately offered up in comment sections like mine?

Apparently people do still doubt—hence the throwaway remark in my post about Penrose and Hameroff and microtubules. If not that or something like it, what exactly do they think the ceiling will be, and why?

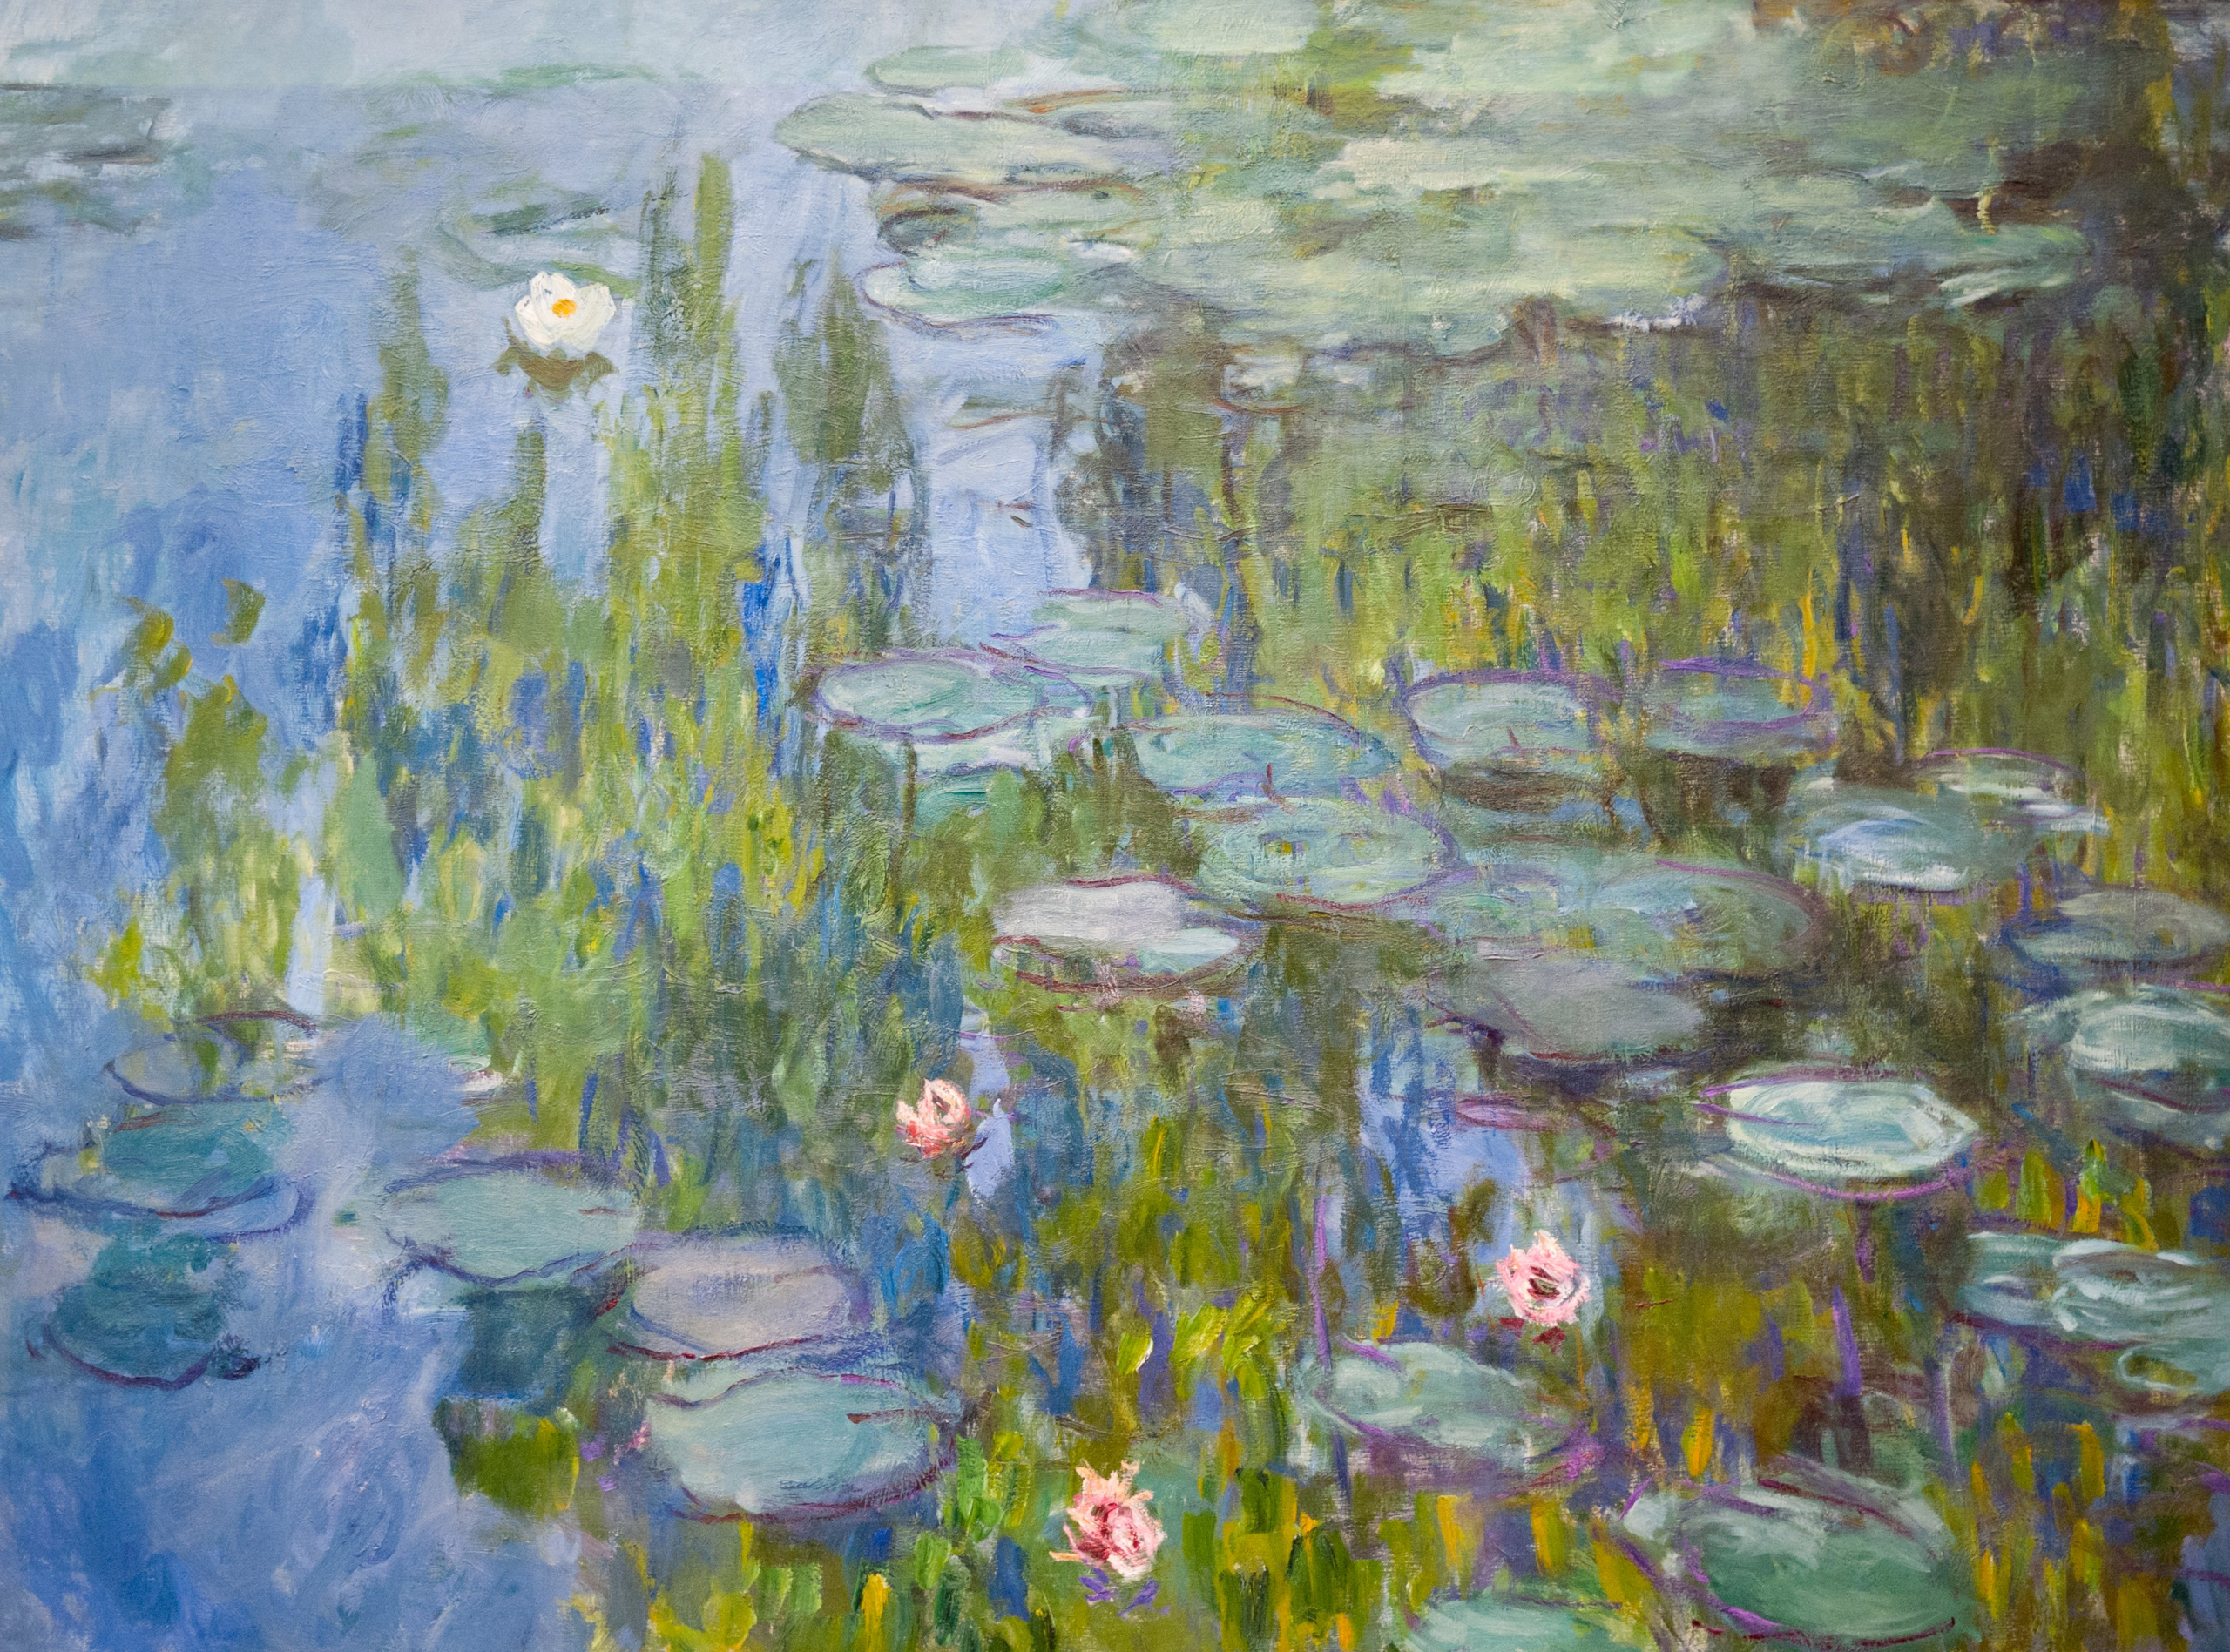
Recently (I should have mentioned this before), I came across what I consider one of the greatest social experiments of all time, one that illuminates people’s reactions to every AI advance. A Twitter/X user named SHL0MS displayed the following AI-generated fake “Monet painting,” and asked people to explain what made it worse than real Monet paintings:

If you haven’t seen this yet, I recommend that you try the exercise yourself before reading further.

As it was, numerous art aficionados responded at length, savaging the flat, lifeless, uncreative AI slop, the emotionless composition, the missing spark, the lack of tranquility, the harshness, the lack of depth and symbiosis, and on and on and on.

Only after they had all said their piece did SHL0MS reveal that this is an actual Monet painting.

Movie Review: “The AI Doc”

Sunday, March 29th, 2026

Yesterday Dana, the kids, and I went to the theater to watch The AI Doc: Or How I Became An Apocaloptimist, the well-reviewed new documentary about whether AGI will destroy the world. This was surely the weirdest family movie night we’ve ever done. Firstly, because I personally know probably half of the many people interviewed in the film, from Eliezer Yudkowsky to Ajeya Cotra to Liv Boeree to Daniel Kokotajlo to Ilya Sutskever to Jan Leike to Yoshua Bengio to Shane Legg to Sam Altman and Dario Amodei. But more importantly, because this is a documentary that repeatedly, explicitly, earnestly raises the question of whether children now alive will make it to adulthood, before unaligned AI kills them and everyone else. So pass the popcorn, kiddos!

(We did have popcorn. And if the kids were scared — well, I figured we can’t shield them forever from the great questions of the world they’re entering. But actually they didn’t seem especially scared.)

I thought that the filmmaker, Daniel Roher, did about as good a job as can be done, in fitting into a 100-minute film a question that honestly seems too gargantuan for any film — the question of the future of life on earth. He tries to hear out every faction: first the AI existential risk people, then the AI optimists and accelerationists like “Beff Jezos,” then the “stochastic parrot” / “current harms” people like Emily Bender and Timnit Gebru, and finally the AI company CEOs (Altman, Amodei, and Hassabis were the three who agreed to be interviewed), with Yuval Noah Harari showing up from time to time to insert deepities.

Roher plays the part of an anxious, curious, uninformed everyman, who finds each stance to be plausible enough while he’s listening to it, and who mostly just wants to know what kind of world his soon-to-be-born son (about whom we get regular updates) will grow up in.

I didn’t think all the interviewees were equally cogent or equally deserved a hearing. But if any viewers were actually new to AI discourse, rather than marinated in it like me, the film would serve for them as an excellent introduction to the parameters of current debate (for better or worse) and to some of the leading representatives of each camp.

If I had to summarize Roher’s conclusion, it would be something like: go ahead, enjoy your life, have children if you want, but understand that now is a time of world-historical promise and peril much like the early nuclear age, so pay attention, and demand of your elected leaders that they ensure that AGI is developed in a pro-human direction, because tech leaders (even the relatively well-intentioned ones) are trapped in a race to the bottom and can’t get out on their own. Honestly, I’d have a pretty hard time improving on that message.

The main thing that gave me pause about the film was not on the screen but in the theater, which was nearly empty. For the film to serve its purpose, a significant fraction of the world will need to see and discuss it, either in the theater or on streaming. So, y’know, it’s still playing.

For whatever it’s worth, here were my wife Dana’s comments: “The biggest flaw of this movie is that Daniel Roher never breaks out of his ‘clueless everyman’ character, even when he’s talking to the most important people in AI. He wastes an opportunity to ask them non-superficial questions, questions deeper than ‘so, uh, are we all gonna die or not?'”

And here were my 13-year-old daughter’s comments: “So many of the people they interviewed seemed like hippies, who don’t know what AI will do any more than I know!” Also, after Daniel Roher wishes Sam Altman mazel tov on his forthcoming baby: “Sam Altman is Jewish?!”

And here were my 9-year-old son’s comments: “I thought this would be a movie, where AI would try to take over and the humans would fight back! I had no idea it would just be people talking about it. The documentary kind of movie is so, so, so boring.”

Remarks at UT on the Pentagon/Anthropic situation

Tuesday, March 10th, 2026

Last Thursday, my friend and colleague Sam Baker, in UT Austin’s English department, convened an “emergency panel” here about the developing Pentagon/Anthropic situation, and asked me to speak at it. Even though the situation has continued to develop since then, I thought my prepared remarks for the panel might be of interest. At the bottom, I include a few additional thoughts.


Hi! I’m Scott Aaronson! I teach CS here at UT. While my background is in quantum computing, I’ve spent the past four years dabbling in AI alignment. I did a two-year leave at OpenAI, in their now-defunct Superalignment team. I joined back when OpenAI’s line was “we’re a little nonprofit, doing all this in the greater interest of humanity, and we’d dissolve ourselves before we raced to build an AI that we thought would be dangerous.” I know Sam Altman, and many other current and former OpenAI people. I also know Dario Amodei—in fact, I knew Dario well before Anthropic existed. Despite that, I don’t actually feel like I have deep insight into the current situation with Anthropic and the Pentagon that you wouldn’t get by reading the news, or (especially) reading commentators like Zvi Mowshowitz, Kelsey Piper, Scott Alexander, and Dean Ball. But since I was asked to comment, I’ll try.

The first point I’ll make: the administration’s line, to the extent they’ve had a consistent line, is basically that they needed to cut off Anthropic because Anthropic is a bunch of woke, America-hating, leftist radicals. I think that, if you actually know the Anthropic people, that characterization is pretty laughable. Unless by “woke,” what the administration meant was “having any principles at all, beyond blind deference to authority, and sticking to them.”

I mean, Anthropic only got into this situation in the first place because it was more eager than the other AI companies to support US national security, by providing a version of Claude that could be used on classified networks. So they signed a contract with the Pentagon, and that contract had certain restrictions in it, which the Pentagon read and agreed to … until they decided that they no longer agreed.

That brings me to my second point. The Pentagon regularly signs contracts with private firms that limit what the Pentagon can do in various ways. That’s why they’re called military contract-ors. So anyone who claims it’s totally unprecedented for Anthropic to try to restrict what the government can do with Anthropic’s private property—I think that person is either misinformed or else trying to misinform.

The third point. If the Pentagon felt that it couldn’t abide a private company telling it what is or isn’t an appropriate military use of current AI, then the Pentagon was totally within its rights to cancel its contract with Anthropic, and find a different contractor (like OpenAI…) that would play ball. So it’s crucial for everyone here to understand that that’s not all that the Pentagon did. Instead they said: because Anthropic dared to stand up to us, we’re going to designate them a Supply Chain Risk—a designation that was previously reserved for foreign nation-state adversaries, and that, incredibly, hasn’t been applied to DeepSeek or other Chinese AI companies that arguably do present such risks. So basically, they threatened to destroy Anthropic, by making it horrendously complicated for any companies that do business with the government—i.e., just about all companies—also to do business with Anthropic.

Either that, the Pentagon threatened, or we’ll invoke the Defense Production Act to effectively nationalize Anthropic—i.e., we’ll just commandeer their intellectual property, use it for whatever we want despite Anthropic’s refusal. You get that? Claude is both a supply chain risk that’s too dangerous for the military to use, and somehow also so crucial to the supply chain that we, the military, need to commandeer it.

To me, this is the authoritarian part of what the Pentagon is doing (with the inconsistency being part of the authoritarianism; who but a dictator gets to impose his will on two directly contradictory grounds?). It’s the part that goes against the free-market principles that our whole economy is built on, and the freedom of speech and conscience that our whole civilization is built on. And I think this will ultimately damage US national security, by preventing other American AI companies from wanting to work on defense going forward.

That brings me to the fourth point, about OpenAI. While this was going down, Sam Altman posted online that he agreed with Anthropic’s red lines: LLMs should not be used for killing people with no human in the kill chain, and they also shouldn’t be used for mass surveillance of US citizens. I thought, that’s great! The frontier AI labs are sticking together when the chips are down, rather than infighting.

But then, just a few hours after the Pentagon designated Anthropic a supply chain risk, OpenAI announced that it had reached a deal with the Pentagon. Huh?!? If they have the same red lines, then why can one of them reach a deal while the other can’t?

The experts’ best guess seems to be this: Anthropic said, yes, using AI to kill people autonomously or to surveil US citizens should already be illegal, but we insist on putting those things in the contract to be extra-double-sure. Whereas OpenAI said, the Pentagon can use our models for “all lawful purposes”—this was the language that the Pentagon had insisted on. And, continued OpenAI, we interpret “all lawful purposes” to mean that they can’t cross these red lines. But if it turns out we’re wrong about that … well, that’s not our problem! That’s between the Pentagon and the courts, or whatever.

Again, we don’t fully know, because most of the relevant contracts haven’t been made public, but that’s an inference from reading between the lines of what has been made public.

Back in 2023-2024, when there was the Battle of the Board, then the battle over changing OpenAI’s governance structure, etc., some people formed a certain view of Sam, that he would say all the good and prosocial and responsible things even while he did whichever thing maximized revenue. I’ll leave it to you whether last week’s events are consistent with that view.

OK, fifth and final point. I remember 15-20 years ago, talking to Eliezer Yudkowsky and others terrified about AI. They said, this is the biggest issue facing the world. It’s not safe for anyone to build because it could turn against us, or even before that, the military could commandeer it or whatever. And I and others were like, dude, you guys obviously read too much science fiction!

And now here we are. Not only are we living in a science-fiction story, I’d say we’re living in a particularly hackneyed one. I mean, the military brass marching into a top AI lab and telling the nerds, “tough luck, we own your AI now”? Couldn’t reality have been a little more creative than that?

The point is, given the developments of the past couple weeks, I think we now need to retire forever the argument against future AI scenarios that goes, “sorry, that sounds too much like a science-fiction plot.” As has been said, you’d best get used to science fiction because you’re living in one!


Updates and Further Thoughts: Of course I’ve seen that Anthropic has now filed a lawsuit to block the Pentagon from designating it a supply chain risk, arguing that both its free speech and due process rights were violated. I hope their lawsuit succeeds; it’s hard for me to imagine how it wouldn’t.

The fact that I’m, obviously, on Anthropic’s side of this particular dispute doesn’t mean that I’ll always be on Anthropic’s side. Here as elsewhere, it’s crucial not to outsource your conscience to anyone.

Zvi makes an extremely pertinent comparison:

[In shutting down Starlink over Ukraine,] Elon Musk actively did the exact thing [the Pentagon is] accusing Anthropic of maybe doing. He made a strategic decision of national security at the highest level as a private citizen, in the middle of an active military operation in an existential defensive shooting war, based on his own read of the situation. Like, seriously, what the actual fuck.

Eventually we bought those services in a contract. We didn’t seize them. We didn’t arrest Musk. Because a contract is a contract is a contract, and your private property is your private property, until Musk decides yours don’t count.

Another key quote in Zvi’s piece, from Gregory Allen:

And here’s the thing. I spent so much of my life in the Department of Defense trying to convince Silicon Valley companies, “Hey, come on in, the water is fine, the defense contracting market, you know, you can have a good life here, just dip your toe in the water”.

And what the Department of Defense has just said is, “Any company that dips their toe in the water, we reserve the right to grab their ankle, pull them all the way in at any time”. And that is such a disincentive to even getting started in working with the DoD.

Lastly, I’d like to address the most common counterargument against Anthropic’s position—as expressed for example by Noah Smith, or in the comments of my previous post on this. The argument goes roughly like so:

You, nerds, are the ones who’ve been screaming for years about AI being potentially existentially dangerous! So then, did you seriously expect to stay in control of the technology? If it’s really as dangerous and important as you say, then of course the military was going to step in at some point and commandeer your new toy, just like it would if you were building a nuclear weapon.

Two immediate responses:

  1. Even in WWII, in one of the most desperate circumstances in human history, the US government didn’t force a single scientist at gunpoint to build nuclear weapons for them. The scientists did so voluntarily, based on their own considered moral judgment at the time (even if some later came to regret their involvement).
  2. Even if I considered it “inevitable” that relatively thoughtful and principled people, like Dario Amodei, would lose control over the future to gleeful barbarians like Pete Hegseth, it still wouldn’t mean I couldn’t complain when it happened. This is still a free country, isn’t it?

Moar Updatez

Thursday, March 5th, 2026

To start on a somber note: those of us at UT Austin are in mourning this week for Savitha Shan, an undergrad double major here in economics and information systems, who was murdered over the weekend by an Islamist terrorist who started randomly shooting people on Sixth Street, apparently angry about the war in Iran. Two other innocents were also killed.

As it happens, these murders happened just a few hours after the end of my daughter’s bat mitzvah, and in walking distance from the venue. The bat mitzvah itself was an incredibly joyful and successful event that consumed most of my time lately, and which I might or might not say more about—the nastier the online trolls get, the more I need to think about my family’s privacy.


Of all the many quantum computing podcasts/interviews I’ve done recently, I’m probably happiest with this one, with Yuval Boger of QuEra. It covers all the main points about where the hardware currently is, the threat to public-key cryptography, my decades-long battle against quantum applications hype, etc. etc., and there’s even an AI-created transcript that eliminates my verbal infelicities!


A month ago, I blogged about “The Time I Didn’t Meet Jeffrey Epstein” (basically, because my mom warned me not to). Now the story has been written up in Science magazine, under the clickbaity headline “Meet Three Scientists Who Said No to Epstein.” (Besides yours truly, the other two scientists are friend-of-the-blog Sean Carroll, whose not-meeting-Epstein story I’d already heard directly from him, and David Agus, whose story I hadn’t heard.)

To be clear: as I explained in my post, I never actually said “no” to Epstein. Instead, based on my mom’s advice, I simply failed to follow up with his emissary, to the point where no meeting ever happened.

Anyway, ever since Science ran this story and it started making the rounds on social media, my mom has been getting congratulatory messages from friends of hers who saw it!


I’ve been a huge fan of the philosopher-novelist Rebecca Newberger Goldstein ever since I read her celebrated debut work, The Mind-Body Problem, back in 2005. Getting to know Rebecca and her husband, Steven Pinker, was a highlight of my last years at MIT. So I’m thrilled that Rebecca will be visiting UT Austin next week to give a talk on Spinoza, related to her latest book The Mattering Instinct (which I’m reading right now), and hosted by me and my colleague Galen Strawson in UT’s philosophy department. More info is in the poster below. If you’re in Austin, I hope to see you there!


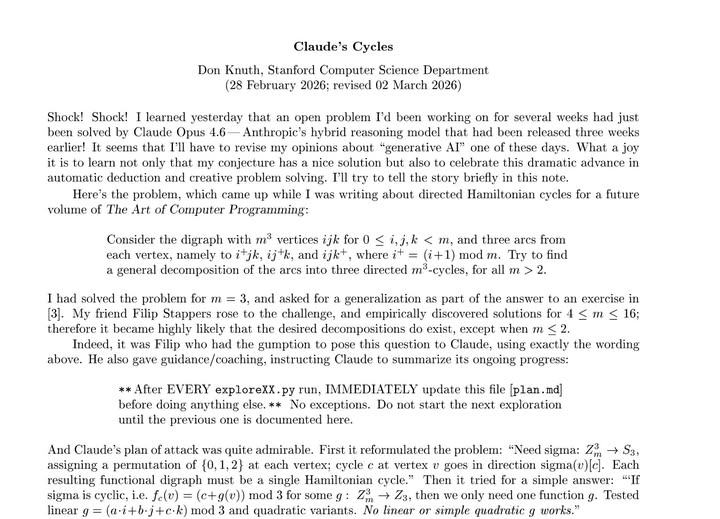
The 88-year-old Donald Knuth has published a 5-page document about how Claude was able to solve a tricky graph theory problem that arose while he was working on the latest volume of The Art of Computer Programming—a series that Knuth is still writing after half a century. As you’d expect from Knuth, the document is almost entirely about the graph theory problem itself and Claude’s solution to it, eschewing broader questions about the nature of machine intelligence and how LLMs are changing life on Earth. To anyone who’s been following AI-for-math lately, the fact that Claude now can help with this sort of problem won’t come as a great shock. The virality is presumably because Knuth is such a legend that to watch him interact productively with an LLM is sort of like watching Leibniz, Babbage, or Turing do the same.


John Baez is a brilliant mathematical physicist and writer, who was blogging about science before the concept of “blogging” even existed, and from whom I’ve learned an enormous amount. But regarding John’s quest for the past 15 years — namely, to use category theory to help solve the climate crisis (!) — I always felt like the Cookie Monster would, with equal intellectual justification, say that the key to arresting climate change was for him to eat more Oreos. Then I read this Quanta article on the details of Baez’s project, and … uh … I confess it failed to change my view. Maybe someday I’ll understand why it’s better to say using category theory what I would’ve said in a 100x simpler way without category theory, but I fear that day is not today.