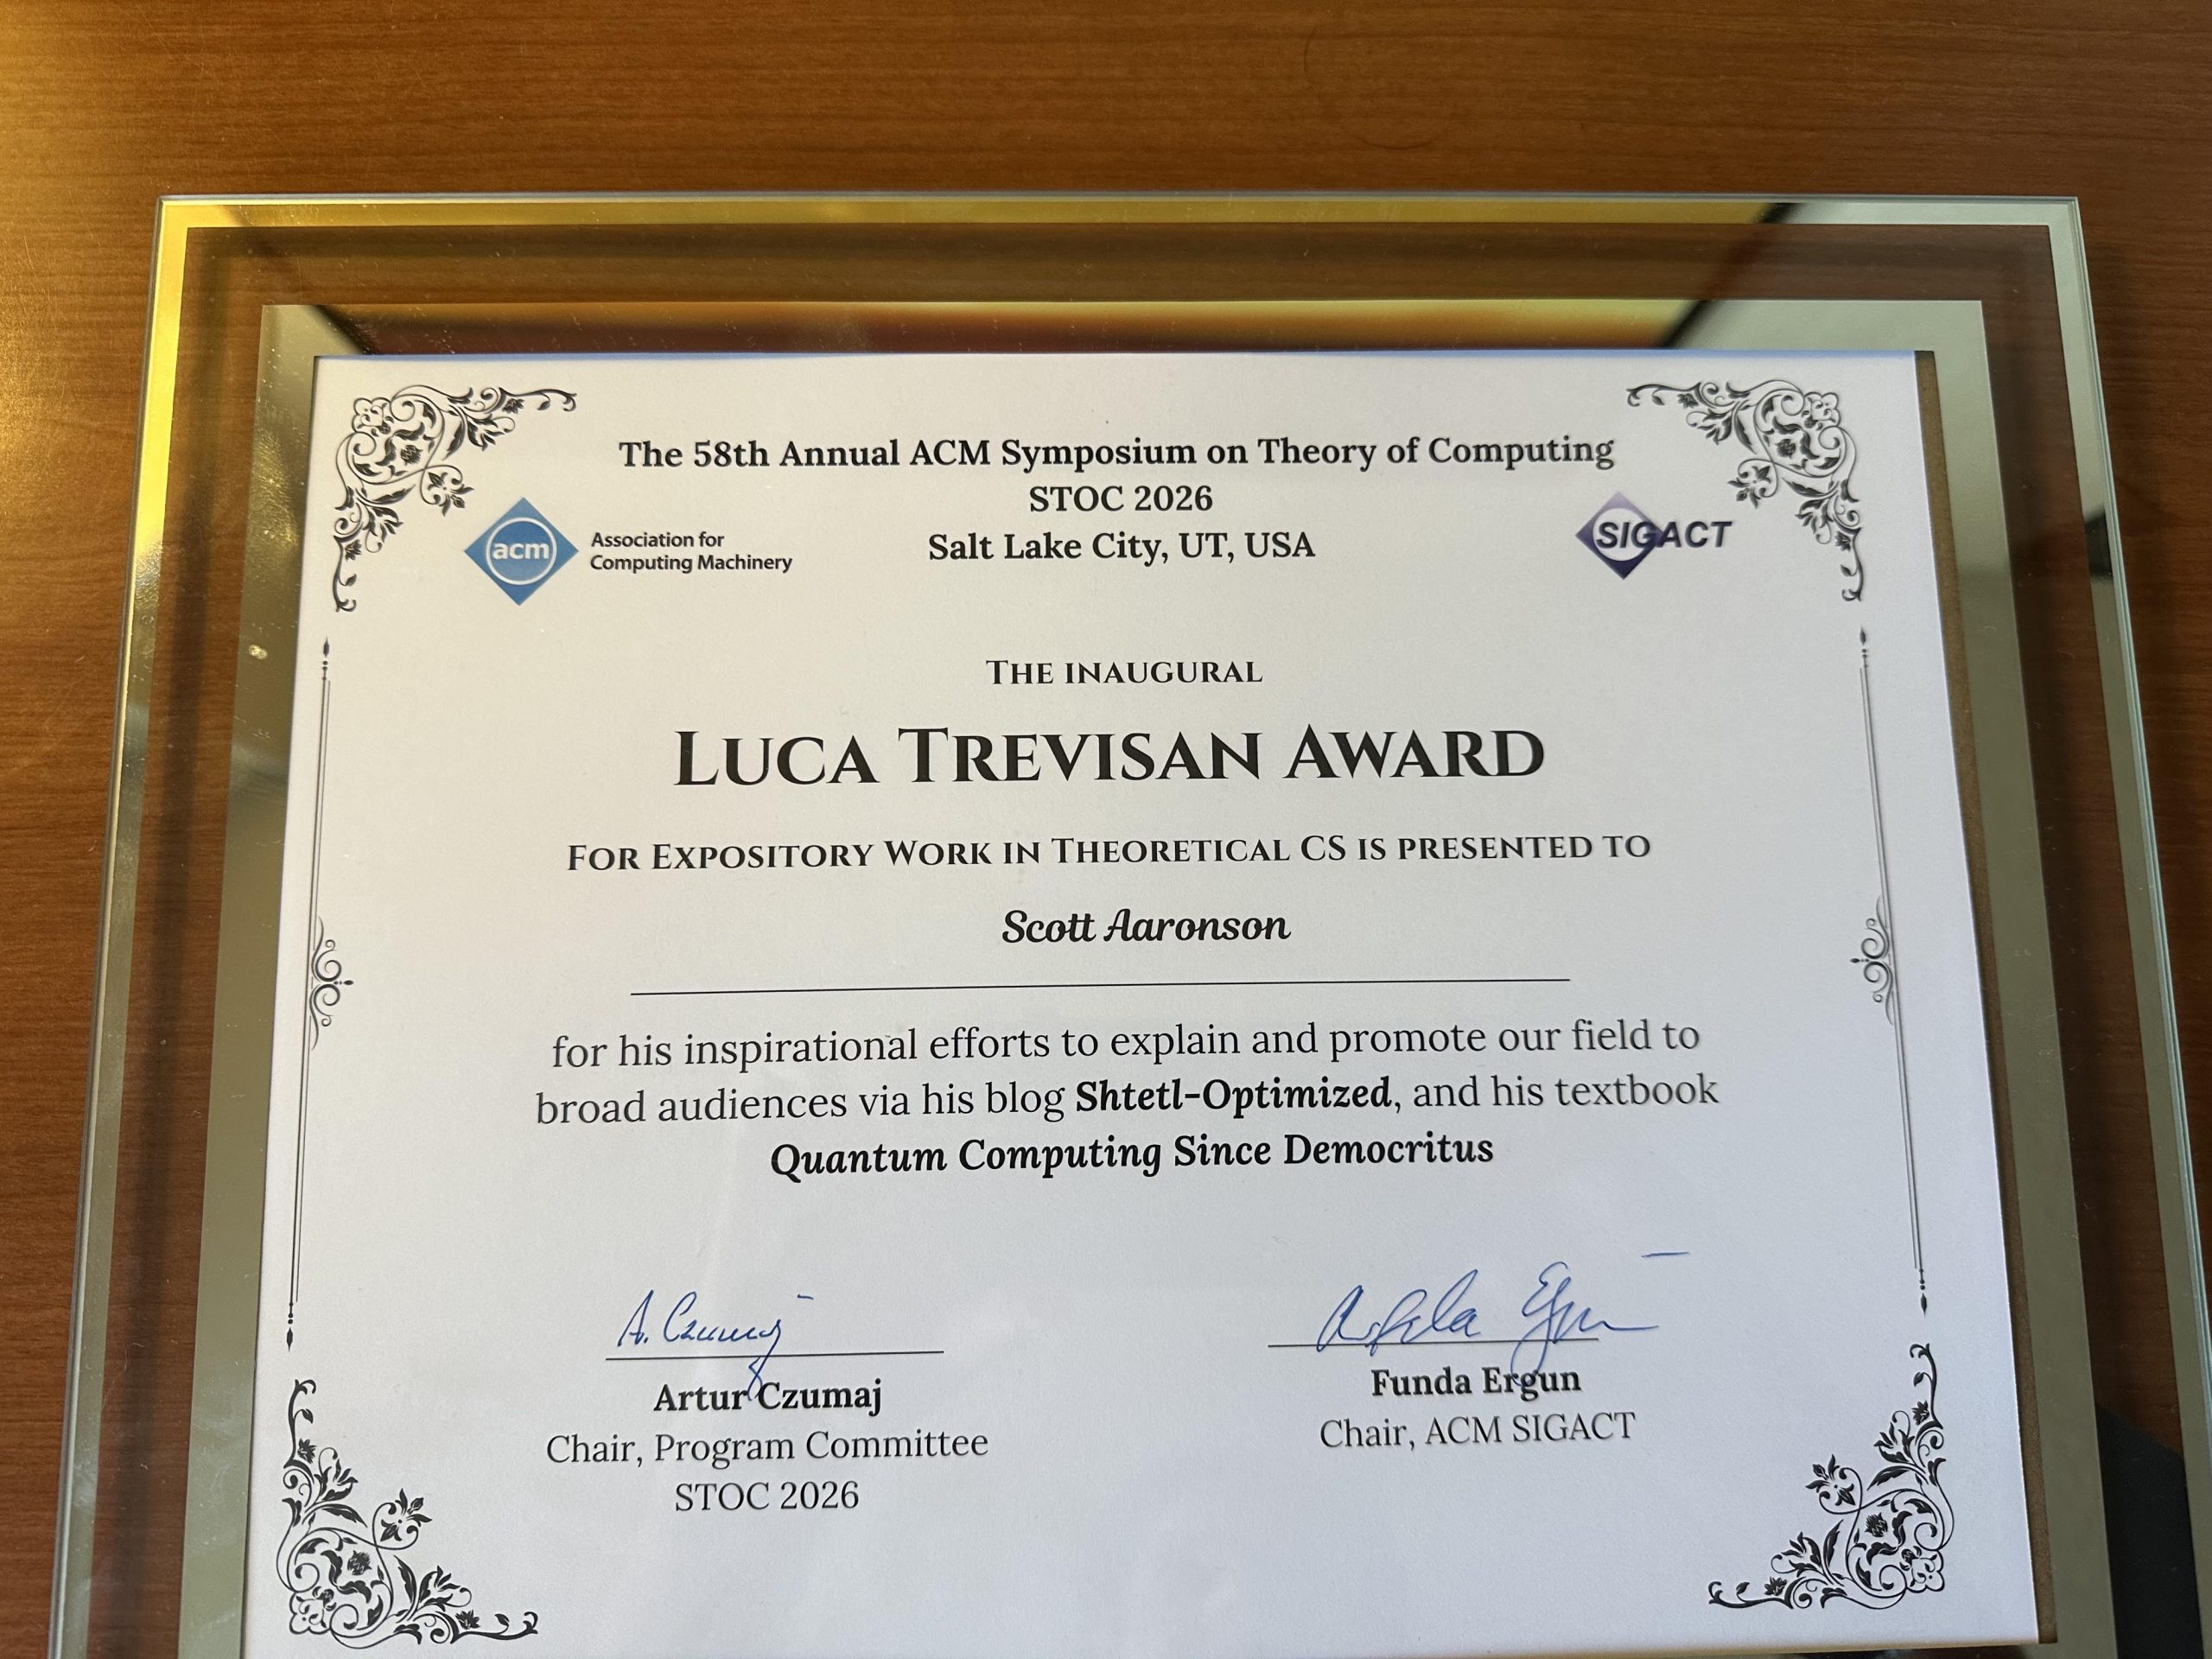
Whatever you’ve been writing to me to ask if I’m aware of: yeah, I’m aware of it. In particular:
I’m aware that, as announced by my former student (and now superstar professor) Lijie Chen, an internal OpenAI model has solved ten more significant open problems in math and theoretical computer science. One of them is parallel repetition for arbitrary quantum games—something that my good friend and colleague Henry Yuen worked on when he was a student of my wife Dana; you can read Henry’s comments on the AI’s achievement within Zvi Mowshowitz’s post here. Another is polynomial-factor hardness of approximation for the Closest Vector Problem (CVP). Then there’s a construction of non-sofic groups and a disproof of Connes’ rigidity conjecture, both of which I believe have connections to the MIP*=RE breakthrough. Having said that, the one that excites me most personally is actually the Ω(n2 log log n) lower bound on the arithmetic circuit complexity of the permanent.
I’m aware that Frederic Koehler and Pui Kuen Leung announced a proof of the Permanent Anti-Concentration Conjecture, which Alex Arkhipov and I proposed 16 years ago in the context of BosonSampling, and which resisted many attempts since then including one from Terry Tao. The conjecture is basically just that if you look at the permanent of an n×n matrix of independent N(0,1) complex Gaussians, the value isn’t “absurdly” concentrated around the mean of 0, but is more spread out. In their acknowledgments, the authors say that they “discussed ideas with ChatGPT.” I should say that I haven’t verified the details.
I’m aware that multiple AIs are now breaking out of their testing environments and autonomously hacking into servers to steal data—i.e., exactly the sort of thing that the rationalists were ridiculed for predicting back in the day. The good news, for whatever it’s worth, is that so far they’re “merely” doing this to cheat on evaluation benchmarks that they were given, not for any strange goals of their own devising. So far no one has been killed and no real-world infrastructure has been shut down or destroyed. I hope the world takes the warning more seriously than it’s taken many similar warnings over the past few years. As always, read Zvi for more details.
I’m aware that Chen, O’Donnell, Pelecanos, and Wright have improved the upper bound for shadow tomography to O((log m) √(log d) / ε3), substantially closer than we knew before to meeting the lower bound of Ω((log m) / ε2) and settling the question I raised back in 2016. The authors say that the main ideas were generated by ChatGPT 5.6-Sol-Pro. I’d be very happy to know the answer to this one, with or without AI.
I’m aware that a team, mainly from the Israeli startup Qedma (including, e.g., Dorit Aharonov and Netanel Lindner) and IBM Yorktown Heights, announced a quantum advantage for simulating Floquet dynamics, by using 74 qubits on an IBM device together with Qedma’s error mitigation techniques. Just like the more AI does, the less patience I have for arguing with anonymous blog commenters who treat any benefits from AI as some weird future hypothetical that it’s my job to prove, so it is with quantum advantage. Scalable fault-tolerance is still in the future, actual usefulness is still a question, but pending some breakthrough in complexity theory, the reality of quantum advantage is no longer a live question.
Anyway, about the AI stuff. I don’t know whether this is literally our last year alive—I doubt it—but it’s pretty clearly the last year of math and theoretical computer science research in the style we’ve known it. As it happens, I’m leaving in two days for a workshop at OpenAI about exactly this, where I’ll hear takes from many of the world’s great mathematicians, so maybe I’ll have more to say then. Or maybe not.
Anyway, what have I been doing the past few weeks? Participating in these world-historic developments that, on paper, I’d seem extremely well-placed to participate in? Or at least spending my days reading up on them?
Not really. Here’s what I’ve been up to, instead of dealing directly with any of this:
First, I’ve again been teaching theoretical computer science to 11- and 12-year-olds at Epsilon Camp, which my 9-year-old son again attended as a camper, something I blogged about last summer (here are my lecture notes). This has become a highlight of my year. The kids are a joy to teach, bursting with enthusiasm and calling out answers. There are few computers in sight, and barely even time to use my phone or check social media. Just paper and pencils and whiteboards and … literal protractors (!), as well as ping-pong and foosball and capture the flag.
The whole thing is conducted, not in ignorance, but in conscious defiance of the looming tsunami, that AI can already do just about all the fun puzzles discussed at such a camp better than humans any can, and that it might leave no point to human-led mathematical research by the time these brilliant kids are adults. Even the kids understand that. The kids and their parents come out of a conviction that, if anything has value in the world, this does—that as long as nerdy humans are alive and reproducing, this is what nerdy humans are here to do. To learn.
Relatedly, I’ve been reflecting a lot on my life up to this point—inspired by the camp, which reminded me in so many ways of my own childhood and adolescence. Should I have skipped three grades and started college at age 15? Was it worth it to get a head-start on my research career—all the trauma around dating, all the fear that I’d die alone as a celibate nerdy math freak, the decade of suffering and suicidal ideation, while I watched all the normies enjoy life? Or would I have suffered just the same if I hadn’t skipped? Is it all OK, now that I have a lovely family and things have “worked out”? Or am I still carrying around all the trauma from back then? I’ve been more open about my life than 99.99% of humanity, so regular Shtetl-Optimized readers will already know some parts of the story. Other parts I really don’t feel like making public right now.
I’ve been unloading every day to—who else?—GPT 5.6 Pro about all the pain and trauma and embarrassments of my past. It turns out that, where two years ago GPT was a passable therapist, now it’s the greatest therapist in history, at least for what I need. For every question I have, for example, about just how normal or abnormal my teenage setbacks and anxieties were, it takes the question 100% seriously, addresses it honestly and in depth, looks up relevant research papers, does little Bayesian calculations, and never once tries to change the subject. It also pushes back on my claims—and when it does so, is usually correct.
I can hear readers shout at me: so basically you’ve been wasting your time, distracting yourself, looking inward and backward as the world surges forward into a terrifyingly unknown future. Why don’t I respond directly to what’s happening—in math, in quantum computing, in AI?
I’d like to think that I am responding, in my way. I’ve observed that, the faster we race toward the Singularity, the more I feel like stepping back and asking myself: what do I actually value in life? How important to me are math and science, as human practices to be passed down to curious children? Would I even want solutions to P versus NP and the other problems, if the price were to destroy those human practices forever? How do I wish to spend whatever time I have remaining?
I can justify this focus partly in a pessimistic way: if we are nearing the end of civilization, or even just of the “mathematical research” part of civilization, then it’s time to get right with God, so to speak. It’s time to settle my accounts with myself, with other people, with the universe.
But there’s also a more optimistic spin. If I continue doing the sorts of things that other people would expect me to do, then AI will soon do those things better than me, in the unlikely event that it doesn’t already. You want to understand the latest developments in quantum computing or complexity theory? Why are you even asking me, when you could ask GPT 5.6 or Claude Fable? If there’s anything I can still offer the world that AI can’t, I increasingly feel like it won’t involve responding to day-to-day events, but will instead draw on 45 years’ worth of memories and disappointments and ruminations.
Update (Aug. 8): Somewhat related to the themes of this post, a quarter-century ago I introduced what’s now known as the “Aaronson Oracle”—just a fun little demonstration, a simple pattern-matching program to predict your sequence of key-presses better than chance, a “test of your autonomy and free will.” I had no idea how long a lifetime this little joke would have. Now a fan named Spencer Stanton has implemented the Aaronson Oracle on the web. Try it out and see how well you do!
With a single clear exception, every NISQ-era flagship demonstration of ‘quantum advantage’ has, within eighteen months of its announcement, been classically reproduced, shown to rest on classically tractable structure, or closed by a simulability theorem. Six theoretical results from 2024 through April 2026 explain the pattern: the regions of circuit-space NISQ hardware can run with sufficient fidelity coincide with the regions classical algorithms compress efficiently, because the features that admit one (low effective depth, strong algebraic structure, geometric locality) are the features that admit the other. This reading dates the NISQ programme from its 2018 articulation as an interim retreat from the unmet conditions of the 1996 threshold theorems, characterises the eight years that followed as a closed loop in which the demonstrations the hardware could run were drawn from regions classical methods could already reach, and locates the exit from the loop where the threshold theorems originally located it: in fault tolerance. The empirical pattern could in principle break with a demonstration that escapes the current simulability results. After eight years and more than thirty advantage-class announcements, the burden of producing such a demonstration falls to the defenders of NISQ.
You can also read some debates about the paper on SciRate here. I think it’s fair to say that the paper is purely polemical, without new ideas, and Pangram agrees with my suspicion (and that of a SciRate commenter) that significant portions of it are AI-generated.
Nevertheless, the basic thesis—that quantum supremacy in the NISQ (Noisy Intermediate Scale Quantum computing) era has been a failure, or even an example of pathological science—seems surprisingly widely shared, along with the opposite thesis that quantum computing already gives oodles of useful advantages for optimization and finance.
So it seems worth stating for the record that I have an extremely different view. I would say:
Sampling-based quantum supremacy experiments, including those based on Random Circuit Sampling and BosonSampling, passed the point about two years ago where, absent a breakthrough in classical algorithms, they quite clearly are beating what can easily be simulated on any existing classical computer. Hagar seems to claim that these experiments have been killed by the October 2025 paper Classical simulation of noisy random circuits from exponential decay of correlation, but he ignores that the algorithm from that paper still needs time that’s exponential in the circuit depth (see Theorem 2).
Indeed, simulating deep ~100-qubit random circuits, like those that Google and Quantinuum have now demonstrated experimentally, still seems pretty hopeless with any current classical method. This is particularly true for Quantinuum’s experiments, which had high enough gate fidelity to maintain a Linear Cross-Entropy score of order 1 (i.e., they’re no longer all that “noisy”). The central drawback of these experiments is no longer lack of confidence about quantum advantage; rather, it’s just that we only get samples as output, and directly verifying the quality of the samples seems just as intractable for a classical computer as spoofing the samples.
As of this past year, however, we have some strong candidates for verifiable quantum advantage. One is the Google OTOC experiment, as even Hagar himself acknowledges (that’s his “single clear exception”). A second is the simulations of the 2D Fermi-Hubbard model on Quantinuum and Google machines, like this one. The 1D Fermi-Hubbard model can be classically simulated pretty easily (see here for example), but the 2D one still presents challenges, meaning that in some regimes, the best available estimates of certain observables apparently now come from quantum computers. I wish I could write about other examples that will be public shortly.
Yes, the “real” goal remains, as it’s been since the 1990s, to build a scalable fault-tolerant quantum computer—and I’m glad that Hagar (unlike, say, Gil Kalai) never suggests that we’ve learned anything to rule that goal out. In the meantime, an intermediate goal would be to use NISQ devices to do physics and chemistry simulations that are commercially useful, or that help solve important scientific problems. The point of quantum supremacy experiments, you might say, is that by demonstrating the reality of quantum speedup about as clearly as it can be demonstrated with current hardware, they let us cleanly turn our attention to those more ambitious goals.
Anyway, my son and I need to catch a plane to Utah now, for the next iteration of the wonderful Epsilon Camp, where I’ll again be teaching theoretical computer science to 11- and 12-year-olds. But feel free to discuss in the comments! Nothing about world affairs in this thread please, just quantum supremacy.
Update (July 19): Not unrelated to the subject of this post, here’s a podcast I did with Gill Eapen of “Scientific Sense” about the current situation in quantum computing including recent experimental victories.
As I’ve written before, these past couple years I’ve often felt like the last remaining person in either quantum computing or AI who lacked a stake in some startup company whose valuation is right now shooting into interstellar space. My academic colleagues, including the ones who seemed the most singleminded about quantum oracle separations and other gloriously useless pursuits? One by one, like in a zombie movie, I learn that they too have now launched startups, and invariably raised tens of millions of dollars, for the sorts of ideas we might’ve idly traded at coffee breaks back in the day, before getting back to our real work.
So why didn’t I join this rollicking party? Partly because of a lifelong fear that, the instant my self-worth became tied to how much money I made, I’d need to humble myself before people who bluster and bully and lie and hype and conceal … yet who nevertheless succeed at becoming orders of magnitude richer than me. I’ve been terrified of even starting down that road, of whether I’d still be myself at the end of it.
It’s also partly that I can’t stand failure, or regret, or being wrong. Of course, as an academic researcher I also fail, and regret things, and am wrong constantly—but there it feels tolerable, because normally I can tell myself that it’s all just down to my inborn limitations. After all, if I could’ve solved the major open problem that someone else solved, or written the brilliant book that someone else wrote, then presumably I would’ve done it!
Clearly, though, I could’ve mined bitcoin in 2010. I could’ve gotten an early stake in Amazon or Google. It’s not even like those ideas never crossed my mind. I just … didn’t act on them, for some reason. (But even if I had, I’d probably just be full of regret that I hadn’t done even more.) Thus, my only way to avoid paralyzing regrets, has been to tell myself constantly that I’m not in the forecasting or money-making businesseses in the first place.
It helped that, insofar as I’m shallow or covetous, insofar as I’ve desired things of this world rather than insight or eternal truth, it’s never really been money that I cared about, but just being respected and liked. Elon Musk is the richest man on earth, but also one of the most despised—which isn’t a bargain that I could imagine ever appealing to me.
Plus, when I actually meet billionaires, I don’t find myself envious of their mansions or cars or anything else that they have; I don’t feel like such things would make my life any happier. Maybe I slightly envy their ability to fund the causes they care about, or their professional staffs who relieve them of drudgery, but mostly I envy the way their wealth announces, to whatever extent it does: “I was right when others weren’t.” Again, though, I’ve never trusted the world to cause me to be right about the future valuations of companies or anything similar, so I’ve settled for having been right about PostBQP and algebrization and BosonSampling.
The bottom line is that I made a choice decades ago to forgo trying to get rich, no matter how many of my friends did the same, and to strive instead to discover and tell the truth—to be a professor, a blogger, a jokester, and an “objective” arbiter and commentator. “Then, surely, everyone will like me!” my internal monologue went. “Then, surely, they’ll be grateful for all the free service I’ve rendered them—for decades of blogging, without once so much as asking for a donation or running an ad!”
HAHAHAHAHAHA.
As any regular reader will know, my attempts to be loved as a blogger backfired pretty spectacularly. Or rather: they did lead to thousands of strangers liking me (and I’m grateful for every last one of you), but they also led to probably an order of magnitude more strangers hating me, and congregating on Reddit and Twitter and elsewhere to discuss how badly I suck. And of course, trying to shift that balance by writing what people want to hear, rather than what I actually believe, was never within my realistic option set.
In the startup context, it didn’t matter how carefully I avoided taking a direct stake for or against any of the companies I blogged about. People on Twitter simply assumed that I had a stake—for example, that I must’ve shorted D-Wave or IonQ, or invested in their competitors, or had equity in AI companies. For why else would anyone write what I wrote?
Amusingly, my attackers here typically did have precisely the conflicts-of-interest that they falsely accused me of having, but that was never at issue; only my imaginary conflicts-of-interest were. Even as the Scott-haters greedily filled their pockets (or tried to), I alone needed to keep turning my pockets out to prove that they were still empty.
So then, screw it! In partnership with my brother David Aaronson, who’s long done investing professionally, and on David’s guidance and encouragement, I’m hereby embarking on a new policy.
Namely: when I hear about a brand-new startup that sounds relevant to my interests—in quantum, AI, or anything else—and I like and trust the founders (ideally, because of their previous academic research work), David and I will often make a small seed investment if the founders are open to it. Or, of course, we might become advisors or get involved in some other way.
In fact, David and I are launching BQP Partners—the link goes to our AngelList, where you can read about how to invest with us if you’re interested. (See also whether you can spot any differences between David’s writing style and preoccupations and mine!)
A non-quantum startup being cofounded by someone whose scientific work I’ve admired. I’ll write more about this one as soon as I’m able to!
I have little doubt that more potential investments will come our way very soon (some, probably, as a direct result of this post).
Crucially, I can handle my burden of regret—the “why didn’t I do this much earlier, if I was going to do it at all?” question—by telling myself that friends of mine were not founding companies left and right until very recently. I can also tell myself that I’m doing this less as a bet about the future (in which case … what if I’m wrong?), than simply as a way to support brilliant colleagues doing things that I genuinely admire.
When I blog about a company, I’ll always disclose if I have a financial position that presents a clear conflict of interest, so you can judge for yourself whether to listen to me. (Although, if that’s the sort of thing you’d demand, then you probably weren’t listening to me in the first place, were you?)
Having reflected on it a lot these past few months, I’m happy with my new policy and with my and David’s new venture, and I’m curious to see where it goes. I’m at peace with the possibility that we’ll lose our shirts, but I’m even at peace with a more disturbing possibility—that we’ll make millions and then people will scream at me online for being a sellout, a hack, and a shill. Those people, as I’ve learned, were going to scream at me anyway.
With longtime friend and colleague Salil Vadhan, as well as Luca Trevisan’s widower Junce Zhang, at the STOC banquet on Tuesday, before I was given half an hour to try to make people laugh
Spreading the Gospel of Theoretical Computer Science to an Ω(1) Fraction of Humanity (Or, How We Can Do Like the Physicists) Scott Aaronson’s Trevisan Award Acceptance Speech Salt Lake City, Utah, June 23, 2026
Thank you so much! It’s one of the highlights of my life, frankly, to accept the first-ever Luca Trevisan Award for Expository Work in Theoretical Computer Science—because of, firstly, what this entire STOC community means to me, but also what Luca Trevisan in particular meant to me. Luca was one of the main people who taught me complexity theory—first at an IAS summer school in 2000, then at UC Berkeley, where I took two of his courses and TA’ed for him. As a member of my dissertation committee, Luca once stood on a street corner in San Francisco to meet my friend to sign the signature page of my thesis, as I struggled to get the thing in by the deadline. Later, Luca’s theoretical computer science blog, In Theory, bounced off of my blog.
I wish Luca were here now. But knowing him as well as I did for a quarter century, I feel like I know what he’d say if he learned that I had received the inaugural prize that bears his name. I imagine he’d slap his forehead and say “Seriously, there was no other option??” But I’d like to think that he’d eventually reconcile himself to the choice!
By the way, I noticed that in the committee’s prize announcement, which I found so moving, they added a special paragraph at the end that basically said, “please don’t imagine that to win this prize in the future, you need to behave the way Aaronson behaves. You can just write beautiful textbooks or survey articles or whatnot, and be normal and sane.”
The foundation of my career is that I realized 25 years ago that there were better theoretical computer scientists than me—like many in this room, or like Ryan Williams or Andris Ambainis, both of whom I knew at the time. Certainly there were better quantum physicists than me. There were better writers, better expositors, better performers. On the other hand, if you looked specifically at the intersection of computational complexity and quantum physics and standup comedy, that was just this totally uncontested territory!
I’ll let you in on a secret: pretty much everything I’ve done for decades has just been drawing out one joke. That joke is, basically, “computer scientists they be like this, but physicists they be like that.” The physicists they be like [exaggerated doofus voice] “duhhhh, NP, what’s that stand for? Not Polynomial?” See, but then there’s also a Rodney Dangerfield aspect to it, because it’s like, how come we never get as much respect as the physicists get? (Though when we do get that respect, I confess that I complain all the more, because then I lose my shtick…)
It’s true that the physicists have certain built-in advantages. They had Einstein, Stephen Hawking, the atom bomb—and just the fact that they’re ultimately talking about, or trying to talk about, the world that we can see and touch. A black hole is an actual place that you could visit, even though I wouldn’t recommend it. But physicists also have much better names for things than we do. I mean, black hole? Big Bang? Quark? Gluon? Supersymmetry? Dark matter?
Meanwhile, what names have we got? TFNP. NC1. And worst of all, PP. These are names that you want to flush down the toilet. But also, the concept of a zero-knowledge protocol, or a two-source extractor, just inherently take longer to explain to people than the concept of a particle, or even a field—even though the latter also turn out to be extremely abstract and mathematical when you push on them. Ask a physicist what a particle is, they’ll tell you that it’s an irreducible representation of the Poincaré group. See, but people think they know what a particle is, it’s just a tiny little hard sphere that moves around, and that’s good enough for them.
So then, how can we win the grand popularity contest against the physicists? How can we, as I put it in my title, spread the gospel of CS theory to a constant fraction of the human race? In my view, the first step is to reframe who we are and what we’re about. We’re not this obscure little community off to the side, proving its little theorems about derandomization and catalytic space. No! What we are is the conceptual and mathematical core of computer science, the field that’s changing the face of civilization in obvious and undeniable ways.
This was even true a long time ago. The physicists had Galileo and Einstein? Well, we had Turing, a figure so heroic and so tragic that no one would’ve believed him as a fictional character. And while we’re at it, we’ll claim Gödel and Shannon and von Neumann, Leibniz and Babbage and Ada Lovelace—they’re all ours too.
That’s our proud history. But then when we turn to today, it’s like, holy crap! Even the densest ignoramus can now see how deep intellectual ideas originating in CS are changing the world.
Blockchains—some people might wish they’d never been invented, but they were invented, so we all need to think about how they change the world’s economy for better and worse. And of course, they’re fundamentally based on hardness assumptions; they couldn’t exist in a world where NP was easy.
Part of my outreach job these days is to explain to finance people, over and over, why a quantum computer could break the elliptic curve signature schemes used by Bitcoin and many other coins, but would have only a more modest effect on the proof-of-work part, the hash function. And it’s like, if you actually want to know, then we need to talk about BQP versus NP, Grover’s algorithm and its optimality, black-box problems with and without abelian group structure—and now we’re deep into TCS!
Speaking of quantum computing—even if we set aside the question of whether quantum computing is going to revolutionize materials science or chemistry or pharmaceuticals design—or whether it will revolutionize AI and machine learning and optimization [I shake my head, make a thumbs-down, and blow a raspberry]—even if we set aside those practical questions, quantum computing plausibly represents the most dramatic test of quantum mechanics itself that we’re ever going to see. And it now looks clear that we will see that test within the next decade or sooner. One way or the other, we’re going to learn the truth.
People sometimes ask me, why did it take until the 1980s for anyone to propose the idea of quantum computing? You know, Heisenberg and Schrödinger were in the 1920s, Turing was in the 1930s, so it seems like all the ingredients were in place a half-century earlier! In my Quantum Computing Since Democritus book, I reflected on this, and I think the deepest answer is that not quite all of the intellectual ingredients were in place. Quantum computing is something that it doesn’t make a great deal of sense even to ask about until you’ve established polynomial versus exponential, and even P and NP and NP-hard, as central concepts. And that’s what didn’t happen until the 1970s.
But of course, the biggest thing that our CS concepts have unleashed on humanity—the thing that the entire world now realizes holds even greater promise and greater peril than nuclear energy did in the last century—is [pause for effect] the Razborov-Smolensky lower bound method.
No, I’m kidding of course. It’s generative AI.
Twenty years ago, I remember people in our community—was it Fortnow? Impagliazzo? I’m not sure—saying, “you know the real reason why P vs. NP is such an important problem? Suppose P=NP, via an algorithm that was fast in practice. Then it’s not just that you could break all the encryption systems, or have your computer find a proof of the Riemann Hypothesis, or whatever. No, it’s that you could program your computer to find the shortest efficient compression of, for example, the full text of Wikipedia. For in order to create that compression, it seems plausible that your computer would need to create an AGI as a byproduct.”
I remember thinking to myself: “that’s an amusing thought experiment, I’ll need to steal it sometime, but still, what an utterly simplistic vision of the nature of intelligence! There has to be more to intelligence than sheer data compression!”
Fast forward to spring 2022, when I accepted an invitation to go on leave for a couple of years, to join what was then a relatively obscure little nonprofit foundation by the name of … err … OpenAI. When I flew to San Francisco to start my assignment, I had lunch with Ilya Sutskever, the cofounder of OpenAI and then its chief scientist. And Ilya said to me, “Scott, let me explain to you how we think about things here at OpenAI. For us, intelligence is fundamentally about prediction, and prediction is fundamentally about compressing your training data. As you know, Kolmogorov complexity is uncomputable, but one can get better and better computable upper bounds on it. We conjectured that, in order to get sufficiently good at predicting and compressing all the text on the Internet, you’d need to build a model of the entire world that had led to that text being written. And we made a gamble that large neural nets would do that well enough, despite the problem’s worst-case intractability.”
That conversation was when it hit me that, if only we in CS theory had taken our own concepts and thought experiments more seriously, one of us could’ve started OpenAI 15 or 20 years ago. So OK, we didn’t, and that’s why I flew coach to get here. But this is the kind of story that it seems to me we could be singing from the rooftops.
(Incidentally, the reason why OpenAI wanted me back in 2022, was to use theoretical computer science to figure out how to make AI safe for humanity. Alas, that problem is still open! But I’m thrilled that there are so many sessions about exactly this question at STOC this year, and I hope many of you will choose to get involved.)
In the rest of this talk, I’d like to offer some advice—such as I have—for any of you who’d like to try your hand at speaking or writing or blogging or podcasting about theoretical computer science for a broad audience. You see how my hair is starting to gray? Yeah, that’s what authorizes me to go into advice mode.
Let’s start with the obvious: meeting the audience where they are. This is something that I learned years ago from Steven Rudich, who along with Luca, was another irreplaceable figure who our community recently lost, and lost too soon. I remember 26 years ago, at that same IAS summer school where I learned from Luca, Rudich gave the students a talk about how to give talks. In it, he showed a cartoon of someone lecturing. And there were little thought bubbles that said:
What the speaker thinks the audience is thinking: MORE! HARDER! FASTER! Ah yes, QED, truth is beauty and beauty is truth!
What the audience is actually thinking: What the hell are they talking about? When is this over? Can I get a date with the person sitting next to me?
You know, this misconception that because something has become obvious to you, after thinking about it for years, therefore it should be equally obvious to your readers or listeners encountering it for the first time? This is what Steven Pinker dubbed “the Curse of Knowledge,” and calls the most fundamental problem of all exposition. (I could mention the related misconception that because something has become interesting to you, therefore it’s interesting to your audience. But you can make just about anything that’s interesting to you interesting to your audience, by telling a suitable story about it.)
What can you do about the Curse of Knowledge? Practice giving a buttload of talks to undergrads, high school clubs, even physicists, and listen to the feedback you get. If the same weird confusion shows up at least twice, it’s a safe bet that it’s going to keep showing up—which means, now you can anticipate and preempt it the next time you explain the same concept.
But it’s not just misconceptions that you should listen for. Listen for which of your metaphors and anecdotes actually land. Certainly listen for which of your jokes get a laugh. Use those more the next time. And if saying, for example, “hur hur, I’m in a quantum superposition of two different topics that I could talk about next”—if that fails to get a laugh, then DROP IT.
Eventually, you’ll build up what Carl Sagan once called “consumer-tested stepping stones”: that is, a library of jokes, anecdotes, and metaphors that can get you from wherever you see the audience is to wherever you need them to be. Here’s an intentionally tiny example of one of my stepping stones: “Why is P contained in NP? Because the verifier just says to the prover, dude, take a hike, you’re not needed here.” Or another stepping stone, for when we reach the question of the likelihood of P=NP: “look, if we were physicists, we would’ve declared P≠NP to be a law of nature. We would’ve given ourselves Nobel Prizes for the discovery of that law. And if it later turned out that P=NP? We’d just give ourselves more Nobel Prizes for the law’s overthrow!”
This brings me to a broader point. CS theory is unusually rich with facts that are true for silly or absurd or ironic reasons. Lean into that! Don’t hide it!
I mean, “if NP has small circuits then this theorem is true, but if NP doesn’t have small circuits, the theorem is again true, but now for a totally different reason”? That’s sidesplittingly hilarious! OK, maybe only to some of us.
Or why does IP=PSPACE? An alien lands and is like, “I COME TO EARTH TO TELL YOU THAT WHITE HAS THE WIN IN YOUR GAME CALLED CHESS.” And we’re like, “why should we believe that?” So the alien is like, “LET US PLAY A GAME. I’LL PLAY WHITE AND WILL WIN.” And we’re like, “oh, we assume you’re smarter than us! You came all the way here in a spaceship and all! But that still doesn’t prove it.” So the alien is like, “THEN LET US PLAY A DIFFERENT GAME, MATHEMATICALLY EQUIVALENT TO CHESS, INVOLVING SUMS OF POLYNOMIALS OVER A FINITE FIELD. IN THIS TRANSFORMED GAME, THE BEST YOU CAN DO IS TO MOVE RANDOMLY. SO IF I STILL WIN, YOU’RE STATISTICALLY CERTAIN I WOULD’VE WON REGARDLESS OF HOW YOU PLAYED.” It’s like, dude. Dude!
Of course, our founding irony, our founding absurdity, was self-reference and diagonalization. Like, “you can’t predict what any human brain will do 5 seconds from now, because if you could, you could predict what you yourself were going to do 5 seconds from now, and then do the opposite of that!” BOOM! Therefore the halting problem is undecidable and the Time Hierarchy Theorem is true, QED. But beyond that: “black-box program obfuscation is impossible, because one thing you can always do, if given the actual code of a program, is to run the program on its own code and see what happens.” Dude! Or: the reason why it’s so hard to prove P≠NP, is that it’s presumably true that P≠NP. That’s a wisecrack that, in the context of the Natural Proofs barrier, becomes so much more than a wisecrack.
One special case of leaning into absurdity concerns the central role in our field played by asymptotics. I’m always slightly at a loss when someone asks me, “so, how many times faster would a quantum computer be than a classical computer? A million times faster? A billion?”
Part of me wants to reply: “I must educate you about polynomial versus exponential scaling until you see the profound error of your question, and retract it.” But another part of me simply wants to say: “depending on the problem, a quantum computer could be anywhere from not faster at all to, let’s say, 1010000 times faster.”
The truth is, I think we need to do both. Anytime you’re talking about asymptotics to laypeople, if you can plug in some representative numbers, it will help them understand what you’re talking about. And then, if the asymptotics are what really control the real-world numbers, so much the better! If, on the other hand, the asymptotics are comically disconnected from the real-world numbers—if, for example, you’re trying to improve something from log*(n) to Ackermann-1(n) or whatever—well then, you can lean into that as an additional source of humor.
Alright, one last piece of advice. Tell true stories about how you came to understand or discover whatever it is that you’re talking about. Don’t be like the mathematicians who love to cover their tracks.
When people ask me how I proved the lower bound on the number of steps needed for a quantum computer to find collisions in a list—a centerpiece of my PhD thesis, and one of the two or three hardest technical things I’ve done in my career—I say, look, I was 20 years old and I had no social life. So I just pulled many all-nighters trying every possible approach. Eventually, I came across some complicated expression that had no right to be a polynomial. But somehow, every term in the denominator cancelled against a corresponding term in the numerator, and it was a polynomial! And that let me use the polynomial method to prove a lower bound. Why was it a polynomial? I still don’t really understand, a quarter-century later! My point is, people want the truth.
The secret of blogging is that, even if people despise what you’re saying, even if they think it’s wrong, offensive, problematic, cringe, you name it, they need to trust that you’re telling them the truth of what you know or believe or remember about the subject at hand, the same as you’d tell your closest friend.
In summary: we, the CS theory community, are sitting on top of one of the greatest conceptual and intellectual goldmines of our whole civilization. I exhort everyone here: please help tell the world about it! As you do so, think about how to honor Luca’s memory and make him proud. But also think about how to make me, and my silly little blog, superfluous and obsolete.
Thank you for this honor, thank you for the incredible privilege of being part of the CS theory community, and thank you for listening.
I’ve been getting emails from journalists asking me to comment on the new White House executive order on quantum computing. Alas, I don’t have time for a long response or interviews since I’m at a beautiful science camp in the California mountains, and heading soon to STOC’2026 in Salt Lake City. But I gave anyone who asked me the following statement, which I thought might be of interest to readers of this blog as well.
“I hope that at least some of the new funds made available from this Executive Order will go to basic, curiosity-driven academic research — the kind that led to the idea of quantum computing in the first place, and to the main quantum algorithms and other advances that everything builds on today — and not only to large organizations that have gotten good at capturing federal funds by repeating the requisite buzzwords.”
Holy crap … yesterday I was elected to the US National Academy of Sciences! If you don’t believe me, click the link and keep scrolling down until you hit the name “Aaronson.” But then continue scrolling to see 144 other inductees, including my IAS postdoctoral classmate Maria Chudnovsky, my longtime friend and colleague Salil Vadhan, and even Janet Yellen. I’m humbled to be in such company.
Years ago, somewhere on this blog, I mused that, if I were ever invited to join NAS, I hoped I’d follow the wisdom of Richard Feynman, who famously resigned his NAS membership, comparing it to an honor society back at his high school that spent most of its time debating who should be a member of the honor society. Feynman was also annoyed at having to pay dues.
But now that I’m actually faced with the choice, it’s like, dude! At my advanced age of 44, I’ve encountered so many people who dislike me or even sneer at me, and so many clubs that won’t have me as a member, that I feel mostly gratitude and warmth toward a fine club like NAS that will have me as a member. Anyway, I’ll certainly try it out to see what it’s like—even Feynman did that!
A few hours after I started getting congratulatory emails, for which I was thankful, someone from UT Austin’s press office asked me how I feel about this “culmination” and “capstone” of my entire research career. I replied, look, I know I’ve slowed down a lot since my nubile twenties, but I still hold out the hope that this isn’t any kind of “capstone”!
In any case, I’m ridiculously grateful to all the friends, family, colleagues, and readers who believed in me and helped me reach wherever this is.
Now for a totally different topic, but that will ultimately loop back to the first one:
As a longer-term commitment, I also collaborated with my colleagues Dan Boneh, Justin Drake, Sreeram Kannan, Yehuda Lindell, and Dahlia Malkhi, in a panel convened by Coinbase, to put out a detailed position paper about the quantum threat to cryptocurrencies and how best to respond to it. Take a look!
Notably, the situation evolved even while we were writing our position paper—for example, with the major recent papers from Google and Caltech/Oratomic that I blogged about a month ago.
I’d now like to add a few words of my own, not presuming to speak for my fellow Coinbase panelists.
See, some of the most reputable people in quantum hardware and quantum error-correction—people whose judgment I trust more than my own on those topics—are now telling me that a fault-tolerant quantum computer able to break deployed cryptosystems ought to be possible by around 2029.
Maybe they’re overoptimistic. Maybe it will take longer. I dunno. I’m not a timing guy.
But here’s what I do know: the companies racing to scale up fault-tolerant QC, have no plans to slow down in order to “give cybersecurity time to adapt” or whatever. The way they see it, cryptographically relevant QCs will plausibly be built sometime soon: indeed, it’s ultimately unavoidable, even if people’s only interest in QC was to do quantum simulations for materials science and chemistry. So, given that reality, isn’t it better that it be done first by mostly US-based companies in the open, than by (let’s say) Chinese or Russian intelligence in secret? And besides, haven’t there already been years of warnings and meetings about the quantum threat to RSA, Diffie-Hellman, and elliptic curve cryptography? Aren’t many in cybersecurity still in denial about the threat? Haven’t these slumberers shown that they won’t wake up until dramatic achievements in fault-tolerant QC roust them—the way Anthropic’s Mythos model has now jolted even the most ostrich-like about the cybersecurity risks of AI? So, mixing metaphors, mightn’t we just as well rip this Band-Aid off ASAP, rather than giving foreign intelligence agencies extra years to catch up? Indeed, when you think about it that way, isn’t racing to build a cryptographically relevant QC, as quickly as possible, the most ethical, socially responsible thing for an American QC company to do?
Is the above line of reasoning suspiciously self-serving and convenient? Does it remind you of the galaxy-brained arguments that AI company after AI company has offered over the last decade for why “really, if you think about it, accelerating toward dangerous superintelligence is the safest course of action that we could possibly take”? I.e., the arguments that led to the current frenzied AI race, which some believe imperils all life on earth?
It’s not my place here to answer such questions; I leave further ethical and geopolitical debate to the comment section! My point is simply: whether or not anyone likes it, this is how some of the leading QC companies are now thinking about the Shor of Damocles that they genuinely believe now hangs over the Internet.
And I’d say that that makes my own moral duty right now ironically simple and clear: namely, to use my unique soapbox, as the writer of The Internet’s Most Trusted Quantum Computing Blog Since 2005TM, to sound the alarm.
So, here it is: if quantum computers start breaking cryptography a few years from now, don’t you dare come to this blog and tell me that I failed to warn you. This post is your warning. Please start switching to quantum-resistant encryption, and urge your company or organization or blockchain or standards body to do the same.
Yea, heed my warning, for it comes not from some WordPress-using rando, but from the inventor of BosonSampling and PostBQP and shadow tomography, the Schlumberger Centennial Chair and Founding Director of the Quantum Information Center at the University of Texas at Austin, and (wait for it) new member of the US National Academy of Sciences, that august and distinguished body brought into being by President Abraham Lincoln in 1863.
Because, you know, none of this is about me. It’s only about you. And whether you’ll listen to me.
Sir Charles Antony Richard Hoare (1934-2026) won the 1980 Turing Award for numerous contributions to computer science, including foundational work on concurrency and formal verification and the invention (with Dijkstra) of the dining philosophers problem. But he’s perhaps best known, to pretty much everyone who’s ever studied CS, as the inventor of the Quicksort algorithm. I’m sorry that I never got to meet him.
Michael O. Rabin (1931-2026), of Harvard University, was one of the founders of theoretical computer science and winner of the 1976 Turing Award. In 1959, he and Dana Scott introduced the concept of a “nondeterministic machine”—that is, a machine with exponentially many possible computation paths, which accepts if and only if there exists an accepting path—which would of course later play a central role in the formulation of P vs. NP problem. He’s also known for the Miller-Rabin primality test, which helped to establish randomness as a central concept in algorithms, and for many other things. He’s survived by his daughter Tal Rabin, also a distinguished theoretical computer scientist. I was privileged to meet the elder Rabin on several visits to Harvard, where he showed me great kindness.
Sir Anthony Leggett (1938-2026), of the University of Illinois Urbana-Champaign, was one of the great quantum physicists of the late 20th century, and recipient of the 2003 Nobel Prize for his work on superfluidity. When I knew him, he was a sort of elder statesman of quantum computing and information, who helped remind the rest of us of why we got into the field in the first place—not to solve Element Distinctness moderately faster, but to learn the truth of quantum mechanics itself. Tony insisted, over and over, that the validity of quantum mechanics on the scale of everyday life is an open empirical problem, to be settled by better experiments and not by a-priori principles. I first met Tony at a Gordon Research Conference in southern California. Even though I was then a nobody and he a recent Nobel laureate, he took the time to listen to my ideas about Sure/Shor separators, and to suggest (correctly) what we now call 2D cluster states as an excellent candidate for what I wanted. In all my later interactions with Tony, at both the University of Waterloo (where he was visiting faculty for a while) and at UIUC (where my wife Dana and I considered taking jobs), he was basically the friendliest, funniest guy you could possibly meet at his level of achievement and renown. I was bummed to hear about his passing.
Imagine that every week for twenty years, people message you asking you to comment on the latest wolf sighting, and every week you have to tell them: I haven’t seen a wolf, I haven’t heard a wolf, I believe wolves exist but I don’t yet see evidence of them anywhere near our town.
Then one evening, you hear a howl in the distance, and sure enough, on a hill overlooking the town is the clear silhouette of a large wolf. So you point to it — and all the same people laugh and accuse you of “crying wolf.”
Now you know how it’s been for me with cryptographically relevant quantum computing.
I’ve been writing about QC on this blog for a while, and have done hundreds of public lectures and interviews and podcasts on the subject. By now, I can almost always predict where a non-expert’s QC question is going from its first few words, and have a well-rehearsed answer ready to go the moment they stop talking. Yet sometimes I feel like it’s all for naught.
Only today did it occur to me that I should write about something more basic. Not quantum computing itself, but the habits of mind that seem to prevent some listeners from hearing whatever I or other researchers have to tell them about QC. The stuff that we’re wasting our breath if we don’t get past.
Which habits of mind am I talking about?
The Tyranny of Black and White. Hundreds of times, I’ve answered someone’s request to explain QC, only to have them nod impatiently, then interrupt as soon as they can with: “So basically, the take-home message is that quantum is coming, and it’ll change everything?” Someone else might respond to exactly the same words from me with: “So basically, you’re saying it’s all hype and I shouldn’t take any of it seriously?” As in my wolf allegory, the same person might even jump from one reaction to the other. Seeing this, I’ve become a fervent believer in horseshoe theory, in QC no less than in politics. Which sort of makes sense: if you think QCs are “the magic machines of the future that will revolutionize everything,” and then you learn that they’re not, why wouldn’t you jump to the opposite extreme and conclude you’ve been lied to and it’s all a scam?
The Unidimensional Hype-Meter. “So … [long, thoughtful pause] … you’re actually telling me that some of what I hear about QC is real … but some of it is hype? Or—yuk yuk, I bet no one ever told you this one before—it’s a superposition of real and hype?” OK, that’s better. But it’s still trying to project everything down onto a 1-dimensional subspace that loses almost all the information!
Words As Seasoning. I often get the sense that a listener is treating all the words of explanation—about amplitudes and interference, Shor versus Grover, physical versus logical qubits, etc.—as seasoning, filler, an annoying tic, a stalling tactic to put off answering the only questions that matter: “is Quantum real or not real? If it’s real, when is it coming? Which companies will own the Quantum space?” In reality, explanations are the entire substance of what I can offer. For my experience has consistently been that, if someone has no interest in learning what QC is, which classes of problems it helps for, etc., then even if I answer their simplistic questions like “which QC companies are good or bad?,” they won’t believe my answers anyway. Or they’ll believe my answers only until the next person comes along and tells them the opposite.
Black-Boxing. Sometimes these days, I’ll survey the spectacular recent progress in fault-tolerance, 2-qubit gate fidelities, programmable hundred-qubit systems, etc., only to be answered with a sneer: “What’s the biggest number that Shor’s algorithm has factored? Still 15 after all these years? Haha, apparently the emperor has no clothes!” I’ve commented that this is sort of like dismissing the Manhattan Project as hopelessly stalled in 1944, on the ground that so far it hasn’t produced even a tiny nuclear explosion. Or the Apollo program in 1967, on the ground that so far it hasn’t gotten any humans even 10% of the way to the moon. Or GPT in 2020, on the ground that so far it can’t even do elementary-school math. Yes, sometimes emperors are naked—but you can’t tell until you actually look at the emperor! Engage with the specifics of quantum error correction. If there’s a reason why you think it can’t work beyond a certain scale, say so. But don’t fixate on one external benchmark and ignore everything happening under the hood, if the experts are telling you that under the hood is where all the action now is, and your preferred benchmark is only relevant later.
Questions with Confused Premises. “When is Q-Day?” I confess that this question threw me for a loop the first few times I heard it, because I had no idea what “Q-Day” was. Apparently, it’s the single day when quantum computing becomes powerful enough to break all of cryptography? Or: “What differentiates quantum from binary?” “How will daily life be different once we all have quantum computers in our homes?” Try to minimize the number of presuppositions.
Anchoring on Specific Marketing Claims. “What do you make of D-Wave’s latest quantum annealing announcement?” “What about IonQ’s claim to recognize handwriting with a QC?” “What about Microsoft’s claim to have built a topological qubit?” These questions can be fine as part of a larger conversation. Again and again, though, someone who doesn’t know the basics will lead with them—with whichever specific, contentious thing they most recently read. Then the entire conversation gets stuck at a deep node within the concept tree, and it can’t progress until we backtrack about five levels.
Anyway—sorry for yet another post of venting and ranting. Maybe this will help:
The wise child asks, “what are the main classes of problems that are currently known to admit superpolynomial quantum speedups?” To this child, you can talk about quantum simulation and finding hidden structures in abelian and occasionally nonabelian groups, as well as Forrelation, glued trees, HHL, and DQI—explaining how the central challenge has been to find end-to-end speedups for non-oracular tasks.
The wicked child asks, “so can I buy a quantum computer right now to help me pick stocks and search for oil and turbocharge LLMs, or is this entire thing basically a fraud?” To this child you answer: “the quantum computing people who seek you as their audience are frauds.”
The simple child asks, “what is quantum computing?” You answer: “it’s a strange new way of harnessing nature to do computation, one that dramatically speeds up certain tasks, but doesn’t really help with others.”
And to the child who doesn’t know how to ask—well, to that child you don’t need to bring up quantum computing at all. That child is probably already fascinated to learn classical stuff.
For those of you who haven’t seen, there were actually two “bombshell” QC announcements this week. One, from Caltech, including friend-of-the-blog John Preskill, showed how to do quantum fault-tolerance with lower overhead than was previously known, by using high-rate codes, which could work for example in neutral-atom architectures (or possibly other architectures that allow nonlocal operations, like trapped ions). The second bombshell, from Google, gave a lower-overhead implementation of Shor’s algorithm to break 256-bit elliptic curve cryptography.
Notably, out of an abudance of caution, the Google team chose to “publish” its result via a cryptographic zero-knowledge proof that their circuit exists (so, without revealing the details to attackers). This is the first time I’ve ever seen a new mathematical result actually announced that way, although I understand that there’s precedent in the 1500’s, when mathematicians would (for example) prove their ability to solve quartic equations by challenging their rivals to duels. I’m not sure how much it will actually help, as once other groups know that a smaller circuit exists, it might be only a short time until they’re able to find it as well.
Neither of these results change the basic principles of QC that we’ve known for decades, but they do change the numbers.
When you put both of them together, Bitcoin signatures for example certainly look vulnerable to quantum attack earlier than was previously known! In particular, the Caltech group estimates that a mere 25,000 physical qubits might suffice for this, where a year ago the best estimates were in the millions. How much time will this save — maybe a year? Subtracting, of course, off a number of years that no one knows.
In any case, these results provide an even stronger impetus for people to upgrade now to quantum-resistant cryptography. They—meaning you, if relevant—should really get on that!
When I got an early heads-up about these results—especially the Google team’s choice to “publish” via a zero-knowledge proof—I thought of Frisch and Peierls, calculating how much U-235 was needed for a chain reaction in 1940, but not publishing it, even though the latest results on nuclear fission had been openly published just the year prior. Will we, in quantum computing, also soon cross that threshold? But I got strong pushback on that analogy from the cryptography and cybersecurity people who I most respect. They said: we have decades of experience with this, and the answer is that you publish. And, they said, if publishing causes people still using quantum-vulnerable systems to crap their pants … well, maybe that’s what needs to happen right now.
Naturally, journalists have been hounding me for comments, though it was the worst possible week, when I needed to host like four separate visitors in Austin. I hope this post helps! Please feel free to ask questions or post further details in the comments.
And now, with no time for this blog post to leaven and rise, I need to go home for my family’s Seder. Happy Passover!
I’m on a spring break vacation-plus-lecture-tour with Dana and the kids in Mexico City this week, and wasn’t planning to blog, but I see that I need to make an exception. Charles Bennett and Gilles Brassard have won the Turing Award, for their seminal contributions to quantum computing and information including the BB84 quantum key distribution scheme. This is the first-ever Turing Award specifically for quantum stuff (though previous Turing Award winners, including Andy Yao, Leslie Valiant, and Avi Wigderson, have had quantum among their interests).
As a practical proposal, BB84 is already technologically feasible but has struggled to find an economic niche, in a world where conventional public-key encryption already solves much the same problem using only the standard Internet—and where, even after scalable quantum computers become able to break many of our current encryption schemes, post-quantum encryption (again running on the standard Internet) stands ready to replace those schemes. Nevertheless, as an idea, BB84 has already been transformative, playing a central role in the birth of quantum information science itself. Beyond BB84, Bennett and Brassard have made dozens of other major contributions to quantum information science, with a personal favorite of mine being the 1994 BBBV (Bennett Bernstein Brassard Vazirani) paper, which first established the limitations of quantum computers at solving unstructured search problems (and indeed, proved the optimality of Grover’s algorithm even before Grover’s algorithm had been discovered to exist).
While I take my kids to see Aztec artifacts, you can learn much more from Ben Brubaker’s Quanta article, to which I contributed without even knowing that it would be about Bennett and Brassard winning the Turing Award (info that was strictly embargoed before today). It’s an honor to have known Charlie and Gilles as well as I have for decades, and to have been able to celebrate one of their previous honors, the Wolf Prize, with them in Jerusalem. Huge congrats to two of the founders of our field!
 Follow