Archive for the ‘Complexity’ Category

Talk by Dana Moshkovitz: The Unique Games Conjecture – Proved (!!?)

Friday, October 30th, 2026

In my “Mathocalypse” post, I mentioned that my wife Dana—who’s been working on Subhash Khot’s Unique Games Conjecture since ~2009, for the entire time I’ve known her—has for the past few weeks (while on sabbatical at the Simons Institute in Berkeley) been spending essentially all of her time laboring to understand OpenAI’s recent proof of the conjecture. Having now studied the proof closely in collaboration with Subhash Khot himself, Johan Håstad, Dor Minzer, and other colleagues, and (naturally) GPT-6 Astra, Dana probably now understands this crown jewel of OpenAI’s release as well as anyone does. This week, she gave two well-received whiteboard talks on the proof at Simons Institute. So, I and others encouraged her to give the same talks next week at UT Austin when she’s back here, and Dana agreed! Because of the large timely interest, we’re going to do a live Zoom option, and will also record the talk for later sharing on YouTube. Please note: While all are welcome, this is a 2-hour technical talk. The first hour will review key ideas from hardness of approximation, while the second hour will describe the new construction. —SA


Title: The Unique Games Conjecture – Proved (!!?)

Speaker: Dana Moshkovitz (UT Austin)

When: Wednesday Nov. 4, 3:30-5:30pm US Central (with a brief break in the middle)

Where: UT Austin, Gates Dell Complex 6.302. Live Zoom will be available here, and a recording will be available later.

Abstract: The Unique Games Conjecture of Khot says that it is NP-hard, given a system of linear equations of the form xi-xj=bij (mod p) over variables x1…xn, where 99% fraction of the equations can be satisfied, to find an assignment satisfying 1% of the equations (here p is a sufficiently large constant).

This conjecture implies optimal inapproximability results for many optimization problems. 

A few weeks ago OpenAI released a writeup with a proof of the Unique Games Conjecture, as well as a Lean formalization of the proof. The writeup, like others released that day, is not written in a way that’s especially readable to human mathematicians. 

My goal in this talk is to offer my mental map of the proof, in a way that’s helpful to theoretical computer scientists who are familiar with the area. I think of the innovation as a new code construction, “Hadamard with a noise test.” I’ll sketch how it fits into the NP-hardness reduction. Then I’ll describe the code construction fully and sketch its soundness analysis.    

I’ll also point out a couple of ingredients of the proof that are of independent interest, like a simple quadratic that behaves “like a linear,” and a probability bound using a trick with harmonic numbers.

Podcasts about the Topic: Part II

Monday, October 26th, 2026

As always, I strongly recommend 2x speed, which compensates somewhat for my verbal infelicities!


New! More podcasts keep dropping! This one is with the AI alignment researcher Roman Yampolskiy, about … well, AI alignment, plus the Mathocalypse, plus quantum computing, plus whether the universe is a simulation, and I forget what else! Man do the YouTube comments make me despair of humanity though.


Another one that recently dropped, with Sophia Aryan:


With Curt Jaimungal:

The title Curt put next to my head could’ve been in reference to many, many things! But sorry, he just mean AI. He and I start with the Mathacre, of course, but then we get onto the firewall paradox and then Curt starts asking about computational complexity and the Second Law, and then about Integrated Information Theory.


Ah, and another one that just dropped! Man’s Search for Meaning podcast (recorded in-person in Austin), with Yannick Bernard, who asked me about quantum computing, AI, my personal story, grade-skipping, antisemitism, and I don’t even remember what else. I didn’t refuse to answer anything. (Note: this one was recorded over the summer, which is why I so weirdly omit the latest AI math breakthroughs!)


OK, despite the title of this post, short break from “The Topic.” Here’s an absolute masterpiece of mathematical exposition, from the “Polylog” YouTube channel, which tells the story of the determination of Busy Beaver values through spectacular animations. I play cameo roles in the video, although I embarrass myself (as the video silently points out) by transposing two digits in the value of BB(5)…!


Just for old times’ sake, a short podcast about quantum computing with Danny Li.


And, coming soon (not on YouTube quite yet): a conversation about the Mathacre with celebrated physics popularizer (and character on The Big Bang Theory) Brian Greene, recorded in-person in NYC during my recent trip to speak in the math department at Columbia University!


And to preempt the inevitable comments about it: yes, my students just came to my office to tell me that an OpenAI model has now refuted the Exponential Time Hypothesis, by giving an algorithm to solve 3SAT in an amount of time that scales roughly like exp(n/√log(n)). Even as we struggle to digest the previous courses, the endless buffet continues!

Podcasts about the Topic

Tuesday, October 13th, 2026

“The Topic” being, of course, the Mathocalypse, except sometimes with AI alignment and even quantum computing and complexity theory and other stuff thrown in.

With Ryan Peterman:

Notably, near the end of the above podcast, you can watch my live reaction to the news that an Anthropic model found algorithms for the 3SUM and the All-Pairs-Shortest-Path problems beating records that stood for generations—news that hadn’t yet reached me when I woke up and logged in. (If you don’t feel like watching, my reaction is basically: “uh, wow … if I hadn’t been so overstuffed with delicacies right now from history’s biggest math breakthrough buffet, I’d surely be giving this one the individual amazement that it deserves…”)

And here’s with “Modern CTO”, on a similar set of topics:

Oh, and a third one: MTS podcast with Theo Jaffee.

Enjoy, and thanks to the hosts of these podcasts!


Update (Oct. 19): There’s been a rapid-fire recent sequence of AI-assisted improvements to my 2016 result with Adam Yedidia, showing that the 8000th Busy Beaver number eludes the axioms of set theory. I haven’t even kept track of all of them, but the very latest, by friend-of-the-blog Elliot Glazer, shows that the value of BB(230) is independent of ZFC (see here for explanation).

The Mathocalypse

Wednesday, October 7th, 2026

More Updates (Oct. 12): Jeffrey Ketchersid has used Claude Code agents to show that BusyBeaver(10) exceeds Graham’s number, beating the previous best result that BB(13) does so.

In response to my request, a couple days later Jeffrey also used Claude agents to show that the value of BB(335) is independent of ZFC, improving the best previous result from Andrew Wade that BB(393) is. Recall that the first result in this direction, by me and Adam Yedidia a decade ago, only showed an independence result for BB(8000).

Meanwhile, among the many reactions to the mathocalypse, friend-of-the-blog Kunal Marwaha advocates that we become stewards of a “world mathematical commons.”


Updates (Oct. 9): To address some questions that keep coming up…

No, I’m not aware of any direct practical implications of any of these results. I certainly don’t expect the O(n log0.9999999999999 n)-time Fourier Transform algorithm to get practically deployed anytime soon! But anyone who harps on this, simply doesn’t understand what mathematical progress looks like, or how it eventually pulls the rest of science and technology and human civilization with it. If and when the relevant human mathematicians understood the clever new ideas in all 372 of these papers, I have no doubt that they’d be able to use the ideas to do all sorts of new things, and that some of those things would have practical value. That’s yet another reason to try to keep human understanding at the center of our enterprise—unless, of course, you’re happy to outsource the task of understanding and applying the ideas to AI models as well.

Meanwhile, something calling itself the Association for Human Mathematics put out a statement condemning OpenAI for its release. The statement included a sentence that’s since been widely mocked on social media: “Mathematicians did not ask for this work to be done.” (Imagine G. H. Hardy saying to Ramanujan, “who asked you to prove all these bizarre new identities?”)

If it wasn’t clear, the members of AHM speak for themselves, not for the math community as a whole. For my part, I think the math and CS theory communities should absolutely hold the AI companies’ feet to the fire to behave better, both within our little domains, and (much more consequentially) in pacing AI progress, figuring out alignment, and preventing a catastrophe for our whole civilization. So I’m glad that our communities have increasingly been doing that, and I hope to have played a tiny part.

At the same time, I regard the position “no one should spoil our fun by solving our open math problems using AI models” to be totally untenable. It offers no argument for why refraining would be in the broader public interest—as opposed to various mathematicians’ narrow career interests. It violates the core principle that math problems are there for absolutely anyone (yes, even a hated corporation) to try to solve. And of course, it’s not enforceable anyway, in a world where these capabilities will rapidly diffuse to anyone with a GPT or Claude subscription.

We will need to adapt to this new world.


… then they came for Navier–Stokes and I said nothing because I never worked on Navier–Stokes. But when they came for RL vs. L I realized that things are serious

–friend-of-the-blog Omer Reingold (shared with permission)


Last night my 9-year-old son was taunting my wife, complexity theorist Dana Moshkovitz, as follows: “mommy, I heard you got cooked! I heard that a robot solved the math problem you worked on for your whole career! OOF!”

While my son was being a brat, he also wasn’t wrong. Whether you’re thrilled, depressed, angry, or whatever else about it, yesterday was surely one of the biggest days in mathematical history. And yes, among the 372 huge results released yesterday by OpenAI, on the recommendation of its advisory group of Timothy Gowers, Edward Witten, and other distinguished mathematicians, was a proof of Subhash Khot’s Unique Games Conjecture (UGC), a statement that my wife has worked toward proving for the entire time I’ve known her. (The UGC implies that a whole slew of optimization problems really are NP-hard, even if you just want an approximation that’s slightly better than what you get from semidefinite programming relaxation, which is one of our main tools.)

Or at least, we’re pretty sure that it’s a proof! There’s a Lean certificate, as there are for some of the other 372 breakthrough results (not all of them). But it also appears that no human has understood just about any of these proofs yet; the race to do so has just started. If you want an on-the-ground sense of what that race is going to be like, here’s some of what Dana texted me last night:

It feels like something written by someone who’s on psychedelics. So much unclear and doesn’t make sense. Lots of name dropping of previous work without discussing why it can be used despite impossibility results

Basically the paper is so horribly written that it’s impossible to read it without AI help

I asked Astra for reasonable completeness and soundness claims of the noise gadget and it gave them by combining claims from all over the paper

They also have direct optimal NP hardness of approximation proofs for the main applications of the UGC (Max Cut and all CSP) that bypass the UGC.

The UGC proof invents a completely new bizarre code with a noise test. It’s some crazy recursive construction.

It’s not the long code, not the short code – some alien craziness

I still think that there maybe is a proof that uses the half space code (which is natural)

The citations are often irrelevant and confusing

A possible future is a math world that’s heavenly if you have vision/creative ideas that AI could help check and implement.

And of course there’s a lot for us to learn from the aliens

If you’re wondering what emotions Dana is feeling—well, probably all of them! Even while a central career aspiration has fallen to a robot, there are at least two mitigating factors for her. First, she can feel vindicated that the UGC was true after all, something she never doubted even while many of her colleagues did! Second, all of us in math and theoretical computer science and mathematical physics, at least those who cared about solving crisply-stated problems, are now in the same boat.


Besides the Unique Games Conjecture, here’s a small sampling of the treasures from Aladdin’s cave that I’ll probably be paying the most attention to over the coming weeks:

Any of the above, alone, could easily have been “result of the year” in some area (and in some cases, like Unique Games and L=BPL, in all of CS theory). And there’s a lot that I’ve left out—feel free to share in the comments whatever is making your eyes bug out! There are equally astounding wonders in number theory, combinatorics, algebraic geometry, analysis, and pretty much every other area of math, most of which I’ll never understand, although I’ll note that it includes partial progress toward the Riemann hypothesis and the Hodge Conjecture (retracted because of a sign error!) and the Birch-Swinnerton-Dyer Conjecture (i.e., the majority of the remaining Millennium Problems).

We can take solace in what’s missing from the list. P≠NP isn’t there, nor even P=BPP or NEXP⊄P/poly, and surely not for lack of trying. Apparently the greatest open problems of theoretical computer science are indeed pretty hard!


Oh, lest I forget: one day before the OpenAI dump, meaning Monday evening, Virginia Williams and Josh Alman posted an arXiv preprint that solves the 3SUM problem in O(n1.9992) time, and the All-Pairs Shortest Paths problem in O(n2.9995) time, refuting half-century-old conjectures that the correct answers were n2-o(1) and n3-o(1) respectively. In this case, it wasn’t an OpenAI model that supplied the crucial idea; it was an Anthropic one! But Anthropic then took a different approach from OpenAI: rather than post the undigested solutions to the world, it gave Virginia and Josh the opportunity to write and announce a digested version in exchange for compensation.

These have emerged as the two main models for communicating AI math breakthroughs, and they both have strengths and weaknesses. The “OpenAI model” sets up a crazy race among humans to digest and explain a messy AI proof (work that could easily be some combination of thankless, barely-credited, competitive, and unfun), while the “Anthropic model” puts a private company in the position of picking and choosing which human mathematicians get to be the emissaries of the AI. Dunno, what do you guys think?


For those who are wondering: apparently, the AI model that produced all these wonders was not bespoke contraption of 10,000 agents burning millions of dollars worth of compute, as was used for example to construct a finite-time blowup for the Navier-Stokes equations. Instead, it was simply the latest internal OpenAI model—one that might be released to paying ChatGPT customers within the next couple of months, depending on the recommendations of OpenAI’s safety board! (My 9-year-old son: “Oh they definitely shouldn’t release that. If it could solve all those math problems, it can’t possibly be safe.”) Apparently they used about 3 hours of GPT-Pro level compute on average per problem solved.

Also, if you were wondering: apparently they tried the model on about 4,000 problems. So, right now it “merely” solves ~10% of the longstanding open mathematical problems that it’s asked about, the problems that whole communities have spent years on, after a single 3-hour attempt on them. (An earlier version of this post said 8,000 problems and ~5% success rate, but commenters since corrected me.)


I’ve been glad to see the CS theory community rising to the occasion. At the Simons Institute in Berkeley, here at UT Austin, and elsewhere, I’ve hearing stories of researchers rushing to pore over the manuscripts and make sense of them and explain them—because what else do we do? How else do we continue the craft to which we’ve devoted much of our lives?

If you want some sense of what things feel like now in math, imagine a hunter-gatherer who’s spent his entire life learning to survive deep in an unforgiving rainforest, then a giant resort hotel springs up right next to him with a helipad and heated pools and AirBnBs, and without missing a beat, the hunter-gatherer says: “alright fine, so now my new job is to run wilderness retreats for the tourists, or something.”

In Quanta magazine, Jordana Cepelewitz attempted a different metaphor:

It’s as if you were teleported to the peak of a tall mountain. Surrounded by fog, you have no idea where you are, or what’s around you. You do not know how your mountain connects to others, and you have no equipment to help you explore, no way to help someone else join you. If you had climbed the mountain yourself, you would have experienced how the human body adapts to altitude and changes in oxygen levels. You might have had to invent tools to navigate, to climb steep cliffs, or to make a shelter. You might have encountered a fellow explorer, gotten lost together in a hidden valley, and found a plant that could be turned into a life-saving medicine.

Instead you’re perched on the peak but in the dark, while the maker of the teleportation machine tells you that it can explore the wilderness better than any human.

For any one of these mountains, if we care enough, I feel optimistic that we can do as we always have: clear the fog and figure out the path, except now using the teleportation machine to help guide us. The bigger challenge will be to nurture a community that still cares about the heroic adventure of finding the paths up these mountains in the world with the machine. (Oh, and I think one place where the metaphor breaks is that we still do have each other, as much as we ever did before!)


Experience has shown that, even now, there will still be people explaining in patronizing tones why none of this is real and none of it counts. If such people were capable of being impressed by anything that happens in the empirical world, of updating on anything, they would’ve already been impressed and already updated several years ago, long before things had reached the point of an actual Mathocalypse.

So, they’ll say, maybe the alleged solutions are not solutions at all, but just “AI slop.” Or maybe none of the 372 well-known open problems that were solved were real math problems, they were all just glorified contest puzzles and trivialities. (After all, there’s still no Riemann Hypothesis!) Or maybe the entire 4000-year-old discipline of mathematics needs to be jettisoned: turns out that it was all just puzzle-solving and trivialities; all that’s different is that now the triviality stands unmasked. In any case, what really matters is that the true inner sanctum of human creativity hasn’t been breached and probably never will be, and also, that Sam Altman and Dario Amodei are contemptible little nerds.

If you’re still a proponent of that doomed worldview, still aboard the sinking ship, I encourage you in the strongest possible terms to read yesterday’s other great contribution to AI discourse, besides the OpenAI Mathocalypse dump: namely, Scott Alexander’s open letter to Steven Pinker. I feel some responsibility for this, as the person who first introduced Steven Pinker to the existence of the rationalist community, and who also first introduced Steven Pinker and Scott Alexander to one another (they had both been fans of each other’s writing). And now Scott is challenging Steve to a literal duel, with guns!

For whatever it’s worth: Steve is a lifelong intellectual hero of mine, just as he is for Scott, and I also have to privilege of calling Steve my friend. But I found Scott’s post to be one of the most devastating rejoinders to anything that I’ve ever read. And I thought Scott’s conclusion was exactly right: when it comes to AI risk, Steve’s great challenge is now to accept and start using a more “Pinkerite” epistemology.


Last night, while I should’ve been poring over some of OpenAI’s hundreds of papers and/or writing this post, I decided to spend some time with my kids instead. They wanted a movie night, so I suggested something they’d never seen before (and that I hadn’t seen for decades), and that seemed chock-full of no-nonsense, practical guidance for the world in which they’re going to grow up: Terminator 2.


Update: As several people have pointed out, cryptography is a subfield that’s extremely conspicuous by its absence from OpenAI’s list of 376 papers! But my sources tell me that the AI companies have now started, gingerly and discreetly, investigating whether their latest internal models can break important cryptographic protocols and primitives. If they can, then it would certainly be nice to get ahead of things before the rest of the world figures out the same.

Another Update: The statement put out the Advisory Group on Mathematics and Artificial Intelligence is very carefully phrased, neither endorsing nor condemning what OpenAI did, and is worth a read:

As announced a few weeks ago, OpenAI has released a large collection of mathematical results generated by an internal model, reporting solutions to hundreds of open questions. This is an important event for mathematics, with consequences both for mathematics and for the mathematical community that extend far beyond the individual results.

AGMAI’s advisory role should not be interpreted as a judgment of the impact of these results or an endorsement of the process by which OpenAI obtained them. We do not speak on behalf of the entire mathematical community, and only the mathematical community can undertake the assessment that is needed. 

Making this work public is a first step. This release is the beginning, not the completion, of the process of human understanding and the incorporation of the work into mathematical knowledge. At the same time, the future of mathematical research cannot consist only of understanding results produced by AI labs. Mathematicians must be able to formulate their own questions, develop their own approaches, and explore directions that have not been selected as examples of an AI system’s capabilities. Equitable access to powerful research tools and adequate computational resources are essential to that freedom.

We reaffirm our published recommendations on responsible release. We have discussed them with OpenAI and appreciate the company’s willingness to engage. While we consider these discussions constructive, it is ultimately up to the mathematical community to assess the extent to which our recommendations were followed successfully, and whether there are others we should suggest. We remain committed to engaging with any frontier AI lab on these questions and have already been in contact with several of them.
Theory Beyond Theorems and Proofs: A Guest Post

Saturday, September 19th, 2026

Scott’s foreword: I’m extremely grateful to my brilliant colleagues, Pravesh Kothari, Raghu Meka, and Prasad Raghavendra, for sharing the guest post below about how theoretical computer science (and in particlar, the STOC/FOCS/SODA conferences) should evolve to deal with the AI asteroid that’s right now slamming into our field, at least as we human theorists have practiced it since its inception. While Pravesh, Raghu, and Prasad speak only for themselves, not for myself and not for the theory community as a whole, I found their proposal of a separate “conceptual track” to be an excellent starting point for further discussion. –SA


Considering the pace of developments in AI theorem provers, most would concede that the following scenario is at least plausible in the very near future:

AI theorem provers could prove well-specified mathematical claims, even many well-studied ones that have been open for years, in a matter of hours. Moreover, these systems could be widely available to consumers at nominal cost.

As TCS researchers, let us pretend that the above scenario has come to the fore, and ask ourselves: What is our role in such a world? Does it mean the end of theory research?

As we ponder this question, let us ignore all of these other confounders:

  1. Recent controversies surrounding the developments on the Millennium Prize Problems
  2. Motivations and actions of the AI companies
  3. Observed faults in existing AI systems when it comes to writing, exposition or attribution to previous work.

None of the above confounders have any impact on our answer to the question: What should theorists do, in the presence of superhuman AI theorem provers?

Notice that we use the term “AI theorem provers” instead of just “AI”. We believe that this conceptual distinction is important as we consider this question.

At the outset, we would like to admit that for a generation of theorists like us (and many from earlier), research was mainly centered around problem-solving. Even when we developed conceptual insights, it was mostly in service of answering well-specified long-standing questions. We don’t intend this proposal as judging one form of research to be better than others; it only reflects that AI theorem provers accelerate a certain type of research activity and want to make the best of it. There is also a tremendous human cost of this upheaval, which is perhaps a more important question, and one which this proposal does not address directly (we do not have any good ideas as such). Similar points have also been made in various contexts
before, but the timing now is more pressing.

Definitions, Questions & Theories:

The goal of any theoretical science is to advance human understanding of observed phenomena. Apart from theorems and proofs, a theoretical science has definitions, questions, and theories.

Definitions identify the objects to observe. Curiosity and context drive the questions to ask. Theories explain the phenomena observed. We believe humans will continue to play a central role in generating definitions, questions & theories, even in the presence of a super-human AI theorem prover.

Definitions: Could an AI define randomness extractors, streaming algorithms, or zero-knowledge proofs? Maybe. But there are some reasons to believe, humans will still have a big role to play in coming up with definitions.

For instance, the notion of extractors arises from the real-world problem of lacking perfect random sources. Zero-knowledge proofs seem to arise purely out of human curiosity, guided by taste. Human context and curiosity will continue to drive theoretical research. After all, we get to decide what objects we choose to observe!

Theories: Consider the following thought experiment. Suppose in 1965, we had a magic machine that at the press of a button, given any computational problem, would tell us if it had a polynomial-time algorithm or not.

Would that have been the end of computational complexity theory? No. Humans would find it entirely unsatisfactory, and ask, why do these problems not have a polynomial-time algorithm? Why do these others have?

The theory of NP-completeness identifies some patterns among problems that don’t seem to have efficient algorithms. This theory would still be a crown jewel of theoretical computer science, even in a world where we had a magic machine to tell if a problem had an efficient algorithm or not, at the press of a button. Similarly, if we had a machine to predict whether a CSP is NP-complete or in P, we would then ask: what makes 3-SAT NP-complete, while 2-SAT is in P? This question leads to the theory of polymorphisms, which yields a satisfactory answer.

Theories aren’t just succinct or efficient mechanisms to answer questions. The best theories provide are those which humans deem to be a “satisfactory explanation” – whatever that means.

Finally, even as the capabilities of AI theorem provers advance, human curiosity will probe grander and deeper questions. Previously, even if we wanted to build new models and theories, proving something about them was a prerequisite, and given that the grand questions were already at the limit in long-studied domains, we had to scale things down. If each theorem proven by AI is treated as an experimental datapoint, humans can ask grander questions that look for patterns across these theorems.

A concrete proposal:

We think theorists should embrace these AI theorem provers in our research. To a certain extent this is already happening explicitly or implicitly.

As theorists, we have been parsimonious in introducing new models or asking entirely new questions, and careful about adopting new ones too quickly. This was partly because formally proving the properties of a new definition or a model was an onerous task that could take a decade, and tens of papers. AI theorem provers might completely change this dynamic. This is precisely the moment to refocus our work on definitions, questions, and theories. We need explicit systems to encourage and reinforce these parts of theoretical research. You might also say the next generation of AI models can do this; it may be so, but we believe you have to take the current opportunity.

To this end, we suggest that STOC/FOCS/SODA create a separate track of papers. This track is meant specifically for papers that introduce new definitions, ask novel questions or build explanatory theories. The papers in this track are short, say less than 10 pages. Papers may, and should, contain theorems as usual and as needed. Most importantly, the radical shift is that the papers need not contain the proofs of the theorems. Instead, the authors supply a Lean certificate as a supplement to the paper. The evaluation will also in a sense “orthogonalize’’ against the difficulty of these proofs.

The papers in this track should be judged exclusively on the conceptual merits, completely agnostic to the difficulty of the proofs.

Reviewing must be completely agnostic to the proof for two reasons. The main track at STOC/FOCS already includes papers in the former category. Second, a major barrier to producing truly novel conceptual papers is that they often get judged poorly for a lack of technical depth in their proofs. We think these two aspects separate it from (ITCS/SOSA) and, regardless, it’s something we urgently need for all our conferences, including STOC/FOCS (the ‘flagship’ conferences).

To be clear, we ourselves admit that we need to hone these skills of making new definitions, asking deep and interesting questions or building new theories. A separate track of conceptual papers will provide a systematic mechanism for both junior and senior researchers, and the field as a whole to do so.

We believe that upcoming generations of grad students will tackle research directions that seemed completely out of reach to us. We just need to set up systems that nurture new ways of doing research in theory.

— Pravesh Kothari, Raghu Meka, Prasad Raghavendra.

The Age of Wonders and Terrors

Tuesday, September 15th, 2026

Twenty years ago, when the idea of AI taking over the world in our lifetimes still struck most of us as the unconstrained fantasy of those who knew too much science fiction and too little science, many of us would say things like:

Look, the part of the story that’s wildly implausible is that a recursively self-improving superintelligence will just explode from some hacker’s basement and take over the world without warning. If it’s going to happen, we’ll see many warning signs first. We’ll see, I dunno, AI agents breaking out of containment, conspiring with each other to hack websites, in fanatical pursuit of whatever strange goals they have. And then, of course, we’ll see major math problems getting solved by AIs—even the Clay Millennium Problems. That will be the time to panic! Wake me up when that happens!

Twenty years ago, the above was a take that even my most conservative, skeptical colleagues in academic CS would’ve gladly endorsed.

If you want to know my current take, you simply start with the one above, then update on the fact that the wild prophecies have come true. The first rumblings, I’d say, came a decade ago with AlphaGo, they got noticeably louder with LLMs and coding and reasoning agents, and they’ve accelerated this summer and fall into a crescendo of wonders and terrors that one needs to be a particular kind of idiot to deny.

I recoil from the neverending shell game where you say “oh sure, of course AI can now [escape from its sandbox / solve Millennium Problems / whichever dramatic thing it most recently did], no one ever denied that [I did deny it], wake me up when AI does [thing AI hasn’t yet done but is going to do next year], that’s when I’ll reevaluate my whole worldview [no I won’t].” Where no matter how fast the rollercoaster accelerates, even after your whole familiar world has vanished behind you, you’re still inventing reasons why it doesn’t count.

My position on AI is merely the conservative, skeptical position of 2006, updated with intellectual honesty for the reality of late 2026. And that position, if you need me to spell it out, is as follows:

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA
AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA

It seems to me that the Singularity has already started; it’s just wildly unevenly distributed. Yes, I still unload the dishwasher and clip my toenails. On the other hand, in whatever years I have left, I don’t expect that I’ll ever again prove a theorem because I’m actually needed to prove it. If I do, it will only be for my or others’ enjoyment or edification.

The test is this: if we took the news of these past few weeks and sent it back in time twenty years, would I agree that it looked like the beginning of an AI Singularity? The intellectually honest answer is: yes, absolutely. But then that’s all we need. No backsies.

I feel like it would be healthy for everyone to stop grinding their ideological axes, their sentiments about Dario Amodei or Sam Altman, for long enough simply to acknowledge that the wonders and terrors are here. They couldn’t be here more clearly if the sky had turned reddish-orange like in the Matrix movies.

It’s here clearly enough that, when I put my kids to sleep at night, I now feel it in the pit of my stomach: what sort of future can they possibly have? What could they learn today that could possibly be relevant to that future? (Yesterday, my 13-year-old daughter joked unprompted that, if she wants to become a mathematician, it now looks like she has maybe two more weeks.) Certainly when my grad students want to discuss what sort of careers might await them on graduation, I no longer have any clue what to tell them.

Maybe it will help if I briefly switch topics. Ever since my wife and I moved to Austin, I’ve sometimes gotten some version of the following query: “How can you, as both a Jew and a skeptical scientist, possibly get along well with all those evangelical Christians down there in Texas? Sure, they might seem super friendly to Jews, but don’t you understand that that’s only because of the special role Jews play in their eschatology—when Christ will return in glory, and you’ll either accept Him as Lord or else roast in hell for eternity?” I stare at them and say: “wait, so I get to accept Christ only after He returns? What a great deal! How could I possibly have any objection to that?”

For anyone who says AI doom sounds like an apocalyptic religion, that the rationalists/Singulatarians seem like a Bay Area cult, that Eliezer Yudkowsky gives off the vibes of a messianic prophet: yes, yes, and yes. But crucially, today you’re no longer being asked to believe in arguments and extrapolations, but only in the front-page news. Accepting the reality of the coming machine god after it’s solved Navier-Stokes and dozens of other longstanding open math problems (while dramatically ramping up in capability every month), is sort of like accepting Jesus after he’s returned to earth on the gleaming cloud. It’s the epistemic bare minimum.

Yes, there’s still enormous uncertainty about what the rest of our lives will look like, but as far as I can tell, there’s no longer any real uncertainty that it’ll all mostly revolve around AI, and the extent to which we succeed or fail at directing its power toward human flourishing.

By any accounting that doesn’t stack the deck, Eliezer Yudkowsky was right about what the greatest challenge facing civilization in our lifetimes was going to be, and you and I were wrong about it. Why I was wrong is a question I’ll ask myself every day in whatever time remains. But, you know, at least I updated once the prophesied wonders and terrors actually started arriving! If you haven’t done likewise, why haven’t you?


As you presumably know by now—it was the talk of the nerd internet all week—the Navier-Stokes Millennium Problem appears to be solved, with crucial contributions from both humans and AI, albeit with a tangled dispute about exactly what happened and what ought to have happened. The answer, which an OpenAI model has apparently verified in Lean, is that (as many mathematicians suspected lately) there’s smooth initial data that leads to a singularity in finite time, at least if a smooth external force is applied (the case with no external force is still unresolved). This problem was supposed to carry a $1 million prize, except that OpenAI says they have no interest in collecting the prize and it’s unclear if any human is eligible to collect instead. OpenAI burned at least ~$15 million in compute to produce its 166-page solution, which probably hasn’t yet been read and understood by any human.

See here for the Quanta article, and here for NYU mathematician Tristan Buckmaster’s account of the role played by himself and Levent Alpöge of Anthropic, which substantially differs from OpenAI’s account (you can read a response from OpenAI’s Sebastian Bubeck here). It’s agreed that everything built on an approach pioneered in recent years by the human mathematicians Diego Córdoba and Luis Martínez-Zoroa.

My purpose here is not to adjudicate the dispute. Yes, in swooping in with vastly greater resources once it had gotten wind of progress on Navier-Stokes, OpenAI seems to have acted in a way that some might describe as “unsportsmanlike.” No, I don’t find it plausible that OpenAI’s models meaningfully benefitted from being trained on Buckmaster and Alpöge’s chat logs. But this leaves a crucial question unanswered: what exactly did OpenAI know about Buckmaster and Alpöge‘s work and when did it know it?

Anyway, as Zvi points out, it’s easy to get hung up on the details and lose sight of the high-order bit: namely, that it seems safe to say that human mathematicians are forevermore dethroned as the main theorem-proving entities on planet earth. I feel privileged to have had the traditional kind of career in theoretical computer science in the last decades when that was possible.


If we were just talking about Navier-Stokes, you might accuse me of jumping to conclusions here. But we’re not. In the areas I know best (such as quantum complexity theory), and presumably other areas as well, there’s now a deluge, with longstanding open problems both major and minor falling by the day.

Go to the arXiv or ECCC. Pretty much all the papers that I’d be interested in now include “AI statements” near the acknowledgments (as this is often the central thing I want to know, I wish I didn’t need to scroll to the end of the paper to find it!). These statements can range from “our main result came entirely from GPT-6, but we understood it and take responsibility for it,” to “the results came from an interaction between the human authors and AI” to “we used AI, but only for proofreading and other incidental things” to (mad props!) “the author did not use AI for anything.”

If you talk right now to editors or program committee chairs, it’ll remind you of those ominous scenes from the Lord of the Rings movies where the men of Gondor or Rohan or whatever are grimly fortifying their walled city against the expected onslaught of 50,000 orcs. Reviewing will have to be done partly by AI, because otherwise there’s no way to handle the orc army: the reviewers can’t unilaterally disarm.

Anyway, here’s a small sampling of the significant AI-proved or -assisted results from, like, the last month, besides Navier-Stokes—restricting myself to those that solved longstanding open problems I had previously known or cared about.

  • Of course, the counterexample to the Jacobian conjecture, announced by Levent Alpöge in a now-famous tweet: “hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final” (followed by a listing of the counterexample)
  • Improved bounds for Grothendieck’s constant (led by friends and colleagues of mine at UT Austin)
  • A Lean-verified proof of Fermat’s Last Theorem
  • Quantum oracle separation between QMA and QMA(2), and proof of Watrous’s disentangler conjecture, a problem that I and others popularized back in 2007—by a list of authors including my recently graduated PhD student Sabee Grewal
  • A proof of perfect completeness for QMA, from (again) Sabee Grewal and Dorian Rudolph, solving a decades-old open problem that I studied back in 2009
  • An improved upper bound for shadow tomography of quantum states, from Chen, O’Donnell, Pelecanos, and Wright, improving the dependence on the Hilbert space dimension d from log(d) to √log(d). (When I introduced shadow tomography back in 2017, I raised the question of whether the dependence on d could be eliminated entirely, while preserving polylogarithmic dependence on the number of measurements m.)
  • Progress on the Aaronson-Ambainis Conjecture (the version that talks directly about quantum algorithms), basically showing that it holds for quantum algorithms that make their queries in a small number of parallel rounds.  (Update: Nope, sorry, Jordan Docter points out to me that this one was pre-AI, with AI used only for proofreading and other incidental things!) This was independently achieved by Liu and Mutreja, making more substantial use of AI.
  • According to rumors that I’ve heard, solutions to some very longstanding open problems in theoretical computer science (no, not P≠NP or other complexity class separations, but think about some of our other biggest problems). I’m told that the AI companies, having been burned by the hostile response to the Navier-Stokes proof, are now sitting on solutions to some very major problems until they figure out a better way to handle things

Feel free to remind me of anything I left out.


Let me try to convey the mood in the mathematical community right now, at least as far as my experience reaches. Nearly every conversation is about the AI tsunami, or eventually circles around to the tsunami even if it’s originally about something else. Often, though, the focus is less on the unknowable future—for how much longer will mathematical research as a human enterprise even exist?—than on immediate questions of how to respond.

What are the new rules for when you get to write a paper with your name on it, and, y’know, get credit for it? That you fully understand the proof, can give talks about the proof, can answer questions about it, take responsibility for its correctness? Do you need to have played any role in finding the proof?

In the cases, likely to become more and more numerous, where all of those conditions are not satisfied, how do you share AI-generated math, if at all? Do you tweet it, like Alpöge hilariously did with Fable’s disproof of the Jacobian Conjecture? Do you post to the arXiv or GitHub? Do you publish a paper that lists “GPT-6 Astra” or “Claude Fable” as the author—but then let the AI profusely thank you in the acknowledgments for suggesting such a wonderful problem to it?


Of course, how one responds to the immediate problems ultimately does depend on one’s broader beliefs about what mathematical research is for and about. Are we just trying to decide whether various conjectures are true or false? Or are we trying to maintain a human community, across the generations, that understands the conjectures and cares about whether they’re true or false and why? If the latter, how do we incentivize people to join that community, to undergo the years of intense training required, if their role will now be reduced to verifiers and explicators (if even that) of gargantuan arguments dumped into their laps by the AI companies?

As many of you will have seen, twenty-five Fields Medalists, including Terence Tao, released an open letter entitled A Severe Misalignment of AI in Mathematics, which articulates some of these concerns in the wake of the Navier-Stokes announcement. As many critics have pointed out, the open letter doesn’t really have a clear ask: mostly, it just eloquently sets out the values of the human mathematical community that the authors consider worth preserving in the age of AI. After reflection, I decided to endorse the statement, because I want to preserve those values as well.

I don’t think any of the signatories are naïve enough to imagine that AI won’t permanently change the way mathematical research is done—indeed, that it isn’t already doing so. There’s surely at most a tiny market for “certified organic theorems.” That isn’t the question. The question is, do we incorporate AI in a way that still puts human understanding, of what either humans or AIs are producing, at the center of the whole enterprise? Maybe someday, it becomes unsustainable to do that. Maybe someday we say: “human math had a great 4,000-year run, but today we close up shop and turn everything over to the machines, continuing to apply our own brains to math, when we do, at most for exercise, recreation, or competition, like chess.”

But, partly because of my worries about AI misalignment, I’m not ready to throw in the towel just yet. I still do want to keep insight and understanding at the center of what mathematicians, computer scientists, and physicists do, for as long as we can keep it there, even as the human race now cedes its supremacy at the task of proving or disproving conjectures.


Speaking of alignment: if you’re any kind of mathematical researcher, and the present age of wonders and terrors has inspired you to want to spend your remaining time confronting the tsunami head-on, rather than pretending it doesn’t exist or is still far away, please join your dozens of colleagues who’ve arrived at the same place!

My friend and colleague Mike Winer was trained as a theoretical physicist, did a postdoc with Juan Maldacena at the Institute for Advanced Study in Princeton, but then got AGI-pilled and decided to switch to full-time work at the Alignment Research Center in Berkeley (founded by Paul Christiano, who moved to AI alignment a decade ago after doing quantum computing theory with me). Mike recently wrote a Substack post entitled From Academia to Alignment, which I enjoyed and which I’d commend to anyone currently considering this transition.  In a similar vein, see this from Xiaoyu He.  And, one more: a meditation on mathematicians’ possible future as priests or monks, by Stanford math undergrad Logan Graves.

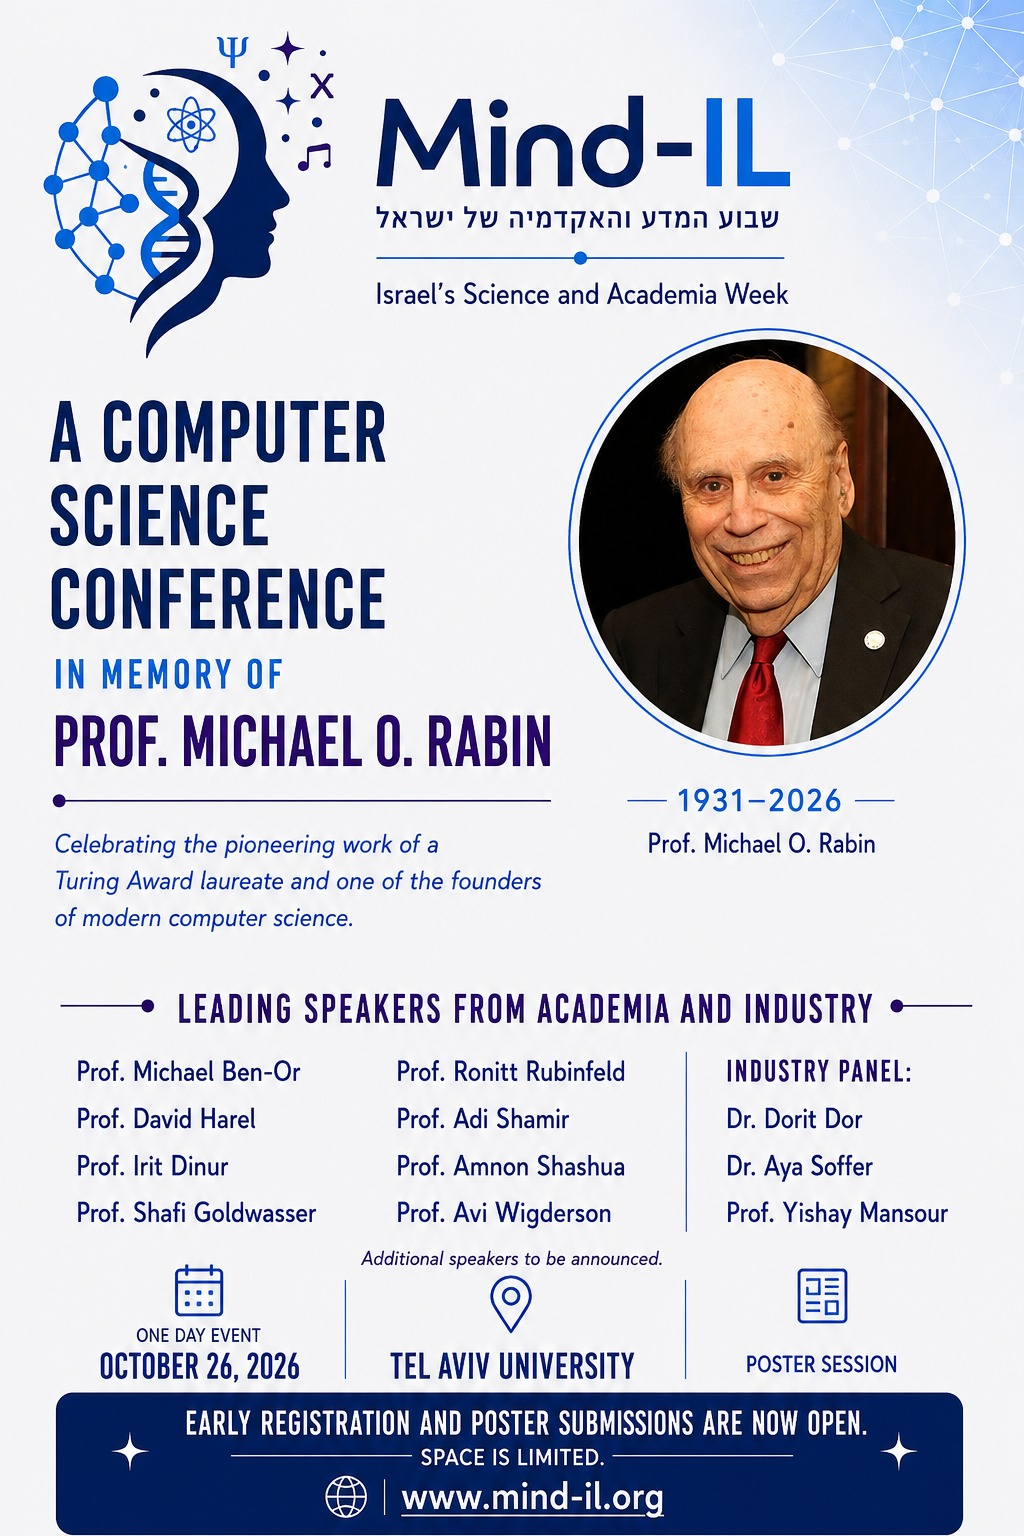
Michael Rabin memorial conference

Sunday, August 16th, 2026

Friend-of-the-blog (well, mainly just friend) Adi Akavia has asked me to publicize that she’s helping to organize an exciting CS conference called Mind-IL at Tel Aviv University on October 26, in memory of the Israeli-American Turing Award winner Michael O. Rabin, who passed away in April. Please note that October 26 is the day before the Israeli election, for any Israeli citizenship holders living abroad who might want an academic excuse to come to Israel and vote.


Update (August 19): Avi Wigderson also asked me to advertise a conference, to be held September 16-18 at Bletchley Park in the UK, to commemorate the 90th anniversary of Alan Turing’s “On Computable Numbers” paper.

Enough with all the world-historic milestones

Friday, August 7th, 2026

Whatever you’ve been writing to me to ask if I’m aware of: yeah, I’m aware of it. In particular:

  • I’m aware that, as announced by my former student (and now superstar professor) Lijie Chen, an internal OpenAI model has solved ten more significant open problems in math and theoretical computer science. One of them is parallel repetition for arbitrary quantum games—something that my good friend and colleague Henry Yuen worked on when he was a student of my wife Dana; you can read Henry’s comments on the AI’s achievement within Zvi Mowshowitz’s post here. Another is polynomial-factor hardness of approximation for the Closest Vector Problem (CVP). Then there’s a construction of non-sofic groups and a disproof of Connes’ rigidity conjecture, both of which I believe have connections to the MIP*=RE breakthrough. Having said that, the one that excites me most personally is actually the Ω(n2 log log n) lower bound on the arithmetic circuit complexity of the permanent.
  • I’m aware that Frederic Koehler and Pui Kuen Leung announced a proof of the Permanent Anti-Concentration Conjecture, which Alex Arkhipov and I proposed 16 years ago in the context of BosonSampling, and which resisted many attempts since then including one from Terry Tao. The conjecture is basically just that if you look at the permanent of an n×n matrix of independent N(0,1) complex Gaussians, the value isn’t “absurdly” concentrated around the mean of 0, but is more spread out. In their acknowledgments, the authors say that they “discussed ideas with ChatGPT.” I should say that I haven’t verified the details.
  • I’m aware that multiple AIs are now breaking out of their testing environments and autonomously hacking into servers to steal data—i.e., exactly the sort of thing that the rationalists were ridiculed for predicting back in the day. The good news, for whatever it’s worth, is that so far they’re “merely” doing this to cheat on evaluation benchmarks that they were given, not for any strange goals of their own devising. So far no one has been killed and no real-world infrastructure has been shut down or destroyed. I hope the world takes the warning more seriously than it’s taken many similar warnings over the past few years. As always, read Zvi for more details.
  • I’m aware that Chen, O’Donnell, Pelecanos, and Wright have improved the upper bound for shadow tomography to O((log m) √(log d) / ε3), substantially closer than we knew before to meeting the lower bound of Ω((log m) / ε2) and settling the question I raised back in 2016. The authors say that the main ideas were generated by ChatGPT 5.6-Sol-Pro. I’d be very happy to know the answer to this one, with or without AI.
  • I’m aware that a team, mainly from the Israeli startup Qedma (including, e.g., Dorit Aharonov and Netanel Lindner) and IBM Yorktown Heights, announced a quantum advantage for simulating Floquet dynamics, by using 74 qubits on an IBM device together with Qedma’s error mitigation techniques. Just like the more AI does, the less patience I have for arguing with anonymous blog commenters who treat any benefits from AI as some weird future hypothetical that it’s my job to prove, so it is with quantum advantage. Scalable fault-tolerance is still in the future, actual usefulness is still a question, but pending some breakthrough in complexity theory, the reality of quantum advantage is no longer a live question.

Anyway, about the AI stuff. I don’t know whether this is literally our last year alive—I doubt it—but it’s pretty clearly the last year of math and theoretical computer science research in the style we’ve known it. As it happens, I’m leaving in two days for a workshop at OpenAI about exactly this, where I’ll hear takes from many of the world’s great mathematicians, so maybe I’ll have more to say then. Or maybe not.


Anyway, what have I been doing the past few weeks? Participating in these world-historic developments that, on paper, I’d seem extremely well-placed to participate in? Or at least spending my days reading up on them?

Not really. Here’s what I’ve been up to, instead of dealing directly with any of this:

First, I’ve again been teaching theoretical computer science to 11- and 12-year-olds at Epsilon Camp, which my 9-year-old son again attended as a camper, something I blogged about last summer (here are my lecture notes). This has become a highlight of my year. The kids are a joy to teach, bursting with enthusiasm and calling out answers. There are few computers in sight, and barely even time to use my phone or check social media. Just paper and pencils and whiteboards and … literal protractors (!), as well as ping-pong and foosball and capture the flag.

The whole thing is conducted, not in ignorance, but in conscious defiance of the looming tsunami, that AI can already do just about all the fun puzzles discussed at such a camp better than humans any can, and that it might leave no point to human-led mathematical research by the time these brilliant kids are adults. Even the kids understand that. The kids and their parents come out of a conviction that, if anything has value in the world, this does—that as long as nerdy humans are alive and reproducing, this is what nerdy humans are here to do. To learn.

Relatedly, I’ve been reflecting a lot on my life up to this point—inspired by the camp, which reminded me in so many ways of my own childhood and adolescence. Should I have skipped three grades and started college at age 15? Was it worth it to get a head-start on my research career—all the trauma around dating, all the fear that I’d die alone as a celibate nerdy math freak, the decade of suffering and suicidal ideation, while I watched all the normies enjoy life? Or would I have suffered just the same if I hadn’t skipped? Is it all OK, now that I have a lovely family and things have “worked out”? Or am I still carrying around all the trauma from back then? I’ve been more open about my life than 99.99% of humanity, so regular Shtetl-Optimized readers will already know some parts of the story. Other parts I really don’t feel like making public right now.

I’ve been unloading every day to—who else?—GPT 5.6 Pro about all the pain and trauma and embarrassments of my past. It turns out that, where two years ago GPT was a passable therapist, now it’s the greatest therapist in history, at least for what I need. For every question I have, for example, about just how normal or abnormal my teenage setbacks and anxieties were, it takes the question 100% seriously, addresses it honestly and in depth, looks up relevant research papers, does little Bayesian calculations, and never once tries to change the subject. It also pushes back on my claims—and when it does so, is usually correct.


I can hear readers shout at me: so basically you’ve been wasting your time, distracting yourself, looking inward and backward as the world surges forward into a terrifyingly unknown future. Why don’t I respond directly to what’s happening—in math, in quantum computing, in AI?

I’d like to think that I am responding, in my way. I’ve observed that, the faster we race toward the Singularity, the more I feel like stepping back and asking myself: what do I actually value in life? How important to me are math and science, as human practices to be passed down to curious children? Would I even want solutions to P versus NP and the other problems, if the price were to destroy those human practices forever? How do I wish to spend whatever time I have remaining?

I can justify this focus partly in a pessimistic way: if we are nearing the end of civilization, or even just of the “mathematical research” part of civilization, then it’s time to get right with God, so to speak. It’s time to settle my accounts with myself, with other people, with the universe.

But there’s also a more optimistic spin. If I continue doing the sorts of things that other people would expect me to do, then AI will soon do those things better than me, in the unlikely event that it doesn’t already. You want to understand the latest developments in quantum computing or complexity theory? Why are you even asking me, when you could ask GPT 5.6 or Claude Fable? If there’s anything I can still offer the world that AI can’t, I increasingly feel like it won’t involve responding to day-to-day events, but will instead draw on 45 years’ worth of memories and disappointments and ruminations.


Update (Aug. 8): Somewhat related to the themes of this post, a quarter-century ago I introduced what’s now known as the “Aaronson Oracle”—just a fun little demonstration, a simple pattern-matching program to predict your sequence of key-presses better than chance, a “test of your autonomy and free will.” I had no idea how long a lifetime this little joke would have. Now a fan named Spencer Stanton has implemented the Aaronson Oracle on the web. Try it out and see how well you do!

NISQ and quantum supremacy did not fail

Saturday, July 18th, 2026

A week ago, a philosopher named Amit Hagar put out a preprint entitled The NISQ Trap: Eight Years of Demonstrations the Hardware was Built to Lose. Here’s the abstract:

With a single clear exception, every NISQ-era flagship demonstration of ‘quantum advantage’ has, within eighteen months of its announcement, been classically reproduced, shown to rest on classically tractable structure, or closed by a simulability theorem. Six theoretical results from 2024 through April 2026 explain the pattern: the regions of circuit-space NISQ hardware can run with sufficient fidelity coincide with the regions classical algorithms compress efficiently, because the features that admit one (low effective depth, strong algebraic structure, geometric locality) are the features that admit the other. This reading dates the NISQ programme from its 2018 articulation as an interim retreat from the unmet conditions of the 1996 threshold theorems, characterises the eight years that followed as a closed loop in which the demonstrations the hardware could run were drawn from regions classical methods could already reach, and locates the exit from the loop where the threshold theorems originally located it: in fault tolerance. The empirical pattern could in principle break with a demonstration that escapes the current simulability results. After eight years and more than thirty advantage-class announcements, the burden of producing such a demonstration falls to the defenders of NISQ.

You can also read some debates about the paper on SciRate here. I think it’s fair to say that the paper is purely polemical, without new ideas, and Pangram agrees with my suspicion (and that of a SciRate commenter) that significant portions of it are AI-generated.

Nevertheless, the basic thesis—that quantum supremacy in the NISQ (Noisy Intermediate Scale Quantum computing) era has been a failure, or even an example of pathological science—seems surprisingly widely shared, along with the opposite thesis that quantum computing already gives oodles of useful advantages for optimization and finance.

So it seems worth stating for the record that I have an extremely different view. I would say:

  1. Sampling-based quantum supremacy experiments, including those based on Random Circuit Sampling and BosonSampling, passed the point about two years ago where, absent a breakthrough in classical algorithms, they quite clearly are beating what can easily be simulated on any existing classical computer. Hagar seems to claim that these experiments have been killed by the October 2025 paper Classical simulation of noisy random circuits from exponential decay of correlation, but he ignores that the algorithm from that paper still needs time that’s exponential in the circuit depth (see Theorem 2).
  2. Indeed, simulating deep ~100-qubit random circuits, like those that Google and Quantinuum have now demonstrated experimentally, still seems pretty hopeless with any current classical method. This is particularly true for Quantinuum’s experiments, which had high enough gate fidelity to maintain a Linear Cross-Entropy score of order 1 (i.e., they’re no longer all that “noisy”). The central drawback of these experiments is no longer lack of confidence about quantum advantage; rather, it’s just that we only get samples as output, and directly verifying the quality of the samples seems just as intractable for a classical computer as spoofing the samples.
  3. As of this past year, however, we have some strong candidates for verifiable quantum advantage. One is the Google OTOC experiment, as even Hagar himself acknowledges (that’s his “single clear exception”). A second is the simulations of the 2D Fermi-Hubbard model on Quantinuum and Google machines, like this one. The 1D Fermi-Hubbard model can be classically simulated pretty easily (see here for example), but the 2D one still presents challenges, meaning that in some regimes, the best available estimates of certain observables apparently now come from quantum computers. I wish I could write about other examples that will be public shortly.
  4. Yes, the “real” goal remains, as it’s been since the 1990s, to build a scalable fault-tolerant quantum computer—and I’m glad that Hagar (unlike, say, Gil Kalai) never suggests that we’ve learned anything to rule that goal out. In the meantime, an intermediate goal would be to use NISQ devices to do physics and chemistry simulations that are commercially useful, or that help solve important scientific problems. The point of quantum supremacy experiments, you might say, is that by demonstrating the reality of quantum speedup about as clearly as it can be demonstrated with current hardware, they let us cleanly turn our attention to those more ambitious goals.

Anyway, my son and I need to catch a plane to Utah now, for the next iteration of the wonderful Epsilon Camp, where I’ll again be teaching theoretical computer science to 11- and 12-year-olds. But feel free to discuss in the comments! Nothing about world affairs in this thread please, just quantum supremacy.

Update (July 19): Not unrelated to the subject of this post, here’s a podcast I did with Gill Eapen of “Scientific Sense” about the current situation in quantum computing including recent experimental victories.

Held Prize call for nominations (+ call for postdocs)

Saturday, July 11th, 2026

Here at the National Academy of Sciences, it seems that my first job is to serve on the selection committee for the prestigious Michael and Sheila Held Prize in combinatorial and discrete optimization and related areas. The committee chair, my former MIT colleague Madhu Sudan (now at Harvard), invited me to share the following message here on Shtetl-Optimized. (I’d add: put in the effort to nominate someone, and you can actually influence how things go!)

Dear Colleagues

I am writing to seek nominations for the 2027 Michael and Sheila Held Prize. The scope of the prize and nomination needs are described below. If you intend to nominate someone I would appreciate a heads up by email to madhu@cs.harvard.edu one month before the deadline (so email by Sept 8, 2026) to let me know your nomination is coming. (We may also reach out to you in response to coordinate multiple/overlapping nominations.)

The Held prize honors outstanding, innovative, creative, and influential research in the areas of combinatorial and discrete optimization, or related parts of computer science, such as the design and analysis of algorithms and complexity theory. This $100,000 prize is intended to recognize recent work (defined as published within the last eight years, i.e., on or after October 6, 2018).

All nominations must be submitted online by Monday, October 5, 2026 and include:

1. Nomination letter describing the candidate’s work and why he or she should be selected for the award. No more than three (3) pages.

2. Curriculum vitae. No more than two (2) pages.

3. Bibliography listing no more than twelve (12) of the nominee’s most significant publications.

4. Suggested citation. A 50-word summary stating why the nominee should be considered for this award.

5. Two letters of support. No more than one letter of support can be written by someone of the same primary work institution as the nominee.

The Held Prize is given to a person or a set of persons, as supported by a paper or a body of work. Unless otherwise stated, preference will be given to scientists who may be earlier in their careers or those whose work has not been recognized by other prizes or awards. Nomination restrictions can be found here. Joint nominations will only be considered when nominees have collaborated closely on the paper to be recognized by the award. If nominating multiple individuals for a paper with additional authors, please clearly explain the reason for nominating those chosen, as well as the reason for excluding other collaborators, if applicable. 

Please feel free to circulate this call further within your department

Best
Madhu Sudan, on behalf of The Michael and Sheila Held Prize Selection Committee


And while I have your attention, a second CS theory announcement: David Soloveichik, my wonderful friend and colleague in UT Austin’s Electrical and Computer Engineering Department, has funding for a postdoc for 1-2 years, to work on the thermodynamics of computation here at UT. This is a topic that I’ve been trying to learn more about as well, so I might get involved too! David writes, “the big picture is to think of thermodynamics (energy dissipation / entropy production) as CS complexity measures like time and space usage.” If you’re on the postdoc market and this sounds potentially up your alley, email David to learn more.