Archive for the ‘Complexity’ Category

Spreading the Gospel of Theoretical Computer Science to an Omega(1) Fraction of Humanity: My Trevisan Award Acceptance Speech at STOC

Sunday, June 28th, 2026
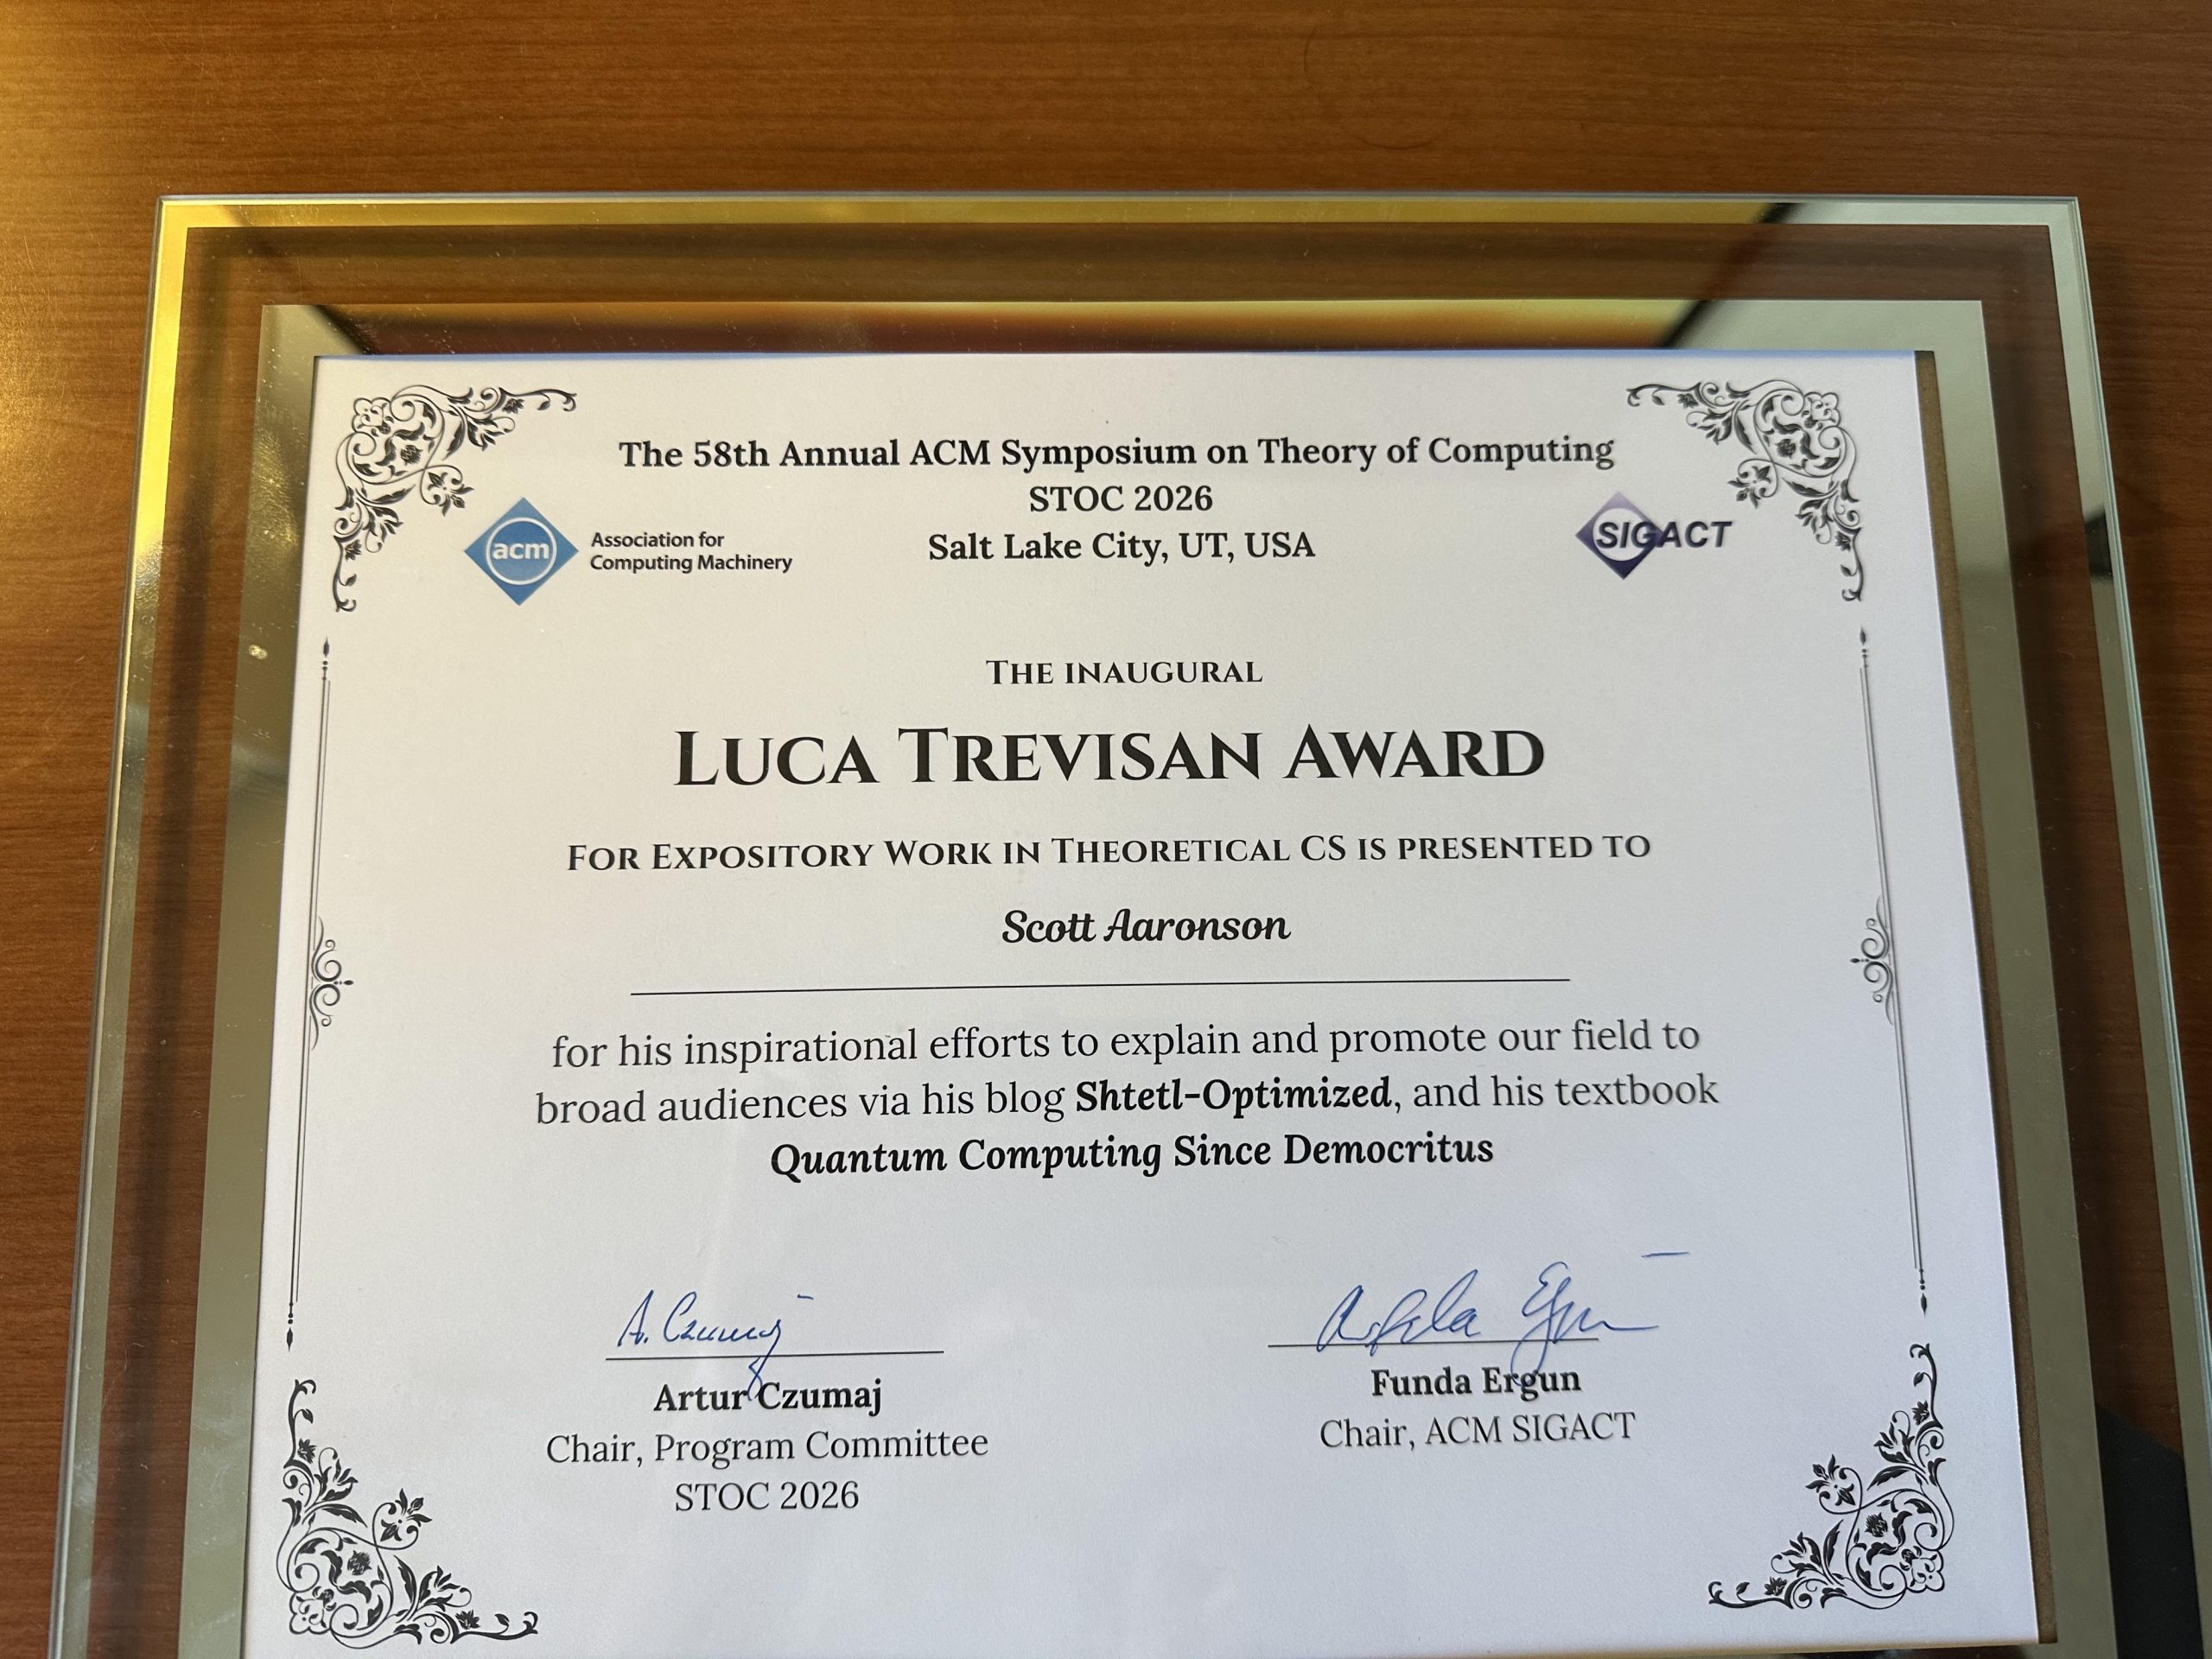
Take that, Shtetl-Optimized haters of the world!
With longtime friend and colleague Salil Vadhan, as well as Luca Trevisan’s widower Junce Zhang, at the STOC banquet on Tuesday, before I was given half an hour to try to make people laugh

Spreading the Gospel of Theoretical Computer Science to an Ω(1) Fraction of Humanity (Or, How We Can Do Like the Physicists)
Scott Aaronson’s Trevisan Award Acceptance Speech
Salt Lake City, Utah, June 23, 2026

Thank you so much! It’s one of the highlights of my life, frankly, to accept the first-ever Luca Trevisan Award for Expository Work in Theoretical Computer Science—because of, firstly, what this entire STOC community means to me, but also what Luca Trevisan in particular meant to me. Luca was one of the main people who taught me complexity theory—first at an IAS summer school in 2000, then at UC Berkeley, where I took two of his courses and TA’ed for him. As a member of my dissertation committee, Luca once stood on a street corner in San Francisco to meet my friend to sign the signature page of my thesis, as I struggled to get the thing in by the deadline. Later, Luca’s theoretical computer science blog, In Theory, bounced off of my blog.

I wish Luca were here now. But knowing him as well as I did for a quarter century, I feel like I know what he’d say if he learned that I had received the inaugural prize that bears his name. I imagine he’d slap his forehead and say “Seriously, there was no other option??” But I’d like to think that he’d eventually reconcile himself to the choice!

By the way, I noticed that in the committee’s prize announcement, which I found so moving, they added a special paragraph at the end that basically said, “please don’t imagine that to win this prize in the future, you need to behave the way Aaronson behaves. You can just write beautiful textbooks or survey articles or whatnot, and be normal and sane.”


The foundation of my career is that I realized 25 years ago that there were better theoretical computer scientists than me—like many in this room, or like Ryan Williams or Andris Ambainis, both of whom I knew at the time. Certainly there were better quantum physicists than me. There were better writers, better expositors, better performers. On the other hand, if you looked specifically at the intersection of computational complexity and quantum physics and standup comedy, that was just this totally uncontested territory!

I’ll let you in on a secret: pretty much everything I’ve done for decades has just been drawing out one joke. That joke is, basically, “computer scientists they be like this, but physicists they be like that.” The physicists they be like [exaggerated doofus voice] “duhhhh, NP, what’s that stand for? Not Polynomial?” See, but then there’s also a Rodney Dangerfield aspect to it, because it’s like, how come we never get as much respect as the physicists get? (Though when we do get that respect, I confess that I complain all the more, because then I lose my shtick…)

It’s true that the physicists have certain built-in advantages. They had Einstein, Stephen Hawking, the atom bomb—and just the fact that they’re ultimately talking about, or trying to talk about, the world that we can see and touch. A black hole is an actual place that you could visit, even though I wouldn’t recommend it. But physicists also have much better names for things than we do. I mean, black hole? Big Bang? Quark? Gluon? Supersymmetry? Dark matter?

Meanwhile, what names have we got? TFNP. NC1. And worst of all, PP. These are names that you want to flush down the toilet. But also, the concept of a zero-knowledge protocol, or a two-source extractor, just inherently take longer to explain to people than the concept of a particle, or even a field—even though the latter also turn out to be extremely abstract and mathematical when you push on them. Ask a physicist what a particle is, they’ll tell you that it’s an irreducible representation of the Poincaré group. See, but people think they know what a particle is, it’s just a tiny little hard sphere that moves around, and that’s good enough for them.


So then, how can we win the grand popularity contest against the physicists? How can we, as I put it in my title, spread the gospel of CS theory to a constant fraction of the human race? In my view, the first step is to reframe who we are and what we’re about. We’re not this obscure little community off to the side, proving its little theorems about derandomization and catalytic space. No! What we are is the conceptual and mathematical core of computer science, the field that’s changing the face of civilization in obvious and undeniable ways.

This was even true a long time ago. The physicists had Galileo and Einstein? Well, we had Turing, a figure so heroic and so tragic that no one would’ve believed him as a fictional character. And while we’re at it, we’ll claim Gödel and Shannon and von Neumann, Leibniz and Babbage and Ada Lovelace—they’re all ours too.

That’s our proud history. But then when we turn to today, it’s like, holy crap! Even the densest ignoramus can now see how deep intellectual ideas originating in CS are changing the world.


Blockchains—some people might wish they’d never been invented, but they were invented, so we all need to think about how they change the world’s economy for better and worse. And of course, they’re fundamentally based on hardness assumptions; they couldn’t exist in a world where NP was easy.

Part of my outreach job these days is to explain to finance people, over and over, why a quantum computer could break the elliptic curve signature schemes used by Bitcoin and many other coins, but would have only a more modest effect on the proof-of-work part, the hash function. And it’s like, if you actually want to know, then we need to talk about BQP versus NP, Grover’s algorithm and its optimality, black-box problems with and without abelian group structure—and now we’re deep into TCS!

Speaking of quantum computing—even if we set aside the question of whether quantum computing is going to revolutionize materials science or chemistry or pharmaceuticals design—or whether it will revolutionize AI and machine learning and optimization [I shake my head, make a thumbs-down, and blow a raspberry]—even if we set aside those practical questions, quantum computing plausibly represents the most dramatic test of quantum mechanics itself that we’re ever going to see. And it now looks clear that we will see that test within the next decade or sooner. One way or the other, we’re going to learn the truth.

People sometimes ask me, why did it take until the 1980s for anyone to propose the idea of quantum computing? You know, Heisenberg and Schrödinger were in the 1920s, Turing was in the 1930s, so it seems like all the ingredients were in place a half-century earlier! In my Quantum Computing Since Democritus book, I reflected on this, and I think the deepest answer is that not quite all of the intellectual ingredients were in place. Quantum computing is something that it doesn’t make a great deal of sense even to ask about until you’ve established polynomial versus exponential, and even P and NP and NP-hard, as central concepts. And that’s what didn’t happen until the 1970s.


But of course, the biggest thing that our CS concepts have unleashed on humanity—the thing that the entire world now realizes holds even greater promise and greater peril than nuclear energy did in the last century—is [pause for effect] the Razborov-Smolensky lower bound method.

No, I’m kidding of course. It’s generative AI.

Twenty years ago, I remember people in our community—was it Fortnow? Impagliazzo? I’m not sure—saying, “you know the real reason why P vs. NP is such an important problem? Suppose P=NP, via an algorithm that was fast in practice. Then it’s not just that you could break all the encryption systems, or have your computer find a proof of the Riemann Hypothesis, or whatever. No, it’s that you could program your computer to find the shortest efficient compression of, for example, the full text of Wikipedia. For in order to create that compression, it seems plausible that your computer would need to create an AGI as a byproduct.”

I remember thinking to myself: “that’s an amusing thought experiment, I’ll need to steal it sometime, but still, what an utterly simplistic vision of the nature of intelligence! There has to be more to intelligence than sheer data compression!”

Fast forward to spring 2022, when I accepted an invitation to go on leave for a couple of years, to join what was then a relatively obscure little nonprofit foundation by the name of … err … OpenAI. When I flew to San Francisco to start my assignment, I had lunch with Ilya Sutskever, the cofounder of OpenAI and then its chief scientist. And Ilya said to me, “Scott, let me explain to you how we think about things here at OpenAI. For us, intelligence is fundamentally about prediction, and prediction is fundamentally about compressing your training data. As you know, Kolmogorov complexity is uncomputable, but one can get better and better computable upper bounds on it. We conjectured that, in order to get sufficiently good at predicting and compressing all the text on the Internet, you’d need to build a model of the entire world that had led to that text being written. And we made a gamble that large neural nets would do that well enough, despite the problem’s worst-case intractability.”

That conversation was when it hit me that, if only we in CS theory had taken our own concepts and thought experiments more seriously, one of us could’ve started OpenAI 15 or 20 years ago. So OK, we didn’t, and that’s why I flew coach to get here. But this is the kind of story that it seems to me we could be singing from the rooftops.

(Incidentally, the reason why OpenAI wanted me back in 2022, was to use theoretical computer science to figure out how to make AI safe for humanity. Alas, that problem is still open! But I’m thrilled that there are so many sessions about exactly this question at STOC this year, and I hope many of you will choose to get involved.)


In the rest of this talk, I’d like to offer some advice—such as I have—for any of you who’d like to try your hand at speaking or writing or blogging or podcasting about theoretical computer science for a broad audience. You see how my hair is starting to gray? Yeah, that’s what authorizes me to go into advice mode.

Let’s start with the obvious: meeting the audience where they are. This is something that I learned years ago from Steven Rudich, who along with Luca, was another irreplaceable figure who our community recently lost, and lost too soon. I remember 26 years ago, at that same IAS summer school where I learned from Luca, Rudich gave the students a talk about how to give talks. In it, he showed a cartoon of someone lecturing. And there were little thought bubbles that said:

What the speaker thinks the audience is thinking: MORE! HARDER! FASTER! Ah yes, QED, truth is beauty and beauty is truth!

What the audience is actually thinking: What the hell are they talking about? When is this over? Can I get a date with the person sitting next to me?

You know, this misconception that because something has become obvious to you, after thinking about it for years, therefore it should be equally obvious to your readers or listeners encountering it for the first time? This is what Steven Pinker dubbed “the Curse of Knowledge,” and calls the most fundamental problem of all exposition. (I could mention the related misconception that because something has become interesting to you, therefore it’s interesting to your audience. But you can make just about anything that’s interesting to you interesting to your audience, by telling a suitable story about it.)

What can you do about the Curse of Knowledge? Practice giving a buttload of talks to undergrads, high school clubs, even physicists, and listen to the feedback you get. If the same weird confusion shows up at least twice, it’s a safe bet that it’s going to keep showing up—which means, now you can anticipate and preempt it the next time you explain the same concept.

But it’s not just misconceptions that you should listen for. Listen for which of your metaphors and anecdotes actually land. Certainly listen for which of your jokes get a laugh. Use those more the next time. And if saying, for example, “hur hur, I’m in a quantum superposition of two different topics that I could talk about next”—if that fails to get a laugh, then DROP IT.

Eventually, you’ll build up what Carl Sagan once called “consumer-tested stepping stones”: that is, a library of jokes, anecdotes, and metaphors that can get you from wherever you see the audience is to wherever you need them to be. Here’s an intentionally tiny example of one of my stepping stones: “Why is P contained in NP? Because the verifier just says to the prover, dude, take a hike, you’re not needed here.” Or another stepping stone, for when we reach the question of the likelihood of P=NP: “look, if we were physicists, we would’ve declared P≠NP to be a law of nature. We would’ve given ourselves Nobel Prizes for the discovery of that law. And if it later turned out that P=NP? We’d just give ourselves more Nobel Prizes for the law’s overthrow!”


This brings me to a broader point. CS theory is unusually rich with facts that are true for silly or absurd or ironic reasons. Lean into that! Don’t hide it!

I mean, “if NP has small circuits then this theorem is true, but if NP doesn’t have small circuits, the theorem is again true, but now for a totally different reason”? That’s sidesplittingly hilarious! OK, maybe only to some of us.

Or why does IP=PSPACE? An alien lands and is like, “I COME TO EARTH TO TELL YOU THAT WHITE HAS THE WIN IN YOUR GAME CALLED CHESS.” And we’re like, “why should we believe that?” So the alien is like, “LET US PLAY A GAME. I’LL PLAY WHITE AND WILL WIN.” And we’re like, “oh, we assume you’re smarter than us! You came all the way here in a spaceship and all! But that still doesn’t prove it.” So the alien is like, “THEN LET US PLAY A DIFFERENT GAME, MATHEMATICALLY EQUIVALENT TO CHESS, INVOLVING SUMS OF POLYNOMIALS OVER A FINITE FIELD. IN THIS TRANSFORMED GAME, THE BEST YOU CAN DO IS TO MOVE RANDOMLY. SO IF I STILL WIN, YOU’RE STATISTICALLY CERTAIN I WOULD’VE WON REGARDLESS OF HOW YOU PLAYED.” It’s like, dude. Dude!

Of course, our founding irony, our founding absurdity, was self-reference and diagonalization. Like, “you can’t predict what any human brain will do 5 seconds from now, because if you could, you could predict what you yourself were going to do 5 seconds from now, and then do the opposite of that!” BOOM! Therefore the halting problem is undecidable and the Time Hierarchy Theorem is true, QED. But beyond that: “black-box program obfuscation is impossible, because one thing you can always do, if given the actual code of a program, is to run the program on its own code and see what happens.” Dude! Or: the reason why it’s so hard to prove P≠NP, is that it’s presumably true that P≠NP. That’s a wisecrack that, in the context of the Natural Proofs barrier, becomes so much more than a wisecrack.

One special case of leaning into absurdity concerns the central role in our field played by asymptotics. I’m always slightly at a loss when someone asks me, “so, how many times faster would a quantum computer be than a classical computer? A million times faster? A billion?”

Part of me wants to reply: “I must educate you about polynomial versus exponential scaling until you see the profound error of your question, and retract it.” But another part of me simply wants to say: “depending on the problem, a quantum computer could be anywhere from not faster at all to, let’s say, 1010000 times faster.”

The truth is, I think we need to do both. Anytime you’re talking about asymptotics to laypeople, if you can plug in some representative numbers, it will help them understand what you’re talking about. And then, if the asymptotics are what really control the real-world numbers, so much the better! If, on the other hand, the asymptotics are comically disconnected from the real-world numbers—if, for example, you’re trying to improve something from log*(n) to Ackermann-1(n) or whatever—well then, you can lean into that as an additional source of humor.


Alright, one last piece of advice. Tell true stories about how you came to understand or discover whatever it is that you’re talking about. Don’t be like the mathematicians who love to cover their tracks.

When people ask me how I proved the lower bound on the number of steps needed for a quantum computer to find collisions in a list—a centerpiece of my PhD thesis, and one of the two or three hardest technical things I’ve done in my career—I say, look, I was 20 years old and I had no social life. So I just pulled many all-nighters trying every possible approach. Eventually, I came across some complicated expression that had no right to be a polynomial. But somehow, every term in the denominator cancelled against a corresponding term in the numerator, and it was a polynomial! And that let me use the polynomial method to prove a lower bound. Why was it a polynomial? I still don’t really understand, a quarter-century later! My point is, people want the truth.

The secret of blogging is that, even if people despise what you’re saying, even if they think it’s wrong, offensive, problematic, cringe, you name it, they need to trust that you’re telling them the truth of what you know or believe or remember about the subject at hand, the same as you’d tell your closest friend.


In summary: we, the CS theory community, are sitting on top of one of the greatest conceptual and intellectual goldmines of our whole civilization. I exhort everyone here: please help tell the world about it! As you do so, think about how to honor Luca’s memory and make him proud. But also think about how to make me, and my silly little blog, superfluous and obsolete.

Thank you for this honor, thank you for the incredible privilege of being part of the CS theory community, and thank you for listening.

50 Years of Aumann’s Agreement Theorem

Sunday, June 28th, 2026

One of the most popular posts in this blog’s history was Common Knowledge and Aumann’s Agreement Theorem, based on a lecture that I gave to high-school students 11 years ago. One of the impacts of that post, I’m proud to say, is that (according to Steven Pinker) it helped to inspire Steve’s excellent recent popular book, which you should read, entitled What Everyone Knows That Everyone Knows…: Common Knowledge and the Mysteries of Money, Power, and Everyday Life.

Two weeks ago, I was privileged to attend a workshop in Paris on “50 Years of Agreeing to Disagree,” where (among other things) I got to meet the 96-year-old Economics Nobel Laureate Robert Aumann for the first time.

Me and my friend Aran Nayebi (CS professor at CMU) with Robert Aumann

I got to catch up there with Steven Pinker as well, who gave a phenomenal talk on the psychology of common knowledge. My own talk was entitled The Complexity of Agreement, with New Directions and Applications (link goes to my PowerPoint slides).

Aran Nayebi has graciously posted on YouTube some partial video from the meeting, including his talk, brief snippets from my talk, and Aumann’s own remarks:

Meanwhile, here were the Aumannian insights that I remembered to write down:

AUDIENCE QUESTION: What questions did people ask you after you published your famous agreement theorem in 1976?

AUMANN: I don’t remember what happened yesterday, let alone 1976.

Also:

ME: I thought you might enjoy knowing that I just came here from a meeting of rationalists…

AUMANN: A meeting of who?

ME: Rationalists, they call themselves, at a beautiful venue called Lighthaven in Berkeley, and that they named the main building there “Aumann Hall” in your honor.

AUMANN: OK, so I’ve made it then.

One recent result announced at the workshop, for those who care, is that the proof of Aumann’s Theorem has now been formalized in Lean, by Scott Kominers at Harvard and a group from the startup company Axiom Math.

Thanks so much to Christina Katt-Pawlowitsch, Ziv Hellman, and others for organizing the workshop and for including me in it.

Happy to field questions in the comments, although if someone wants to call me an idiot like usual, we’ll just need to agree to disagree!

Bipartite matching is in NC!

Monday, June 22nd, 2026

Since I’m a good mood today—at a beautiful science camp with my kids, high in the mountains near Big Bear Lake in California—I thought I’d blog about something positive. Last week, five authors (Chatterjee, Ghosh, Gurjar, Raj, and Thierauf) posted a major paper to the Electronic Colloquium on Computational Complexity, which shows (or anyway, credibly claims to show) that the Bipartite Matching problem is in the complexity class NC. Assuming this stands, it resolves a central problem in parallel algorithms and derandomization that’s been open since the 1980s.

In Bipartite Matching, you’re given a list of n men and n women, you’re told who’s willing to date whom, and your goal is to

  1. decide whether it’s possible to pair everyone off with a willing partner, and
  2. if they are, actually pair them off.

One of the great early discoveries of combinatorial algorithms, taught in every introductory algorithms course, is that this problem is solvable in time polynomial in n, even though the naïve, brute-force approach would require examining n! possibilities.

(Note that in the bipartite version, we assume that the men and women are all straight. If the men and women can be LGBT, we get the problem of matching in general graphs, which again turns out to be solvable in polynomial time, but now the algorithm is much more sophisticated, and was a major discovery of Edmonds in the 1960s.)

Anyway, the question is whether we can do even better than polynomial time: in particular, can we solve the problem in time polynomial in log(n), given polynomially many parallel processors?

Back in the 1980s, first Karp, Upfal, and Wigderson, and then (via a very different method) Mulmuley, my former PhD adviser Umesh Vazirani, and Umesh’s brother Vijay Vazirani managed to show that the answer is yes, but only if the parallel processors additionally get access to random bits, and only need to succeed with high probability.

The new achievement is to derandomize the Mulmuley-Vazirani-Vazirani algorithm, and show that problems 1 and 2 above are both solvable in deterministic polylogarithmic time with parallel processing (in other words, in the complexity class NC).

No, I don’t understand how it works yet. If anyone does, feel free to explain in the comments! Or ask your favorite AI to generate a summary. If I run out of options, at some point I might actually try reading the paper.

(Note: Thanks to Gil Kalai for some corrections to an earlier version of this post.)


One other announcement: Today is the day of primary elections in NYC! Virtually all of my smartest friends who work on AI governance and safety are extremely excited about the Congressional campaign of Alex Bores—indeed, it would be little exaggeration to say that they consider him the last best hope of humankind. Bores has been a national leader on trying to regulate AI, to the extent that Marc Andreessen’s “Leading the Future” anti-AI-regulation PAC has spent millions of dollars trying to sink his candidacy. Outside of AI, Bores seems like a sane, conventional Democrat, i.e. the kind I like, and much more moderate than his base on Israel (note that his main opponent is also such). Without commenting on Bores’ views on every possible issue, I’ll simply say: if you live in New York’s 12th Congressional District (comprising a huge chunk of central Manhattan), and you care about AI safety, please consider a vote for Bores while there’s still time.

The Trevisan Award and the Decimal Digits of Powers of 2

Sunday, May 10th, 2026

WHOA … I’ve won the inaugural Luca Trevisan Award for Expository Work in Theoretical Computer Science! This has a particular meaning for me as someone who knew Luca Trevisan as well as I did for 25 years — who had him as a professor and thesis committee member, whose blog bounced off his blog, who benefitted tremendously from his expository work in TCS — before Luca tragically succumbed to cancer two years ago.

As I told the committee, receiving this award makes me want to use my blog for more actual CS theory exposition, and less venting, in order to retrospectively become worthier of such an honor.

I’m ridiculously grateful to the entire TCS community — my people, my homies — for tolerating me to do what I do.

If you’re curious, here’s the official citation:

The inaugural Luca Trevisan Award for Expository Work in Theoretical Computer Science is awarded to Scott Aaronson for his sustained and high-impact inspirational efforts to explain and promote our field to broad audiences. His blog Shtetl-Optimized has hosted remarkably frequent and elaborate posts over more than two decades, and has become a central meeting place for wide-ranging conversations across the TCS and Physics communities. Scott Aaronson’s blog posts contain crystal-clear, informative expositions of exciting new results, calibrated evaluations of technological claims, and profound analyses of topics in these fields and (way) beyond. The uniquely enthusiastic and witty style of his writings (including his book Quantum Computing Since Democritus and his other lecture notes and surveys), lectures, and interviews have made him a top invitee for both popular and professional appearances, attracting large audiences. These qualities have inspired many students to enter the field, and made Scott Aaronson a go-to person for journalists and scientists alike looking for a definitive word on the latest scientific activity in TCS and quantum computing.


In the rest of this post, I’m going to start practicing what I preached—y’know, about turning over more of this blog to actual exposition, of a kind that the Trevisan Award could plausibly be meant to encourage. I’ll start with something that’s been on my back burner for the past couple months: namely, the (lightly edited) transcript of a talk that I gave this spring at UT Austin’s undergraduate math club. So, without further ado, and in memory of Luca…


On the Decimal Digits of Powers of 2
by Scott Aaronson

Hi! I’ve given six previous talks here at UT’s math club, some on relatively “important” topics—Gödel’s Theorem, time travel, Huang’s proof of the Sensitivity Conjecture, and so on.

Today, I want to talk about an unimportant question, one that my son Daniel, who was then 8, and who’s sitting here in the front row (along with his sister Lily), asked me a few months ago.

Daniel asked: which powers of 2 can you double without needing to carry digits? Clearly 1, 2, 4, 32, and 1024 all have this property, their doubles being 2, 4, 8, 64, and 2048 respectively. Are there any others?

Since I happen to have the powers of 2 up to 220 = 1,048,576 committed to memory since childhood, I confirmed that there were no other examples up to there: 128, 256, 512, 2048, etc. all require carries. So I told Daniel: I can’t find any other example, and on that basis, I conjecture that there aren’t any more. But if that conjecture is true, I don’t know if it will ever be proven, by humans or even AI!

Then I googled it, and saw that this is a known question (not very well known, but there’s a StackExchange post about it). And indeed it had been checked up to 2millions, and no other counterexample had been found.


Why did I become confident so quickly that yes, 1024 is probably the last example of a power of 2 that can be doubled without carrying?

Because of the heuristic that the decimal digits of 2n are more or less “random,” apart from various constraints that are irrelevant here (like that the last digit always cycles among 2, 4, 6, and 8). And 2n has about n/log210 decimal digits. Since only 0, 1, 2, 3, 4 can be doubled without carrying, the probability of 2n being a counterexample should therefore be about $$ (\frac{1}{2} )^{n / \log_2 10}. $$

So, if we’ve already checked up to (say) n=1000, then the probability of a larger counterexample should be at most

$$ \sum_{n=1001}^{\infty} (\frac{1}{2} )^{n / \log_2 10} $$

which, when we sum the geometric series, is exceedingly close to 0.


Ah, but why did I say that I don’t know if the conjecture will ever be proven? Because it seems to belong a large class of similar statements, none of which mathematicians have had any idea how to prove.

Variant of a conjecture by Jeffrey Shallit: 65,536 is the only power of 2 that has no power of 2 among its decimal digits.

Freeman Dyson’s conjecture (2005): There’s no power of 2 for which, when you reverse the decimal digits, you get a power of 5.

Paul Erdös’s conjecture (1979): For every n≥9, there’s at least one ‘2’ in the base-3 representation of 2n.

Or looking even more broadly:

Conjecture: The decimal expansion of π is not all 6’s and 7’s after some finite point.

(This would follow from the stronger conjecture that π is base-10 normal—that is, that every finite pattern of decimal digits occurs in it with the limiting frequency you’d expect.)

Or:

Conjecture: π+e is an irrational number.

What all the above conjectures have in common, and what I find so fascinating about them, is that they seem hopeless to prove for exactly the same reason why they seem almost certainly true. Namely, they all seem to be true “merely” because it would be too insane of a coincidence were they false!

The trouble is, that’s not the sort of reason that seems amenable to turning into a proof. Fermat’s Last Theorem is an interesting exception that proves the rule here. That xn+yn=zn has no nontrivial integer solution for n≥3, did seem almost certainly true on statistical grounds for n≥4 (and for the n=3 case, a proof goes back to Euler). And of course, FLT was ultimately provable. But Wiles’s eventual proof exploited a lucky connection between the Fermat equation and deep, fancy things like modular forms and elliptic curves. At no point did the proof formalize the statistical argument that a 12-year-old could understand, for why the theorem is “almost certainly true.” It simply had nothing to do with the statistical argument.

So then, if you wanted to prove conjectures like my son Daniel’s, or like Shallit’s or Dyson’s or Erdös’s above, the question would be: could these “recreational” problems about base-10 representations ever be connected to anything similarly deep? Right now, it’s very hard to see how they could.

Still, all hope is not lost! Here’s a striking theorem that I learned about when I researched this:

Theorem (James Maynard, 2016): For every digit a from 0 to 9, there are infinitely many primes with no a’s in their base-10 representation.

The proof uses heavy Fourier-analytic techniques. Likewise, presumably there are infinitely many primes that you can double without carrying—2, 3, 11, 13, 23, 31, …—because the primes are much denser than the powers of 2! And presumably there are infinitely many primes that are missing any two decimal digits, or even whose decimal digits consist entirely of 0’s and 1’s. But Maynard’s techniques are not yet powerful enough to prove such things.


Even though I promised a topic of no importance today, I can’t resist pointing out a potential connection here to one of the biggest questions on earth right now, and something that’s professionally interested me for the past four years: namely, the question of how to align powerful AIs with human values and prevent them from destroying the world.

Paul Christiano, and the Alignment Research Center in Berkeley that he founded, have developed a whole program for how to make AI safe that depends on the possibility of formalizing “heuristic arguments”—that is, the kinds of arguments that convince us that the above conjectures are all almost certainly true, even without proofs of them.

The intuition here is that we’ll never have a rigorous proof that, for example, a real-world neural network will behave safely under all circumstances—it’s just too complicated. The best we can hope for is an argument that, e.g., “for this model to scheme against humans would require a crazy unexplained coincidence in its weights.” But how can we hope to formalize such arguments? As baby test cases, can we at least formalize our intuitions for why π is normal, or why Daniel’s conjecture is true, in some principled way?

ARC has tried: there’s a 2022 paper by Christiano, Neyman, and Xu on “Formalizing the presumption of independence.” But it’s tricky, and ARC itself would be the first to agree that the existing results are unsatisfying. How do we even formalize the intuition that, for example, you should be willing to bet at even odds against the 10100th digit of π being a 5?


In the rest of this talk, I’d like to circle back to Daniel’s original question about powers of 2, and show you some things that can be proved about it—with thanks to Greg Kuperberg and my other friends on Facebook, and in some cases to GPT5Pro.

Let’s start with the following easier question. Is there a power of 2 whose decimal digits start with 31415? Or with the complete works of Shakespeare, encoded by letter values in some suitable way? Or with a googolplex digits all of which can be doubled without carrying (as Daniel wanted)?

I claim that the answers are yes, yes, and yes! How do we prove this?

The key fact we’ll use is simply that log102 is an irrational number. (If you don’t remember the proof: suppose log102 = a/b. Then 10a/b = 2, so 10a=2b. But this has no integer solutions other than a=b=0.)

Suppose we want k as a prefix, where 10d-1 ≤ k ≤ 10d. Then we want integers n,r such that

$$ k 10^r \le 2^n \le (k+1) 10^r, $$

i.e. taking the base-10 log,

$$ \log_{10}k + r \le n \log_{10}2 \le \log_{10}(k+1) + r. $$

In other words, the fractional part of n log102 needs to lie between the fractional part of log10(k), and the fractional part of log10(k+1) (where again, k is given).

But now we can appeal to the following Key Fact: if α is any irrational number, then the set

{the fractional part of nα : n∈N}

is dense in the interval [0,1]. Or equivalently, if I rotate around and around the unit circle by 2απ radians each time, then if α is irrational, I’ll eventually get arbitrarily close to any given point on the unit circle.

Why is the key fact true? Just the pigeonhole principle! Clearly, for any ε>0, the fact that α is irrational means that there must be two points, xα and yα, whose fractional parts are distinct yet closer together than ε. But then, by adding multiples of (x-y)α, we can get our fractional part to be ε-close to anything in [0,1].

And to sum up, this is why there must be a power of 2 whose decimal representation starts with the complete works of Shakespeare, or with a googolplex carry-free digits! (Indeed, from the above discussion, we could even extract an efficient algorithm for constructing that power of 2.)


So much for the first decimal digits of 2n. Now let’s look at 2n‘s last decimal digits!

Here there are some complications, arising from the twin facts that

(a) 10 is composite, and
(b) 2 is one of its factors.

But we can deal with those complications!

For starters: what are the possible last decimal digits of 2n?

1, 2, 4, 8, 6, 2, 4, 8, 6, …

So, there’s an initial 1, but then we cycle forever through the even nonzero digits.

What about the last two digits of 2n? If you’ve never tried this before, it’s instructive to work it out:

01, 02, 04, 08, 16, 32, 64, 28, 56, 12, 24, 48, 96, 92, 84, 68, 36, 72, 44, 88, 76, 52, 04, …

So, there’s an initial 01 and 02, but after that, we cycle forever through 20=4×5 possibilities, namely all the possible multiples of 4 whose last digits are nonzero.

You can check that the general pattern is: the last k decimal digits of 2n have an initial segment that looks like 001, 002, 004, 008, …, 2k-1. And then there’s an eternal cycle of length 4×5k-1, where the last digit can be any of 2,4,6,8, while every other digit can either be any possible even digit or any possible odd digit, depending on the digits to its right—in (if you want to say this a fancier way) a recursively defined embedding of the powers of 2 mod 5k into the cyclic group Z/10k. So, there’s an initial “runup” as you fill out all the needed powers of 2, but then once that’s done, you just cycle around forever in an embedding of Z/5k into Z/10k, because

(a) 2 happens to be a primitive element of Z/5k for any k, and
(b) 5 divides 10.

So in particular, and relevant to Daniel’s conjecture: there exists a power of 2 whose last googolplex digits can all be doubled without carrying. Why? For the last digit, you can pick 2 or 4. Then, for the last googolplex digits but one, you can pick 1 or 3 for those constrained to be odd, and 0, 2, or 4 for those constrained to be even. Lots of choices that work!


So, we can avoid carries in the leftmost digits of 2n, we can avoid carries in the rightmost digits … so that “merely” leaves all the digits in the middle, where who the hell knows! Empirically, the digits seem to pass every standard randomness test that you can throw at them. So in particular, e.g., the fraction of the digits that are in {0,1,2,3,4} seems to converge inexorably towards 50%, so that it’s extremely plausible to conjecture that the fraction is less than 49% or more than 51% for only finitely many values of n. But of course, that’s presumably even harder to prove than Daniel’s original conjecture.


OK, last topic. Suppose we want to program a computer to check Daniel’s conjecture up to 2n, for some huge n. What algorithm will do that most efficiently? A naive algorithm would just calculate 1, 2, 4, …, 2n and check all the digits of all of them. That takes O(n2) time, since each 2k, for k=0,1,…,n, has ~klog102 = O(k) decimal digits.

We can improve this to roughly O(n) time, by simply noticing that we only need to check O(1) digits per power of 2 in expectation, presumably, until we find the first digit that requires carrying. Then we don’t even need to compute the remaining digits: we can simply move on to the next power of 2. (This sort of trick is used all over the place in the design of fast algorithms.)

But when I posted about Daniel’s problem on Facebook, my friend Greg Kuperberg (who’s a mathematician at UC Davis) noticed that further improvements are possible. To wit: 8×6 = 48, which again ends in 8. So, 8×16 ends in 8, as does 8×16k for every k≥0. Meaning: no 2n where n=3+4k can possibly be a counterexample to Daniel’s conjecture. They’re all ruled out!

Likewise, 64×1,048,576 ends in 64, so no 2n of the form n=6+20k can be a counterexample. They’re all ruled out as well.

We can keep going this way, filling out the “search tree” of potential counterexamples to Daniel’s conjecture via breadth-first search. At the root of the search tree, we try all possibilities for the last digit. One level deeper, we try all possibilities for the second-to-last digit, and so on. As we go, we prune subtrees according to constraints like the ones above that we keep discovering and adding.

When I worked this out, I got an algorithm for checking Daniel’s conjecture up to 2n, which under reasonable assumptions takes time only O(nα), where α = 1-log52 ≈ 0.569, and space only polylog(n).

Paul Crowley (who’s my Facebook friend) then actually implemented this algorithm, and he tells me that he used it to check that Daniel’s conjecture holds all the way up to $$2^{10^{21}}$$ (!!), using 40 minutes on a 128-core machine.

So, to return at last to the first thing I told Daniel: yes, I think his conjecture is almost certainly true, even though I have no idea when, if ever, the human race or its successors will have a proof.

Three greats who we’ve lost

Sunday, April 19th, 2026

Sir Charles Antony Richard Hoare (1934-2026) won the 1980 Turing Award for numerous contributions to computer science, including foundational work on concurrency and formal verification and the invention (with Dijkstra) of the dining philosophers problem. But he’s perhaps best known, to pretty much everyone who’s ever studied CS, as the inventor of the Quicksort algorithm. I’m sorry that I never got to meet him.

Michael O. Rabin (1931-2026), of Harvard University, was one of the founders of theoretical computer science and winner of the 1976 Turing Award. In 1959, he and Dana Scott introduced the concept of a “nondeterministic machine”—that is, a machine with exponentially many possible computation paths, which accepts if and only if there exists an accepting path—which would of course later play a central role in the formulation of P vs. NP problem. He’s also known for the Miller-Rabin primality test, which helped to establish randomness as a central concept in algorithms, and for many other things. He’s survived by his daughter Tal Rabin, also a distinguished theoretical computer scientist. I was privileged to meet the elder Rabin on several visits to Harvard, where he showed me great kindness.

Sir Anthony Leggett (1938-2026), of the University of Illinois Urbana-Champaign, was one of the great quantum physicists of the late 20th century, and recipient of the 2003 Nobel Prize for his work on superfluidity. When I knew him, he was a sort of elder statesman of quantum computing and information, who helped remind the rest of us of why we got into the field in the first place—not to solve Element Distinctness moderately faster, but to learn the truth of quantum mechanics itself. Tony insisted, over and over, that the validity of quantum mechanics on the scale of everyday life is an open empirical problem, to be settled by better experiments and not by a-priori principles. I first met Tony at a Gordon Research Conference in southern California. Even though I was then a nobody and he a recent Nobel laureate, he took the time to listen to my ideas about Sure/Shor separators, and to suggest (correctly) what we now call 2D cluster states as an excellent candidate for what I wanted. In all my later interactions with Tony, at both the University of Waterloo (where he was visiting faculty for a while) and at UIUC (where my wife Dana and I considered taking jobs), he was basically the friendliest, funniest guy you could possibly meet at his level of achievement and renown. I was bummed to hear about his passing.

My theoretical computer science notes from Epsilon Camp

Sunday, March 29th, 2026

Last summer, I was privileged to teach a two-week course on theoretical computer science to exceptional 11- and 12-year-olds at Epsilon Camp, held at Washington University in St. Louis. The course was basically a shorter version of the 6.045 course that I used to teach to undergrads at MIT.

I was at Epsilon Camp to accompany my son Daniel, who attended a different course there, for the 7- and 8-year-olds. So they got me to teach while I was there.

Teaching at Epsilon was some of the hardest work I’ve done in years: I taught two classes, held office hours, and interacted with or supervised students for 6-7 hours per day (compared to ~4 hours per week as a professor), on top of being Daniel’s sole caregiver, on top of email and all my other normal responsibilities. But it was also perhaps the most extraordinary teaching I’ve ever done: during “lecture,” the kids were throwing paper planes, talking over and interrupting me every ten seconds, and sometimes getting in physical fights with each other. In my ~20 years as a professor, this was the first time that I ever needed to worry about classroom discipline (!). It gave me newfound respect for what elementary school teachers handle every day.

But then, when I did have the kids’ attention, they would often ask questions or make observations that I would’ve been thrilled to hear from undergrads at UT Austin or MIT. Some of these kids, I felt certain, can grow up if they want to be world-leading mathematicians and physicists and computer scientists, Terry Taos and Ed Wittens of their generation. Or at least, that’ll be true if AI isn’t soon going to outperform the top human scientists at their own game, a prospect that of course casts a giant shadow not only over Epsilon Camp but over our entire enterprise. But enough about the future. For now I can say: it was a privilege of a lifetime to teach these kids, to be the one who first introduced them to theoretical computer science.

Or at least, the one who first systematically introduced them. As I soon realized, there was no topic I could mention—not the halting problem or the Busy Beaver function, not NP-completeness or Diffie-Hellman encryption—that some of these 11-year-olds hadn’t previously seen, and that they didn’t want to interrupt me to share everything they already knew about. Rather than fighting that tendency, I smiled and let them do this. While their knowledge was stunningly precocious, it was also fragmentary and disjointed and weirdly overindexed on examples rather than general principles. So fine, I still had something to teach them!

Coming to Epsilon Camp was also an emotional experience for me. When I was 15, I attended Canada/USA Mathcamp 1996, the first year that that camp operated. I might not have gone into research otherwise. Coming from a public high school—from the world of English teachers who mainly cared whether you adhered to the Five Paragraph Format, and chemistry teachers who’d give 0 on right answers if you didn’t write “1 mol / 1 mol” and then cross off both of the moles—I was suddenly thrust, sink or swim, into a course on elliptic curves taught by Ken Ribet, who’d played a major role in the proof of Fermat’s Last Theorem that had just been completed, and a talk on algorithms and complexity by Richard Karp himself, and lectures on number theory by Richard Guy, who had stories from when he knew G. H. Hardy.

Back when I was 15, I got to know George Rubin Thomas, the founding director of Mathcamp … and then, after 29 years, there he was again at Epsilon Camp—the patriarch of a whole ecosystem of math camps—and not only there, but sitting in on my course. Also at Epsilon Camp, unexpectedly, was a woman who I knew well back when we were undergrads at Cornell, both of took taking the theoretical computer science graduate sequence, but who I’d barely seen since. She, as it turned out, was accompanying her 8-year-old son, who got to know my 8-year-old. They played together every day and traded math facts.


It occurred to me that the course I taught, on theoretical computer science, was one of the most accessible I’ve ever done, and therefore more people might be interested. So I advertised on this blog for someone to help me LaTeX up the notes for wider distribution. I was thrilled to find a talented student to volunteer. Alas, because of where that student lives, he needs to stay anonymous for now. I thank him, pray for his safety, and hope to be able to reveal his name in the future. I’m also thrilled to have gotten three great high school students—Ian Ko, Tzak Lau, and Sunetra Rao—to help with the figures. Thanks to them as well.

You can read the notes here [59 pages, PDF]

If you’re curious, here’s the table of contents:

  • Lecture 1: Bits
  • Lecture 2: Gates
  • Lecture 3: Finite Automata
  • Lecture 4: Turing Machines
  • Lecture 5: Big Numbers
  • Lecture 6: Complexity, or Number of Operations
  • Lecture 7: Polynomial vs. Exponential
  • Lecture 8: The P vs. NP Problem
  • Lecture 9: NP-completeness
  • Lecture 10: Foundations of Cryptography
  • Lecture 11: Public-Key Cryptography and Quantum Computing

Happy as always to receive comments and corrections. Enjoy!

The ”JVG algorithm” is crap

Saturday, March 7th, 2026

Sorry to interrupt your regular programming about the AI apocalypse, etc., and return to the traditional beat of this blog’s very earliest years … but I’ve now gotten multiple messages asking me to comment on something called the “JVG (Jesse–Victor–Gharabaghi) algorithm” (yes, the authors named it after themselves). This is presented as a massive improvement over Shor’s factoring algorithm, which could (according to popular articles) allow RSA-2048 to be broken using only 5,000 physical qubits.

On inspection, the paper’s big new idea is that, in the key step of Shor’s algorithm where you compute xr mod N in a superposition over all r’s, you instead precompute the xr mod N’s on a classical computer and then load them all into the quantum state.

Alright kids, why does this not work? Shall we call on someone in the back of the class—like, any undergrad quantum computing class in the world? Yes class, that’s right! There are exponentially many r’s. Computing them all takes exponential time, and loading them into the quantum computer also takes exponential time. We’re out of the n2-time frying pan but into the 2n-time fire. This can only look like it wins on tiny numbers; on large numbers it’s hopeless.

If you want to see people explaining the same point more politely and at greater length, try this from Hacker News or this from Postquantum.com.

Even for those who know nothing about quantum algorithms, is there anything that could’ve raised suspicion here?

  1. The paper didn’t appear on the arXiv, but someplace called “Preprints.org.” Come to think of it, I should add this to my famous Ten Signs a Claimed Mathematical Breakthrough is Wrong! It’s not that there isn’t tons of crap on the arXiv as well, but so far I’ve seen pretty much only crap on preprint repositories other than arXiv, ECCC, and IACR.
  2. Judging from a Google search, the claim seems to have gotten endlessly amplified on clickbait link-farming news sites, but ignored by reputable science news outlets—yes, even the usual quantum hypesters weren’t touching this one!

Often, when something is this bad, the merciful answer is to let it die in obscurity. In this case, I feel like there was a sufficient level of intellectual hooliganism, just total lack of concern for what’s true, that those involved deserve to have this Shtetl-Optimized post as a tiny bit of egg on their faces forever.

Updatez!

Friday, February 20th, 2026
  1. The STOC’2026 accepted papers list is out. It seems to me that there’s an emperor’s bounty of amazing stuff this year. I felt especially gratified to see the paper on the determination of BusyBeaver(5) on the list, reflecting a broad view of what theory of computing is about.
  2. There’s a phenomenal profile of Henry Yuen in Quanta magazine. Henry is now one of the world leaders of quantum complexity theory, involved in breakthroughs like MIP*=RE and now pioneering the complexity theory of quantum states and unitary transformations (the main focus of this interview). I’m proud that Henry tells Quanta that learned about the field in 2007 or 2008 from a blog called … what was it again? … Shtetl-Optimized? I’m also proud that I got to help mentor Henry when he was a PhD student of my wife Dana Moshkovitz at MIT. Before I read this Quanta profile, I didn’t even know the backstory about Henry’s parents surviving and fleeing the Cambodian genocide, or about Henry growing up working in his parents’ restaurant. Henry never brought any of that up!
  3. See Lance’s blog for an obituary of Joe Halpern, a pioneer of the branch of theoretical computer science that deals with reasoning about knowledge (e.g., the muddy children puzzle), who sadly passed away last week. I knew Prof. Halpern a bit when I was an undergrad at Cornell. He was a huge presence in the Cornell CS department who’ll be sorely missed.
  4. UT Austin has announced the formation of a School of Computing, which will bring together the CS department (where I work) with statistics, data science, and several other departments. Many of UT’s peer institutions have recently done the same. Naturally, I’m excited for what this says about the expanded role of computing at UT going forward. We’ll be looking to hire even more new faculty than we were before!
  5. When I glanced at the Chronicle of Higher Education to see what was new, I learned that researchers at OpenAI had proposed a technical solution, called “watermarking,” that might help tackle the crisis of students relying on AI to write all their papers … but that OpenAI had declined to deploy that solution. The piece strongly advocates a legislative mandate in favor of watermarking LLM outputs, and addresses some of the main counterarguments to that position.
  6. For those who can’t get enough podcasts of me, here are the ones I’ve done recently. Quantum: Science vs. Mythology on the Peggy Smedley Show. AI Alignment, Complexity Theory, and the Computability of Physics, on Alexander Chin’s Philosophy Podcast. And last but not least, What Is Quantum Computing? on the Robinson Erhardt Podcast.
  7. Also, here’s an article that quotes me entitled “Bitcoin needs a quantum upgrade. So why isn’t it happening?” Also, here’s a piece that interviews me in Investor’s Business Daily, entitled “Is quantum computing the next big tech shift?” (I have no say over these titles.)

Luca Trevisan Award for Expository Work

Friday, February 6th, 2026

Friend-of-the-blog Salil Vadhan has asked me to share the following.


The Trevisan Award for Expository Work is a new SIGACT award created in memory of Luca Trevisan (1971-2024), with a nomination deadline of April 10, 2026.

The award is intended to promote and recognize high-impact work expositing ideas and results from the Theory of Computation. The exposition can have various target audiences, e.g. people in this field, people in adjacent or remote academic fields, as well as the general public. The form of exposition can vary, and can include books, surveys, lectures, course materials, video, audio (e.g. podcasts), blogs and other media products. The award may be given to a single piece of work or a series produced over time. The award may be given to an individual, or a small group who together produced this expository work.

The awardee will receive USD$2000 (to be divided among the awardees if multiple), as well as travel support if needed to attend STOC, where the award will be presented. STOC’2026 is June 22-26 in Salt Lake City, Utah.

The endowment for this prize was initiated by a gift from Avi Wigderson, drawing on his Turing Award, and has been subsequently augmented by other individuals.

For more details see here.

Quantum is my happy place

Wednesday, January 28th, 2026
  • Here’s a 53-minute podcast that I recorded this afternoon with a high school student named Micah Zarin, and which ended up covering …[checks notes] … consciousness, free will, brain uploading, the Church-Turing Thesis, AI, quantum mechanics and its various interpretations, quantum gravity, quantum computing, and the discreteness or continuity of the laws of physics. I strongly recommend 2x speed as usual.
  • QIP’2026, the world’s premier quantum computing conference, is happening right now in Riga, Latvia, locally organized by a team headed by the great Andris Ambainis, who I’ve known since 1999 and who’s played a bigger role in my career than almost anyone else. I’m extremely sorry not to be there, despite what I understand to be the bitter cold. Family and teaching obligations mean that I jet around the world so much less than I used to. But many of my students and colleagues are there, and I’ll plan a blog post on news from QIP next week.
  • Greg Burnham of Epoch AI tells me that Epoch has released a list of AI-for-math challenge problems—i.e., open math problems that are below the level of P vs. NP and the Riemann Hypothesis but still of very serious research interest, and that they’re putting forward as worthy targets right now for trying to solve with AI assistance. A few examples that should be familiar to some Shtetl-Optimized readers: degree vs. sensitivity of Boolean functions, improving the constant in the exponent of the General Number Field Sieve, giving an algorithm to test whether a knot has unknotting number of 1, and extending Apéry’s proof of the irrationality of ζ(3) to other constants. Notably, for each problem, alongside a beautifully written description by a (human) expert, they also show you what the state-of-the-art models were able to do on that problem when they tried.
  • There’s been a major advance in understanding constant-depth quantum circuits, by my former PhD student Daniel Grier (now a professor at UCSD), along with his PhD student Jackson Morris and Kewen Wu of IAS. Namely, they show that any function computable in TC0 (constant-depth, polynomial-size classical circuits with threshold gates) is also computable in QAC0 (constant-depth quantum circuits with 1-qubit and generalized Toffoli gates), as long as you provide many copies of the input. Two examples of such TC0 functions, which we therefore now know to be in QAC0 given many copies of the input, are Parity and Majority. It’s been a central open problem of quantum complexity theory for a quarter-century to prove that Parity is not in QAC0, complementing the celebrated result from the 1980s that Parity is not in classical AC0 (a constant-depth circuit class that, for all we know, might be incomparable with QAC0). It’s known that showing Parity∉QAC0 is equivalent to showing that QAC0 can’t implement the “fanout” function, which makes many copies of an input bit. To say that we’ve gained a new understanding of why this problem is so hard would be an understatement.